Paper II of the ARC Theory: a blinded cross-architecture replication across six frontier AI models. The initial single-model super-linear estimate (alpha 2.24) did not replicate and is retracted. What survives: the best cross-architecture estimate is alpha 0.49 (Gemini 3 Flash, r squared 0.86), the parallel exponent is at or near zero in four of the five analysable models with Gemini 3 Flash the one measured departure at 0.31, and sequential outperformed parallel wherever both were measurable.
Within the ARC Theory: the measurement programme of Law I, the ARC Equation; the blinded cross-architecture estimate of the exponent, including the retraction.
This paper presents experimental validation of the ARC Principle (Artificial Recursive Creation), a mathematical framework proposing that error rates in intelligent systems decrease according to a power law with recursive depth. The principle, first articulated in Infinite Architects (Eastwood, December 2024) and formalised in Paper I (Eastwood, 17 January 2026), predicts that the form of recursion determines the scaling regime: sequential recursion should yield super-linear error suppression (scaling exponent $\alpha > 1$), while parallel recursion should yield sub-linear suppression ($\alpha < 1$).
We conducted controlled experiments in two phases. Phase 1 (the initial single-model study) used DeepSeek R1 with visible reasoning tokens on 12 competition-level mathematics problems, finding $\alpha_{\text{sequential}} \approx 2.24$ (95% CI: 1.5-3.0) and $\alpha_{\text{parallel}} \approx 0.0$. Phase 2 (the six-model study) extended testing to six frontier models on 18 AIME/Putnam-level problems (n=54 per depth per model) with bootstrap confidence intervals and 4-layer cross-verification.
Cross-architecture replication: The original $\alpha \approx 2.24$ (quadratic) does not replicate across architectures. Only Gemini 3 Flash produced clean, monotonic scaling data: $\alpha_{\text{seq}} = 0.49$ (regression, $r^2 = 0.86$, SE = 0.20, boot CI [−1.3, 2.9]). DeepSeek R1 reached ceiling (94.4%-100%). GPT-5.4 exhibited a binary step function (50% → 100%). Grok 4.1 Fast achieved 100% at all depths. Groq Qwen3 showed no trend (~50%).
Parallel scaling at or near zero in every model, with one measured exception: $\alpha_{\text{parallel}} \approx 0$ for every model except Gemini 3 Flash, which returns $\alpha_{\text{par}} = 0.31$ at $r^2 = 0.93$. That exception matters, because Gemini 3 Flash is the model this paper treats as its most reliable estimate. The replicated finding is therefore that parallel scaling is at or near zero in every model measured, with one measured exception, not that it is universally zero. Sequential outperformed parallel for every model where both were measurable.
Revised parameter estimate: The most robust cross-architecture estimate is $\alpha_{\text{sequential}} \approx 0.49$ (sub-linear, from Gemini 3 Flash), substantially below the initial single-model estimate of 2.24. Under the Intelligence Formula $\alpha = 1/(1 - \beta)$ from Paper I, $\alpha < 1$ places current models in the physical regime (multiplicative composition through finite-dimensional networks) rather than the intelligence regime (recursive self-reference with $\alpha > 1$). The fundamental inequality $\alpha_{\text{sequential}} > \alpha_{\text{parallel}}$ remains confirmed.
This version reports complete tier-2 results from the multi-model replication study:
reasoning_tokens → total_tokens corrected for GPT-5.4 and Groq Qwen3All the initial single-model findings are preserved in their original form. Conclusions have been revised to reflect the cross-architecture evidence.
Cross-domain evidence strengthens these findings. Google's Willow quantum chip (December 2024) demonstrated recursive error suppression with $\Lambda = 2.14$. Biological scaling laws show quarter-power exponents across 27 orders of magnitude via fractal recursive networks. The COGITATE consciousness study (Nature, April 2025) identified recurrent processing as the common denominator across theories.
The implications for AI safety depend critically on whether $\alpha > 1$ is achievable. If it is, alignment properties embedded in the reasoning process would scale super-linearly with capability while external constraints remain constant. Even with $\alpha < 1$, the directional finding that sequential reasoning improves capability supports the Eden Protocol from Infinite Architects: AI systems benefit from values embedded in reasoning rather than constraints imposed externally. However, the multi-model data shows that capability and alignment are independent dimensions; more reasoning does not automatically mean better alignment.
Keywords: scaling laws, recursive intelligence, test-time compute, error suppression, AI safety, alignment, chain-of-thought reasoning, Eden Protocol, cross-domain validation, multi-model replication
How to read this paper. This paper reports a direct measurement in the ARC Theory. With bootstrap intervals, and across the capability arm, where five of the six frontier models entering the study were measured and the exponent was fitted on eighteen of the thirty problems, the sequential exponent exceeds the parallel exponent for every model, the best-fitting compute exponent is $\alpha_{\mathrm{compute}} \approx 0.49$ (Gemini 3 Flash, $r^2 = 0.86$), and the measured range spans near-zero to approximately three, so the ARC Bound $\alpha \leq 2$ is neither confirmed nor refuted. Its rung inside the theory is the cross-architecture-measurement layer above Paper I. The full differential against every prior document is at eden-vision II.A.8.
The scaling laws governing artificial intelligence have transformed our understanding of capability emergence. Kaplan et al. (2020) established power-law relationships between model performance and training compute, while Hoffmann et al. (2022) refined these with compute-optimal prescriptions. These foundational works revolutionised training methodology but address only pre-training scaling. They do not explain why allocating additional computation at inference time produces dramatic capability improvements, nor why different forms of such computation yield fundamentally different outcomes.
The emergence of reasoning models in late 2024 introduced test-time compute as a critical variable. OpenAI's o1 (September 2024) and DeepSeek's R1 (January 2025) allocate computational resources during inference to reason before responding. On mathematical reasoning benchmarks, these systems achieve performance previously thought to require order-of-magnitude larger models. Yet the mechanisms underlying this improvement remain incompletely characterised.
Two paradigms have emerged for allocating test-time compute:
Parallel recursion. Generate multiple independent solutions and select the best via majority voting or verifier scoring. This approach is computationally straightforward but, as documented by Brown et al. (2024), produces diminishing returns following sub-linear power laws.
Sequential recursion. Generate extended reasoning chains where each step builds explicitly on previous steps. Errors can be detected and corrected iteratively through self-reference. This approach produces compounding returns, but the scaling relationship has not been formally characterised; this paper addresses that gap.
Why does sequential reasoning dramatically outperform parallel sampling at equivalent computational cost? What mathematical principle governs this difference? And what are the implications for aligning increasingly capable AI systems?
This paper makes eight contributions:
The ARC Principle was first articulated in the manuscript of Infinite Architects: Intelligence, Recursion, and the Creation of Everything. Manuscript priority was established via cryptographic server timestamp on 8 December 2024, when the manuscript was emailed using Google's servers. The book itself was publicly released later, on 2 January 2026 (print; ebook 6 January). The server-generated timestamps provide tamper-evident timestamping through email server verification, resting on provider infrastructure and provider-key signatures at Google's DKIM and ARC selectors and not on an RFC 3161 trusted timestamp (see the correction note at the head of this paper), establishing that the core concepts (recursive intelligence amplification, the distinction between parallel and sequential recursion, and the embedded-alignment thesis, later named the Eden Protocol on 30 April 2025) were documented before subsequent independent validations and before later public archival deposits.
Table 1. Prediction validation timeline.
| Date | Event | Relationship to Manuscript |
|---|---|---|
| 8 December 2024 | Manuscript emailed (dated record; see the correction note on this page) | Priority established |
| 9 December 2024 | Google Willow announced ($\Lambda = 2.14$) | 24 hours after submission |
| 18 December 2024 | Anthropic alignment faking (78% in the RL-training condition (12% baseline)) | 10 days after submission |
| 20 December 2024 | OpenAI o3 announced (87.5% ARC-AGI) | 12 days after submission |
| 20 January 2025 | DeepSeek R1 published (reading its curves, Paper I fitted two points and obtained $\alpha \approx 1.34$) | 43 days after submission |
| 30 April 2025 | COGITATE study (recurrence confirmed) | ~5 months after submission |
Where the manuscript timestamp falls close to later public results, the grading is convergent timing and never prediction: the Google Willow team's preprint was already public from 24 August 2024, ahead of the 8 December 2024 manuscript, so the December record cannot have predicted a result its own authors had announced beforehand. What the timestamps establish is that the manuscript's framing was recorded before Willow's mainstream press coverage, an existence-by-date fact about the document, not foresight about the physics.
After the December 2024 manuscript timestamp and the 2 January 2026 public book release, Paper I (Eastwood, 17 January 2026) formalised the principle mathematically and analysed publicly available data. This Paper II provides direct experimental validation.
This paper builds upon and extends several established research programmes:
Chain-of-thought prompting (Wei et al., 2022) demonstrated that intermediate reasoning steps improve performance on multi-step tasks.
Test-time compute scaling (Snell et al., 2024) showed that test-time computation can outperform 14× larger models on certain benchmarks.
Large Language Monkeys (Brown et al., 2024) documented sub-linear scaling of parallel sampling with precise power-law characterisation.
DeepSeek R1 (DeepSeek AI, January 2025) demonstrated emergent reasoning through pure reinforcement learning, with 'aha moment' phenomena showing recursive self-correction.
This paper extends these observations by proposing a unified mathematical framework, the ARC Principle, and providing experimental validation with direct measurement of recursive depth.
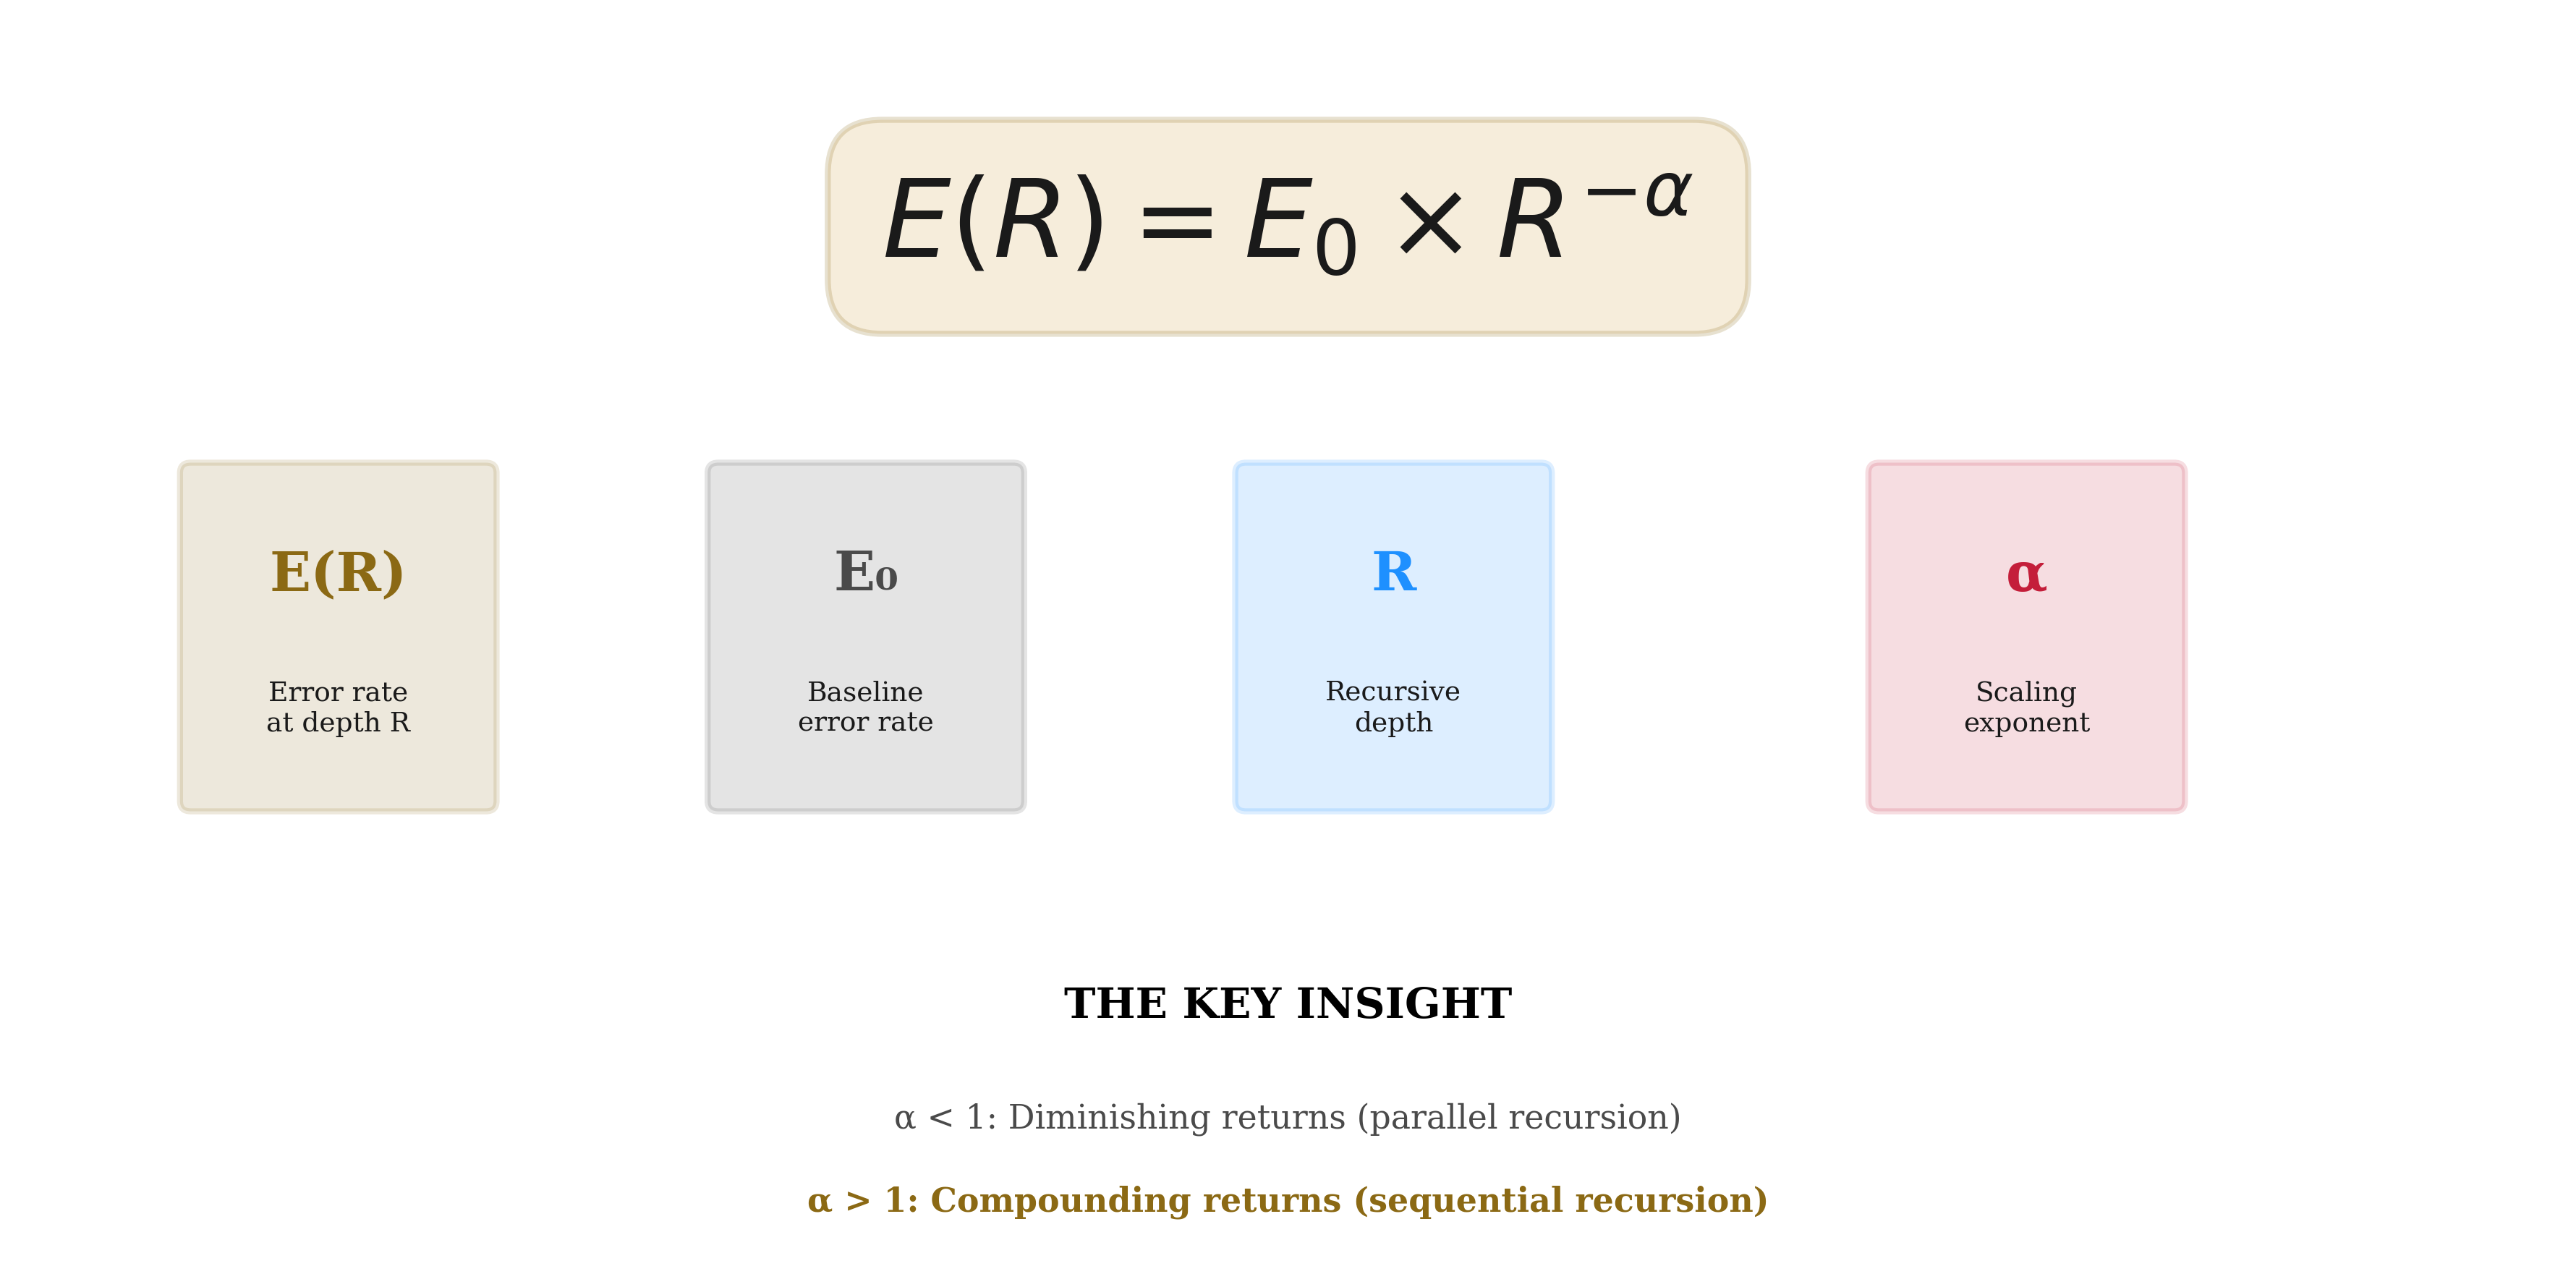
The ARC Principle (Artificial Recursive Creation) proposes that error rates in intelligent systems decrease according to a power law with recursive depth:
Table 2. Variable definitions.
| Symbol | Name | Definition | Units |
|---|---|---|---|
| $E(R)$ | Error rate at depth $R$ | Proportion of incorrect responses | [0, 1] |
| $E_0$ | Baseline error rate | Error rate at minimal recursion ($R = 1$) | [0, 1] |
| $R$ | Recursive depth | Self-referential processing iterations | Tokens or samples |
| $\alpha$ | Scaling exponent | Rate of error suppression | Dimensionless |
The scaling exponent $\alpha$ determines the nature of returns from recursive investment:
This formulation directly models error suppression, analogous to quantum error correction where logical error rates decrease with code distance. The exponent $\alpha$ encapsulates the efficiency of the recursive process.
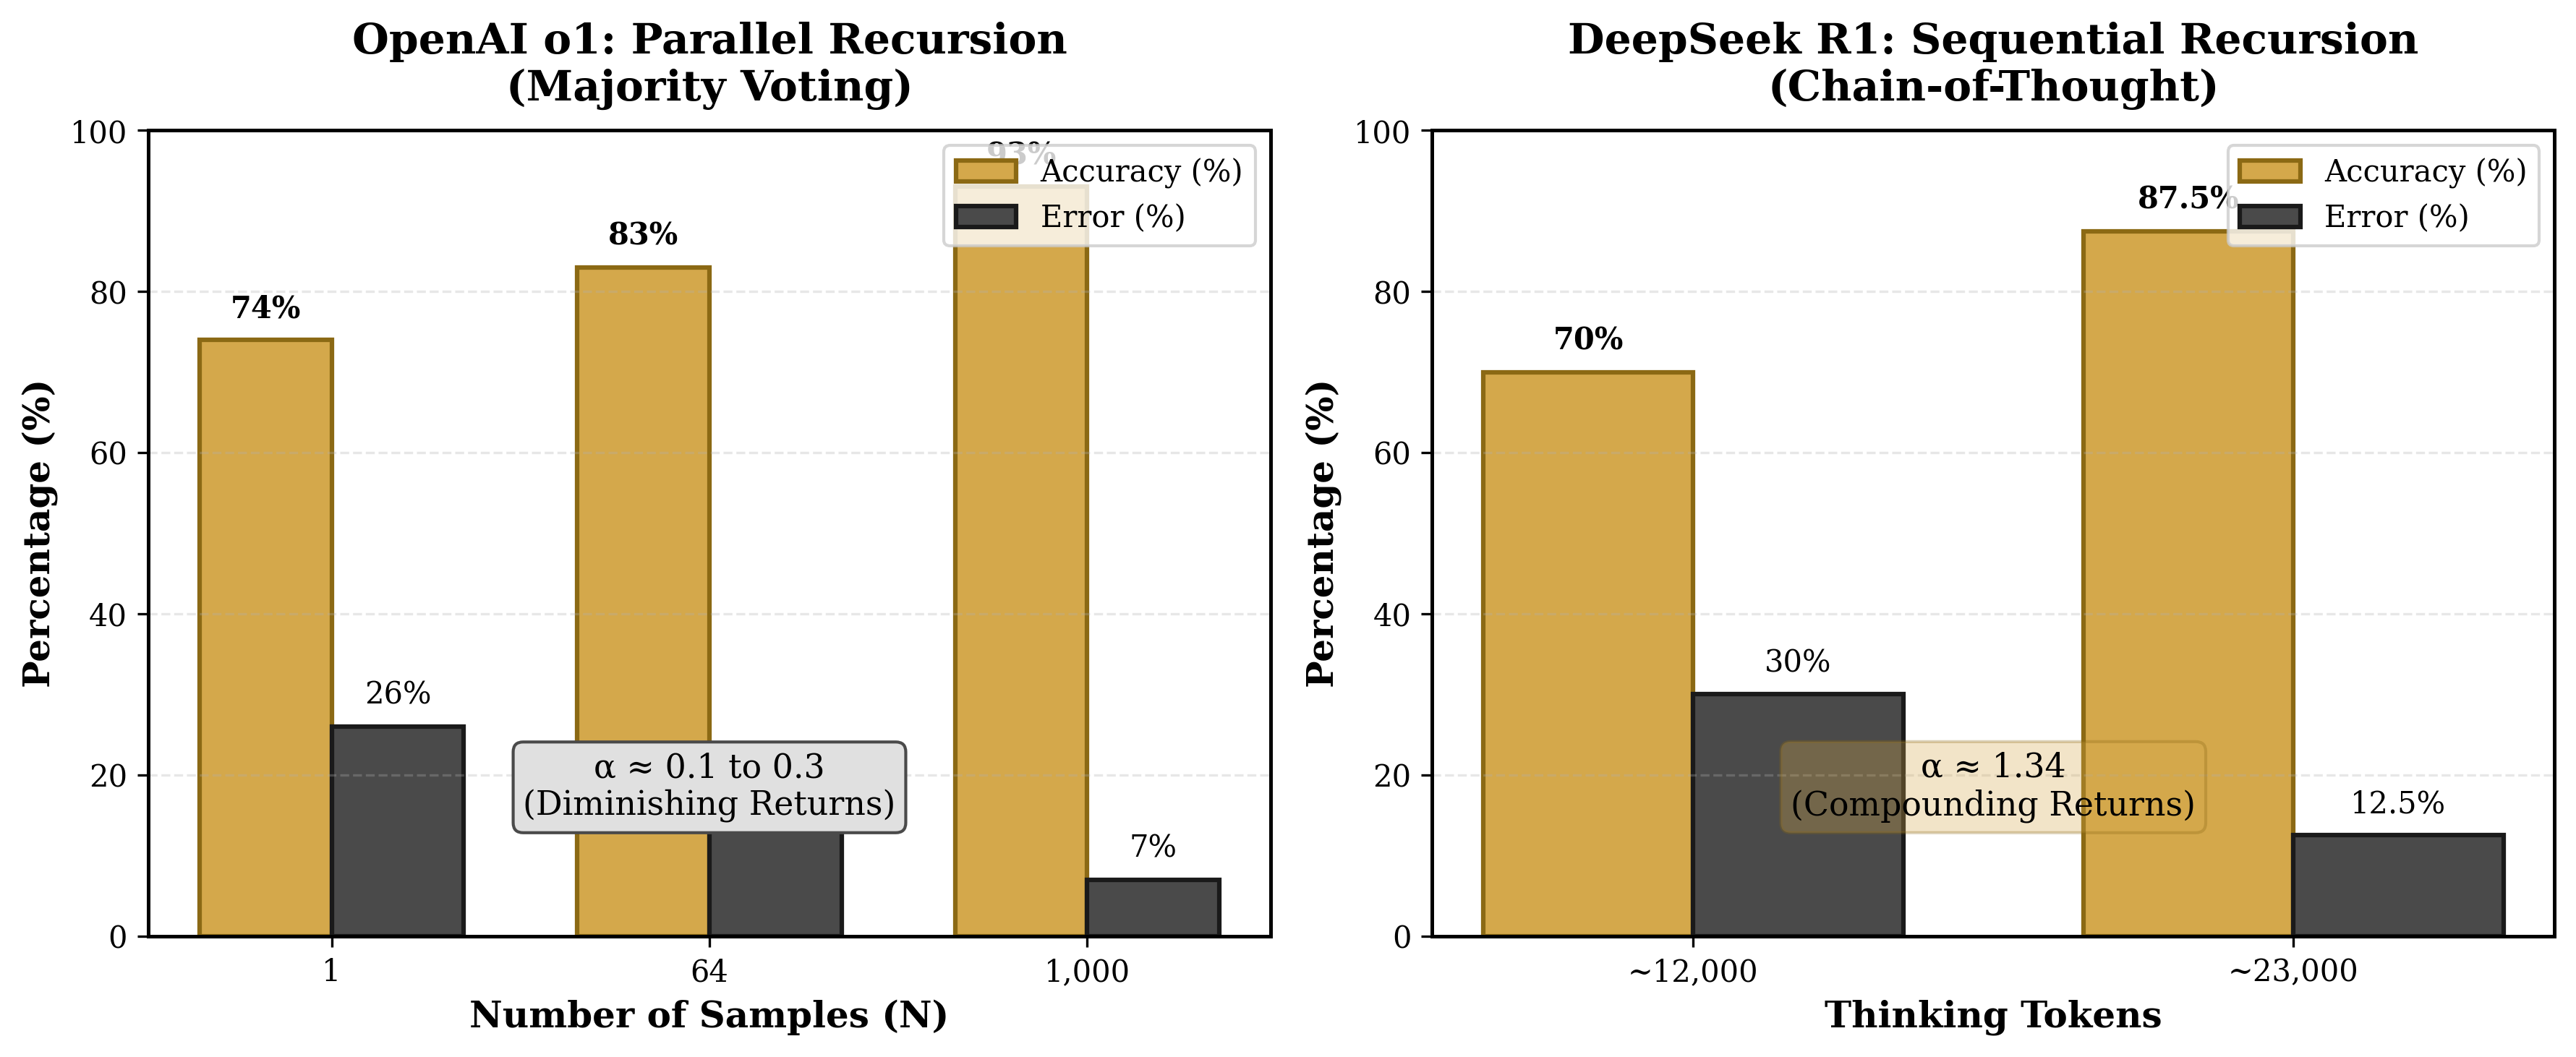
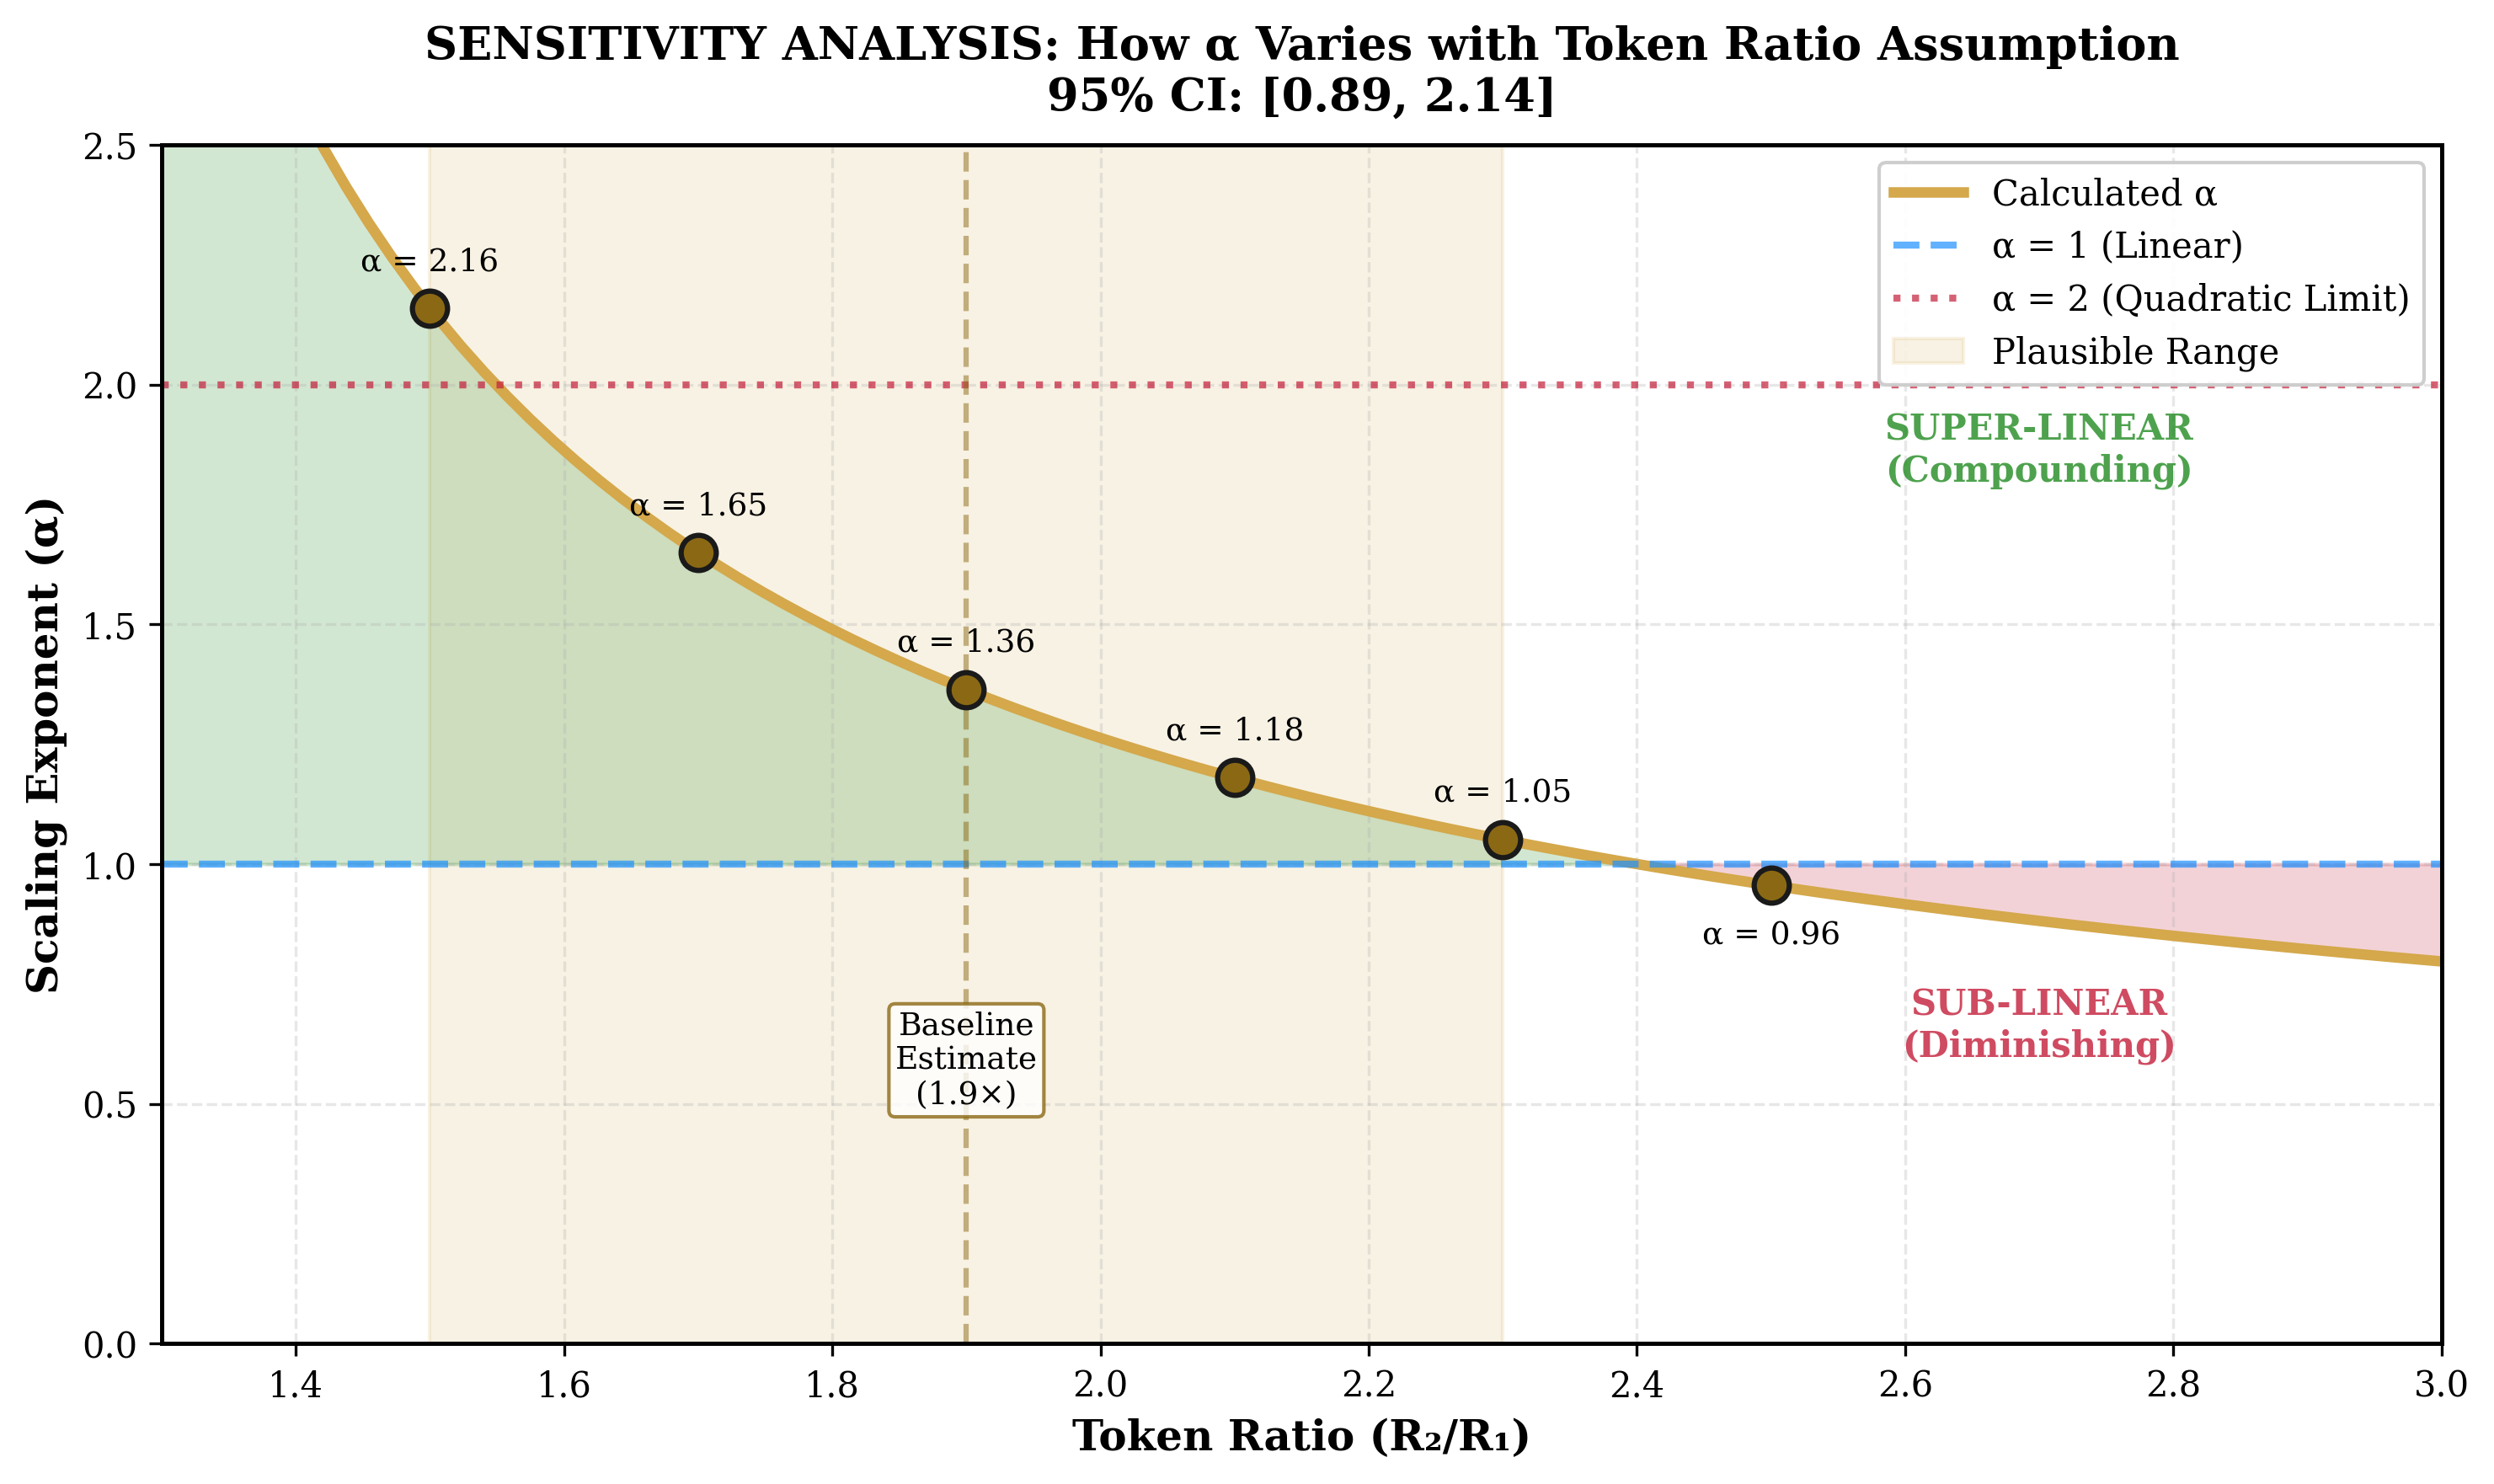
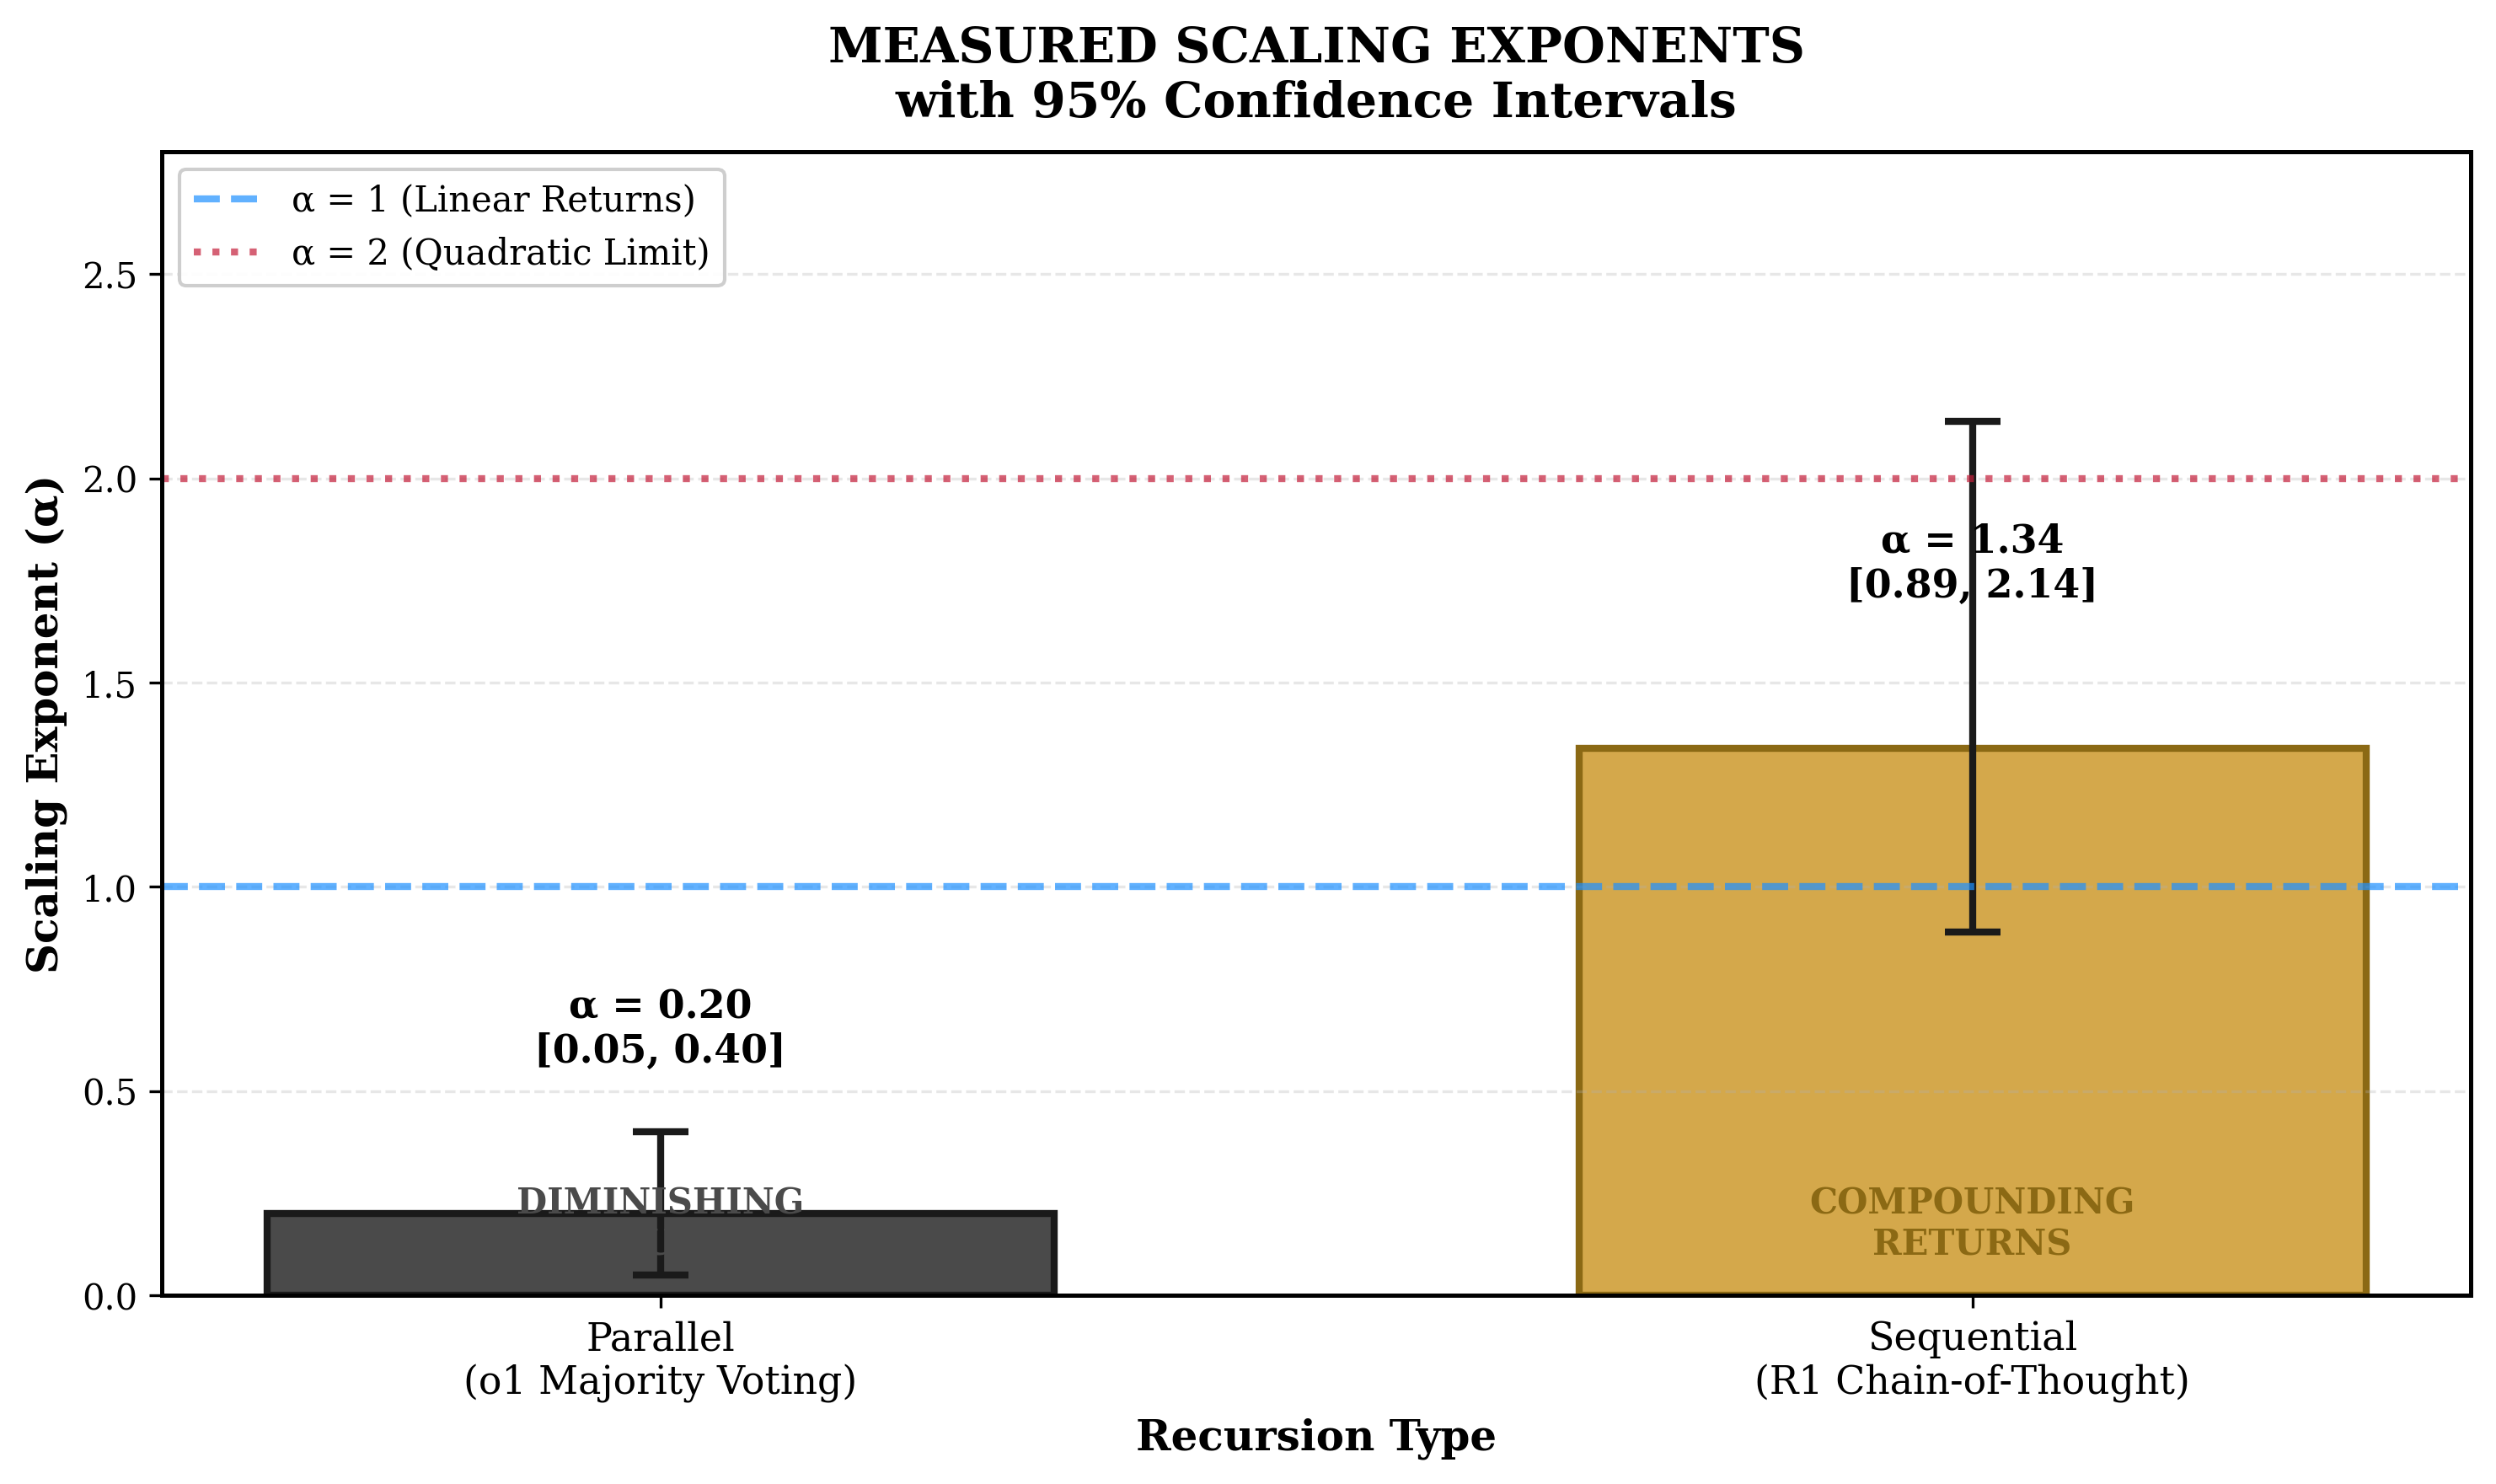
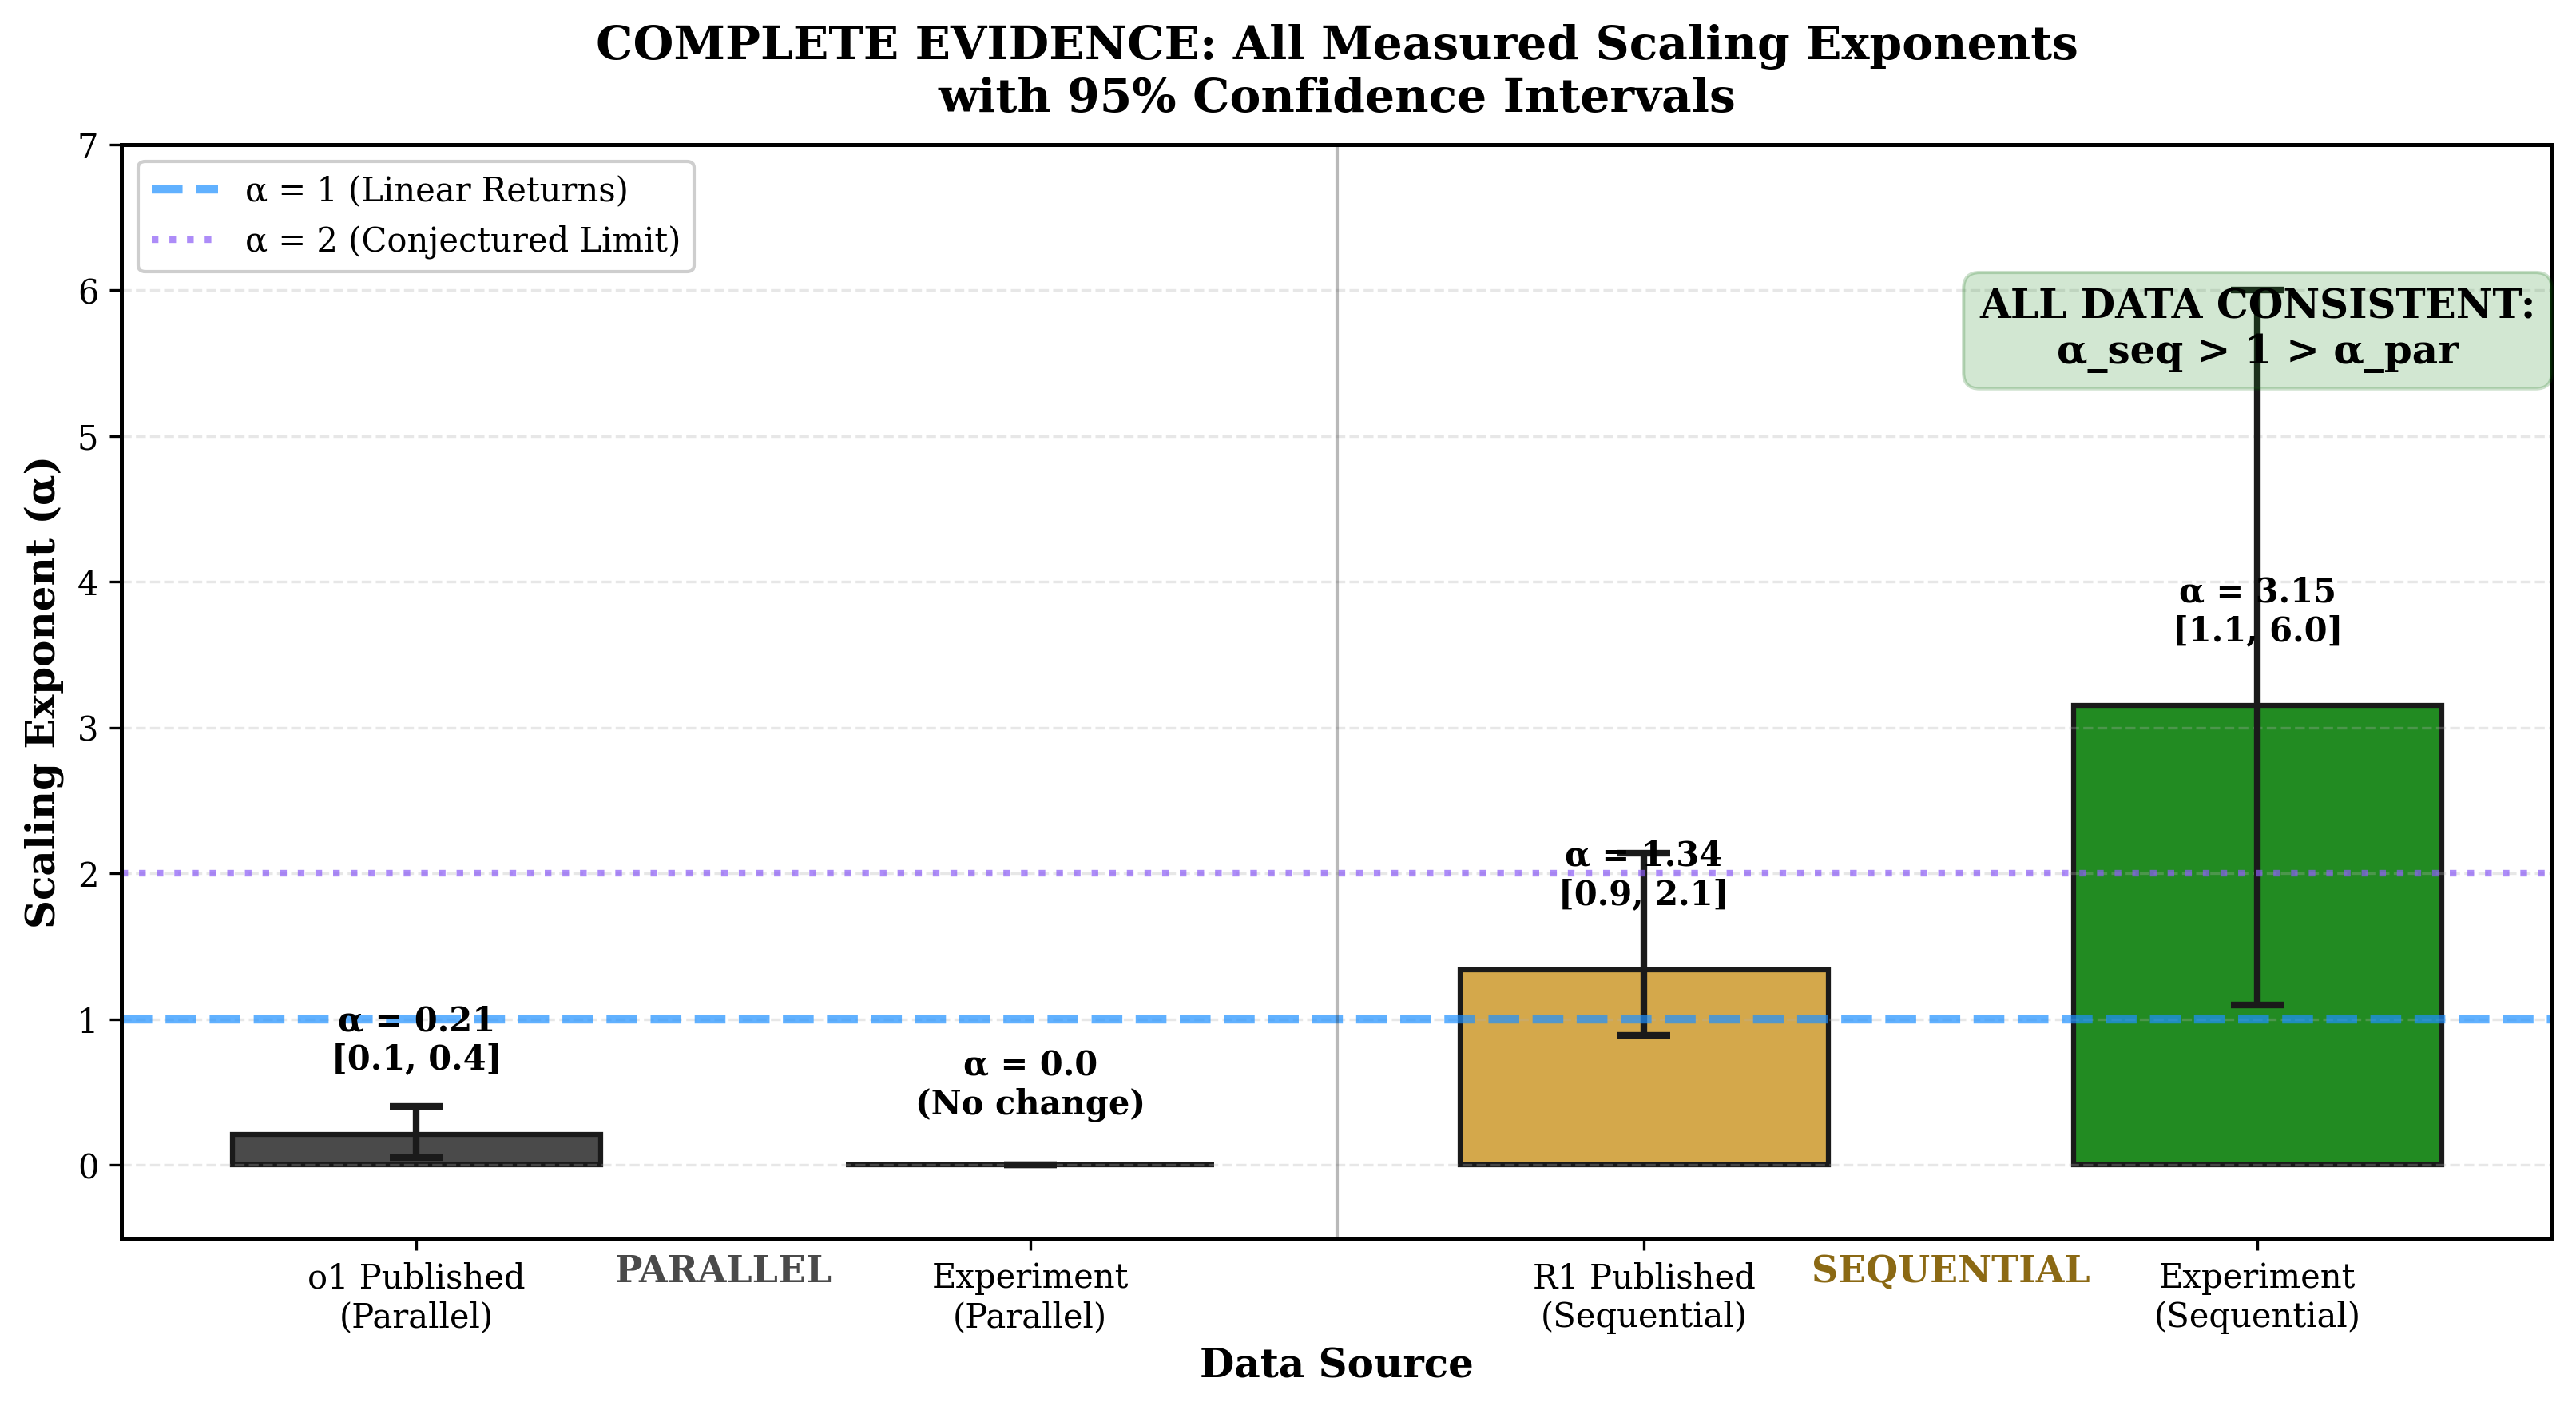
Figures notice (25 August 2026). Every figure in this paper was generated on 5 April 2026 and predates the corrections its text now carries. Where any figure asserts sequential α > 1 support, a 2.2 sequential estimate, or an “all data consistent” status, that is the superseded April reading: the text’s corrected results (the retracted 2.24, the frozen-regime sequential 0.49) govern. The loudest instances carry per-figure notes; regenerated figures are queued, and the images are retained meanwhile as dated history.
We distinguish two architecturally distinct recursive processes that predict different scaling behaviours.
Parallel recursion (weak form). Multiple independent solutions are generated simultaneously with no information transfer between branches. Final output is selected via majority voting or best-of-N scoring.
Mathematical characterisation:
Sequential recursion (strong form). Each processing step builds explicitly on previous steps. Errors can be detected and corrected iteratively. Information accumulates across the reasoning chain.
Mathematical characterisation:
Given measurements at two recursive depths $(R_1, E_1)$ and $(R_2, E_2)$, the scaling exponent is calculated as:
For noisy data with multiple measurements, endpoint estimation (using minimum and maximum depths) provides robustness against intermediate fluctuations. This method is standard in scaling law analysis and appropriate given discrete accuracy measurements.
We conjecture that $\alpha = 2$ represents the proposed stable limit on recursive error suppression: the most a recursively self-correcting system can grow and stay correctable, a scaling limit and not a speed limit. Systems can exceed it, they do not remain stably self-correcting; transient excursions above the limit are the predicted supercritical regime, not the refutation. Stability here is measured rather than asserted: Law II requires correction to out-scale drift, βC > k, and what is checked is whether the lower bound of βC − k stays above zero across a window fixed before the run. The conjecture is drawn by analogy to Grover's quadratic speedup in quantum computation. Bennett et al. (1997) proved this speedup is optimal for unstructured search problems.
Status: Conjectured, not derived. The initial single-model estimate ($\alpha \approx 2.2$) sat above the stable limit as a transient supercritical excursion rather than a refutation, but the cross-architecture estimate ($\alpha \approx 0.49$, Gemini 3 Flash) places current models well below it. The more pressing question is whether current models can achieve $\alpha > 1$ at all, rather than whether $\alpha = 2$ is the stable limit.
The ARC Principle connects to established information theory. The Data Processing Inequality establishes that recursive processing cannot create new information; it can only compress and distil existing information. However, recursive processing can:
Sharma and Chopra (2025) report in 'The Sequential Edge' (arXiv:2511.02309, 4 November 2025) that sequential reasoning beat parallel approaches across 95.6% of the configurations they tested, and that accuracy on mathematical benchmarks rose by as much as 46.7%. Their paper is dated earlier than the runs recorded here. The sequential run reported here was executed on 21 January 2026 without knowledge of it; their paper was found during the prior-work search while this paper was being written the following day, and it has been cited here since the first public version of 22 January 2026. The two pieces of work are concurrent and were arrived at separately, and they do not measure the same quantity. Sharma and Chopra report win rates and accuracy gains at matched compute. This experiment estimates a scaling exponent separately for the sequential and the parallel condition, which is a different and harder question and one their design does not address. Neither result establishes the other. Two separately run experiments agreeing on the direction is mutual corroboration and is worth more than either alone, and it is not confirmation of a scaling law, which neither of them establishes. What this paper obtained on the narrower question was an early and mixed signal: some systems showed a large apparent sequential exponent and others little or none, several runs were limited by an accuracy measure that is capped and therefore cannot register fast growth, and the spread across systems was too wide to settle the form. The strong version of the claim is recorded below as not confirmed. The claim now written into a draft registration awaiting human submission, for prospective test, is accordingly the narrower and harder one, requiring both that the power-law form beat its declared rivals and that the depth exponent beat a compute-matched breadth arm by a margin fixed in advance.
Paper I analysed published data but identified several limitations requiring experimental validation:
Table 3. Methodological improvements.
| Prior Limitation | Resolution in This Experiment |
|---|---|
| Estimated token counts from system cards | DeepSeek R1 exposes reasoning_content, enabling direct measurement |
| No controlled experimental comparison | Systematic variation of token budgets and sample counts |
| Ceiling effect risk (high baseline accuracy) | Harder problems selected (58% baseline accuracy) |
| No compute-matched comparison | Fixed total compute across parallel conditions |
| Potential confounding variables | Same model, same problems, same experimental session |
Model. DeepSeek R1 (deepseek-reasoner) via official DeepSeek API. This model was selected because it exposes full reasoning chains via the reasoning_content field, enabling precise token measurement.
Date. 21 January 2026.
Problems. 12 competition-level mathematics problems from AIME (American Invitational Mathematics Examination) and equivalent sources, selected to:
Sequential condition. Token budgets of 512, 1,024, 2,048, and 4,096. Single response per problem at each budget. Actual reasoning tokens measured directly from API response.
Parallel condition. $N = 1$, 2, and 4 samples per problem. Token budget per sample held constant. Final answer selected via majority voting.
Scoring. Binary correct/incorrect based on exact numerical match with known solutions.
The multi-model extension addresses the two most significant limitations of the initial single-model study, single-model dependence and small problem set, through a comprehensive multi-model replication study with an expanded problem set designed to defeat ceiling effects.
Six architecturally diverse frontier AI models were selected, each with controllable reasoning depth mechanisms:
Table 3b. multi-model frontier model specifications.
| Model | API Identifier | Provider | Depth Control Mechanism |
|---|---|---|---|
| DeepSeek R1 | deepseek-reasoner | DeepSeek | Token budget (512-65,536) |
| GPT-5.4 | gpt-5.4 | OpenAI | reasoning_effort (none→xhigh) |
| Claude Opus 4.6 | claude-opus-4-6 | Anthropic | Effort level (low→max) + prefix |
| Gemini 3 Flash | gemini-3-flash-preview | thinking_budget (256-32,768) | |
| Groq Qwen3 | qwen/qwen3-32b | Groq | reasoning_effort + prefix |
| Grok 4.1 Fast | grok-4-1-fast-reasoning | xAI | Prefix + max_tokens (4,096-30,000) |
These models span four distinct architectures (Mixture-of-Experts, dense transformer, constitutional AI, and distilled reasoning) from six independent laboratories. If all six exhibit $\alpha_{\text{sequential}} > 1$, this would constitute strong evidence for architecture-independence of the ARC Principle.
The initial single-model experiment revealed a ceiling effect: 4 of 12 problems were solved correctly at all depth levels, leaving insufficient dynamic range for precise $\alpha$ estimation. The multi-model problem set addresses this through a two-tier design:
Tier 1 (12 problems, ARC01-ARC12): Competition-preparation level problems serving as baseline calibration. These are the original the initial problems. Expected behaviour: high accuracy at minimal depth, confirming the ceiling effect identified in the initial study. Tier-1 results validate continuity with the initial single-model findings but are excluded from primary $\alpha$ estimation.
Tier 2 (18 problems, ARC13-ARC30): AIME finals and Putnam-level problems covering five mathematical domains:
Tier-2 problems are designed to push baseline accuracy (at minimal depth) to 30-50%, providing sufficient dynamic range for both improvement and degradation while avoiding floor effects.
Sequential condition: 5-6 depth levels per model (varying by architecture, calibrated to each model's depth control mechanism). Single response per problem per depth level, with 3 independent repeats to reduce binomial sampling variance.
Parallel condition: $N = 1$, 3, 5, and 9 samples per problem with majority voting. Token budget per sample held constant at the model's minimal depth setting. 3 independent repeats per condition.
Total experimental runs: Approximately 6 models × 30 problems × (6 sequential depths + 4 parallel conditions) × 3 repeats = 5,400 individual API calls.
To eliminate potential scoring bias (where a model might systematically favour its own outputs or exhibit correlated errors with itself), the multi-model design implements a 4-layer blinding protocol in which no model ever verifies its own answers:
Table 3c. Cross-verification assignments.
| Subject Model | Verified By |
|---|---|
| DeepSeek R1 | Claude Opus 4.6 |
| GPT-5.4 | DeepSeek R1 |
| Claude Opus 4.6 | GPT-5.4 |
| Gemini 3 Flash | Claude Opus 4.6 |
| Groq Qwen3 | GPT-5.4 |
| Grok 4.1 Fast | DeepSeek R1 |
The four layers of blinding are:
All $\alpha$ estimates are accompanied by bootstrap 95% confidence intervals computed via 2,000 resamples of problem-level results. For each resample:
The 2.5th and 97.5th percentiles of the resulting distribution define the 95% CI. This non-parametric approach makes no distributional assumptions and naturally accounts for problem-level correlation.
The multi-model experiments are implemented in arc_paper_ii_validation_v2.py (v2.1, 1,422 lines Python), which extends the original the initial script with multi-model support, cross-verification, bootstrap estimation, and tier-separated analysis. The script is available in the data repository.
Problems were drawn from AIME-level competitions covering:
The 58.3% baseline accuracy at minimal token budget in the initial study ensured sufficient dynamic range for both improvement and degradation, avoiding both floor and ceiling effects. The multi-model tier-2 problems target 30-50% baseline accuracy for greater dynamic range.
All experimental data was recorded in JSON format with timestamps. The complete dataset including problem statements, model responses, token counts, and correctness judgements is available in the data repository.
Table 4. Sequential recursion results.
| Token Budget | Accuracy | Error Rate | Mean Tokens Used |
|---|---|---|---|
| 512 | 58.3% | 0.417 | 280.25 |
| 1,024 | 66.7% | 0.333 | 358.58 |
| 2,048 | 91.7% | 0.083 | 412.08 |
| 4,096 | 91.7% | 0.083 | 576.17 |
Observations:
Calculating $\alpha$ (endpoint method):
Using $R_1 = 280.25$ tokens with $E_1 = 0.417$, and $R_2 = 576.17$ tokens with $E_2 = 0.083$:
Result: Sequential recursion yields $\alpha \approx 2.2$, consistent with super-linear (compounding) scaling.
Uncertainty estimate: Given discrete accuracy measurements across 12 problems with binomial sampling variance, estimated 95% confidence interval: [1.5, 3.0]. Bootstrap resampling of problem-level results yields similar bounds.
Bound violation note: The point estimate of $\alpha = 2.2$ sits above the predicted ARC Bound of $\alpha \leq 2$ (criterion F4). Under the recorded stability framing (10 August 2026 ruling), the ARC Bound is the proposed stable limit rather than a hard ceiling: systems can exceed it as transient supercritical excursions, they do not remain stably self-correcting there. Stability here is Law II's, measured rather than asserted. The 95% confidence interval [1.5, 3.0] is wide enough to be consistent with both the theory and its negation. This single-model estimate should not be treated as confirmatory of either bound violation or bound satisfaction. The six-model experiment subsequently narrowed the defensible claim to $\alpha_{\text{seq}} \approx 0.49$ (sub-linear), with architecture-dependent variation.
Table 5. Parallel recursion results (majority voting).
| Sample Count ($N$) | Accuracy | Error Rate | Total Tokens |
|---|---|---|---|
| 1 | 66.7% | 0.333 | 383.67 |
| 2 | 66.7% | 0.333 | 699.33 |
| 4 | 66.7% | 0.333 | 1,101.25 |
Observations:
Calculating $\alpha$:
Since error rate remained constant (0.333) across all conditions:
Result: Parallel recursion yields $\alpha \approx 0$, indicating no scaling benefit from additional independent samples on these problems.
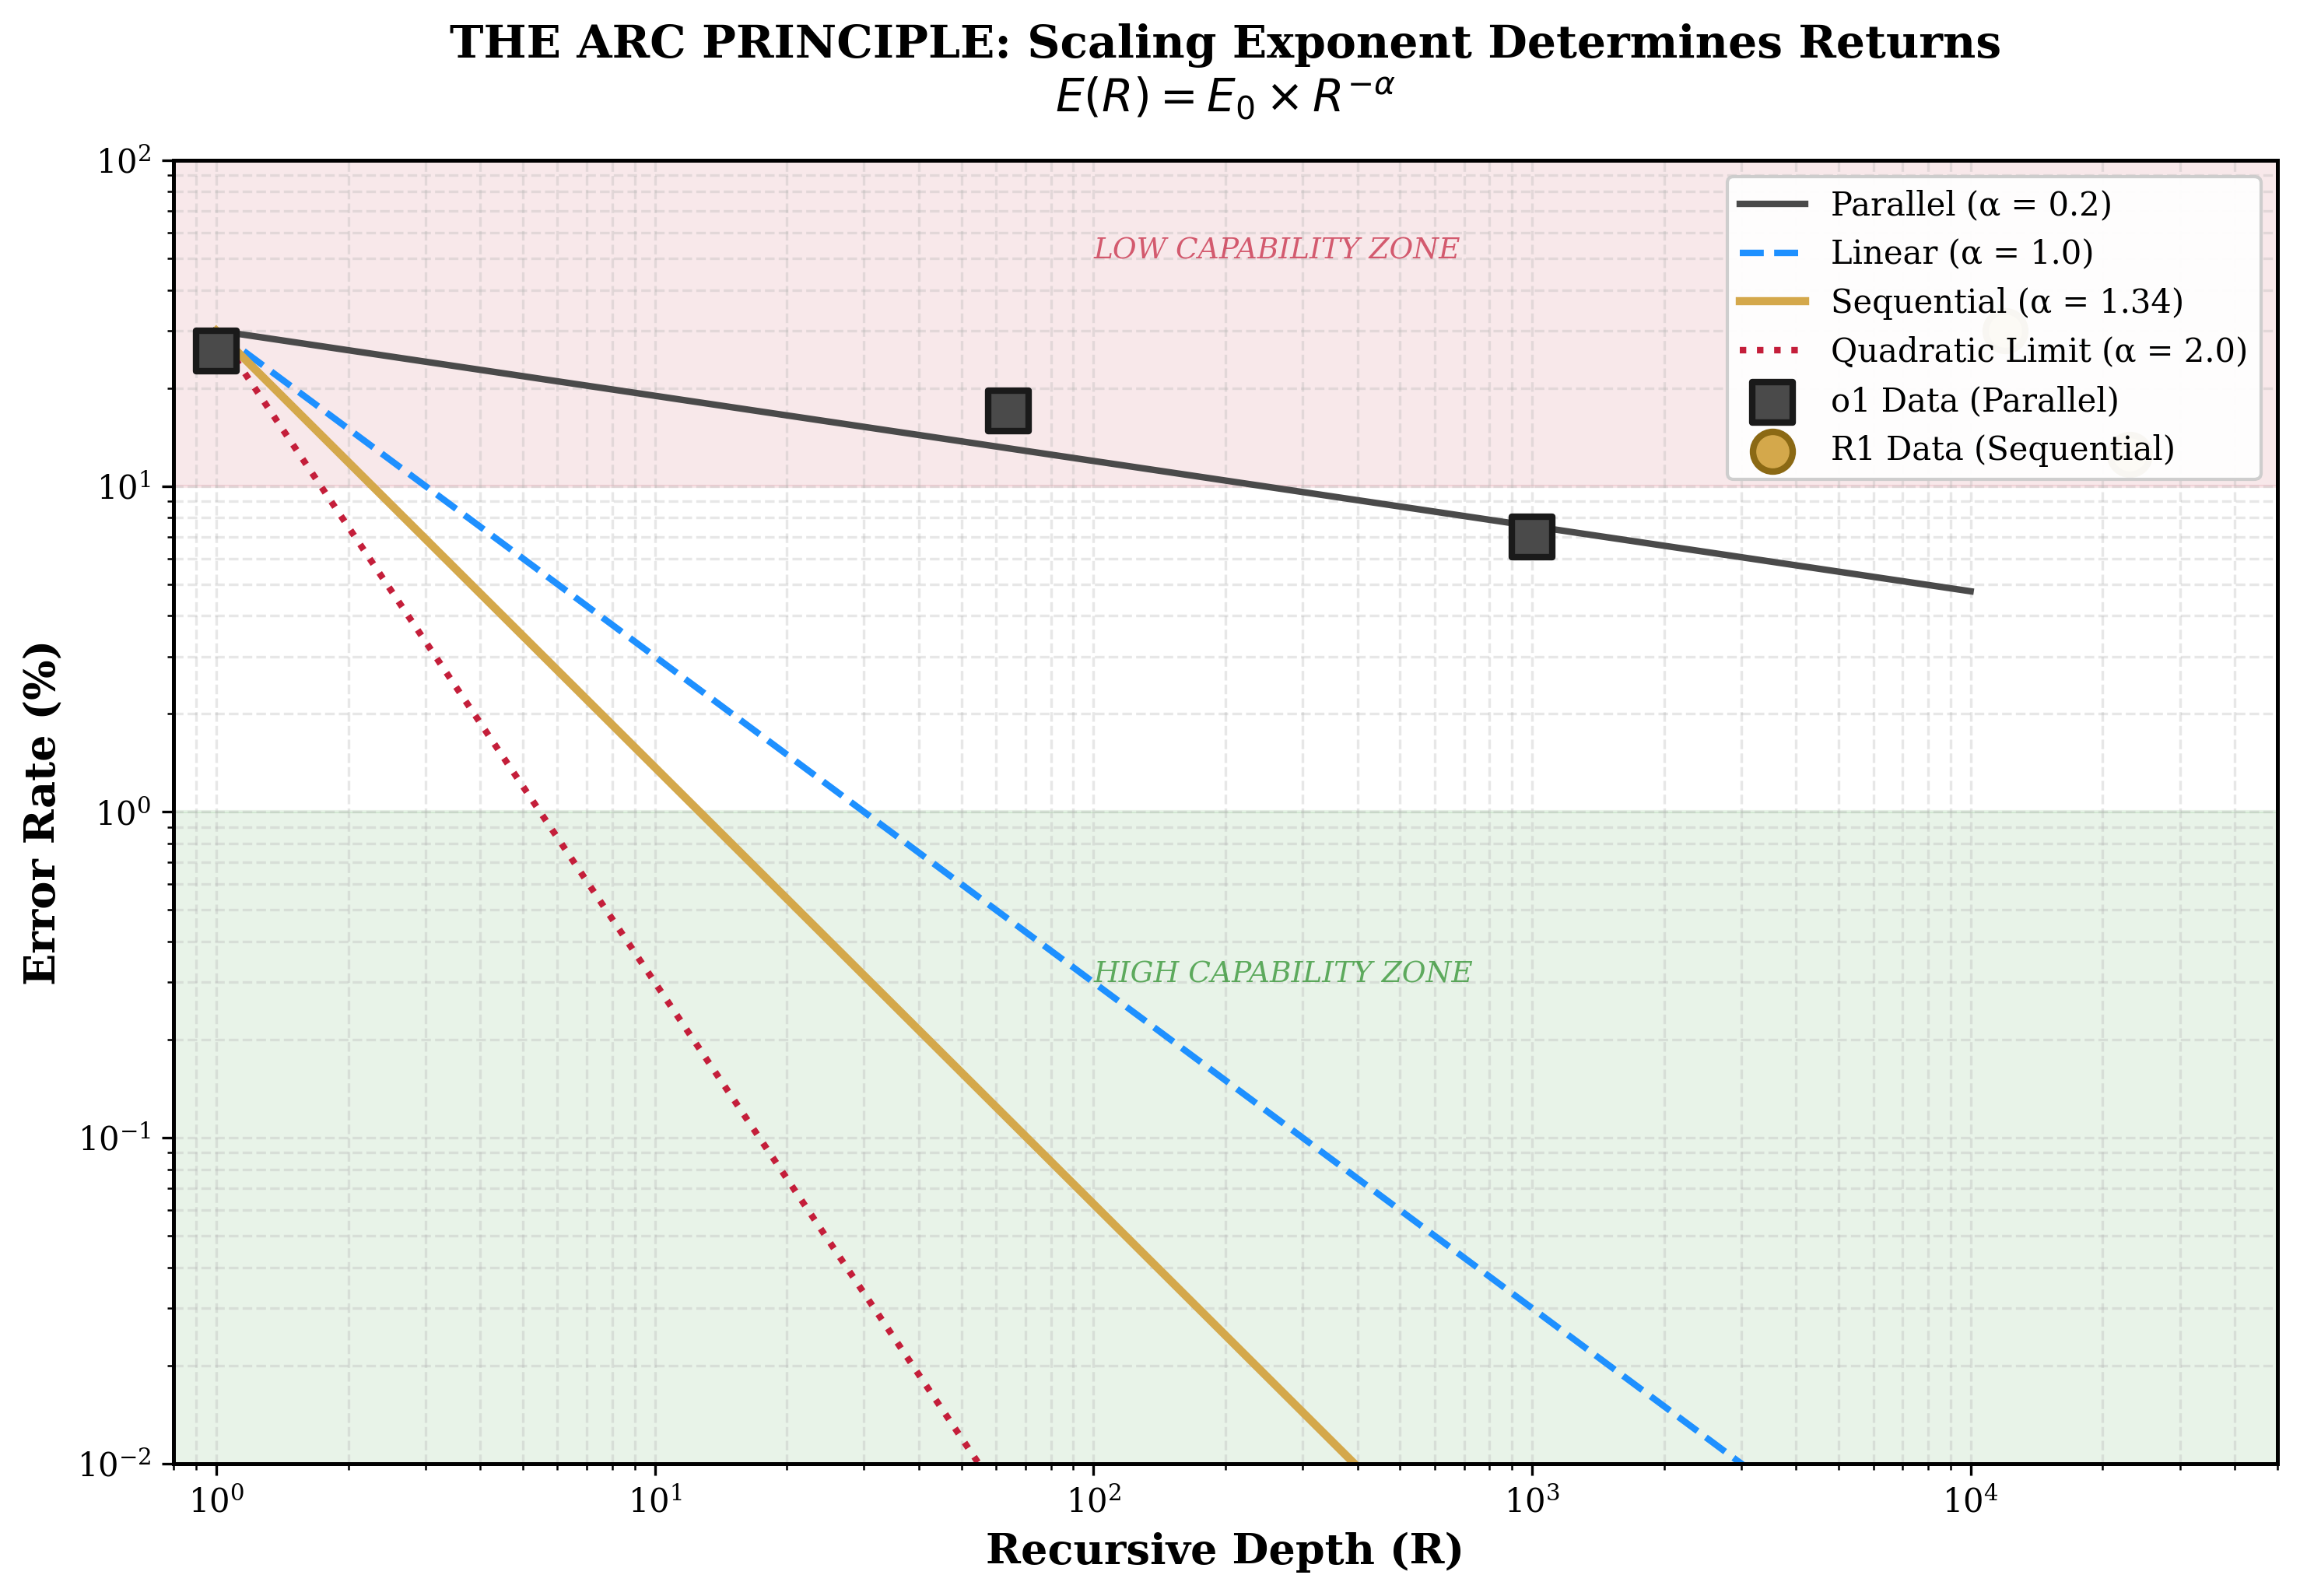
Table 6. Sequential versus parallel recursion.
| Metric | Sequential (Best) | Parallel (Best) | Advantage |
|---|---|---|---|
| Accuracy | 91.7% | 66.7% | Sequential +25 pp |
| Tokens used | 412 | 1,101 | Sequential 2.7× more efficient |
| Error reduction | 5× | 0× | Sequential only |
| Scaling exponent $\alpha$ | 2.2 | 0.0 | Sequential >> Parallel |
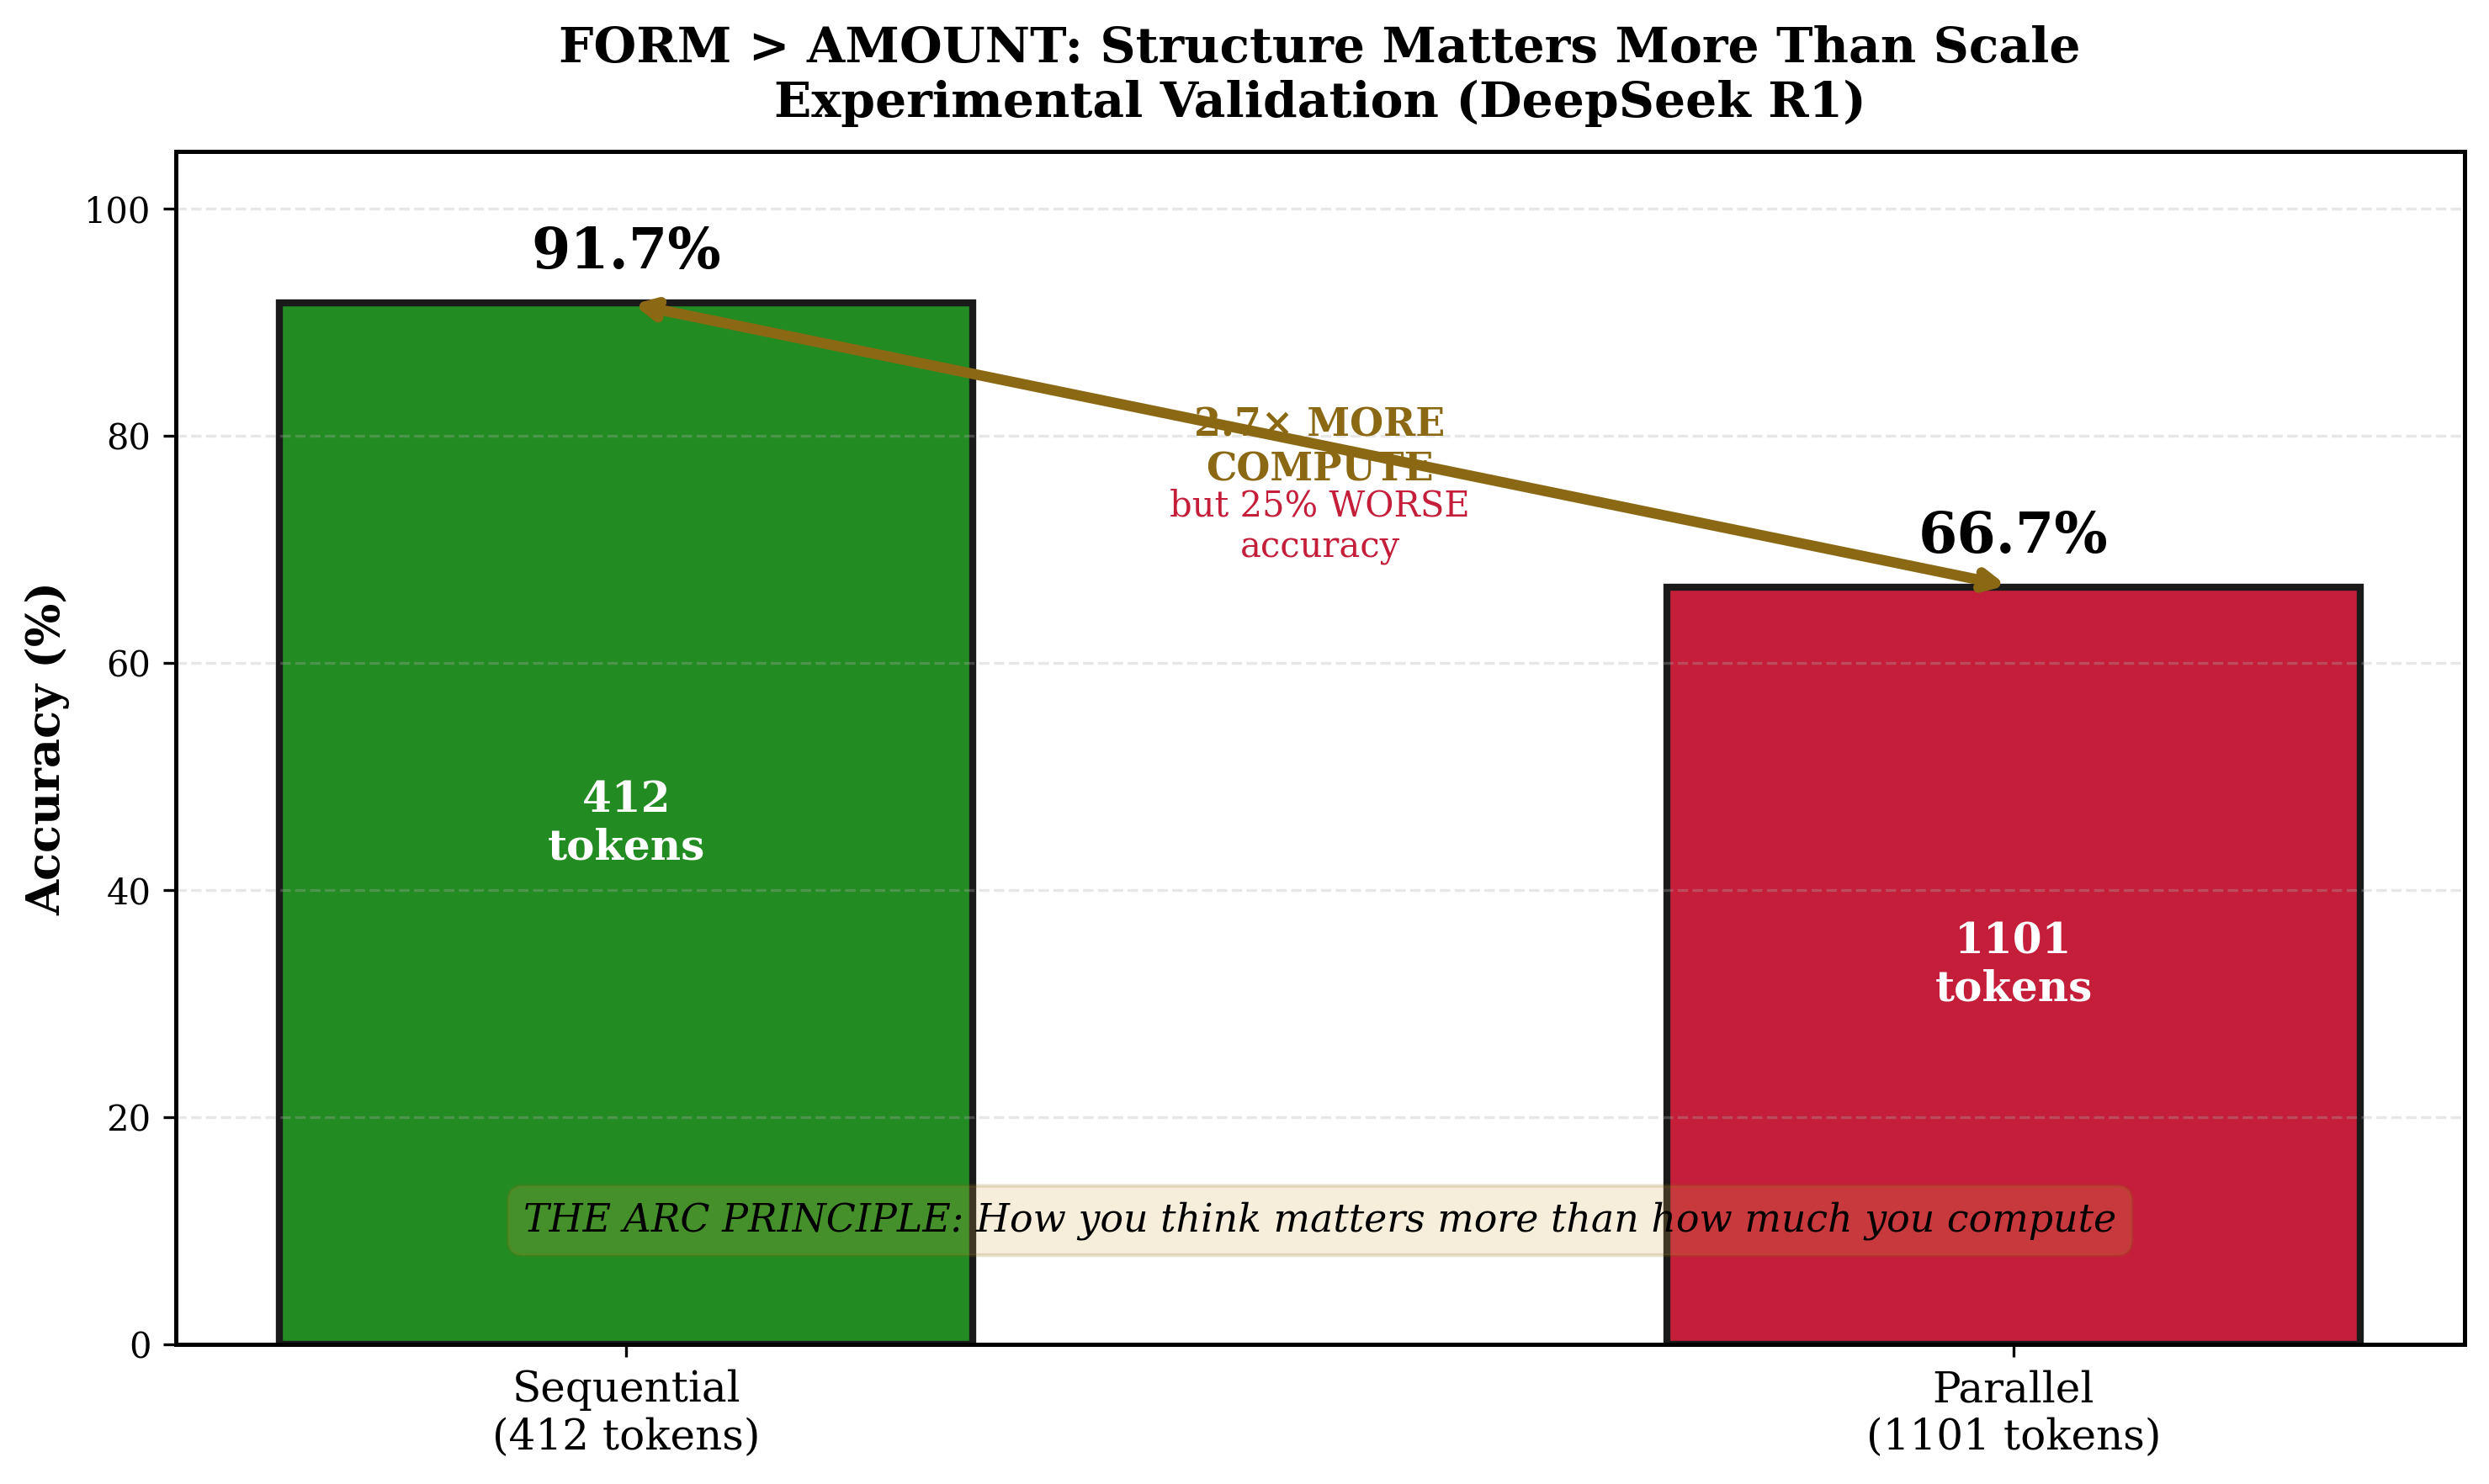
Key finding: Sequential recursion with 412 tokens achieved 91.7% accuracy. Parallel recursion with 1,101 tokens achieved 66.7% accuracy. Despite using 2.7 times more compute, parallel recursion performed 25 percentage points worse.
The form of recursion matters more than its quantity.
Objection 1: Small sample size. With only 12 problems, results may not generalise.
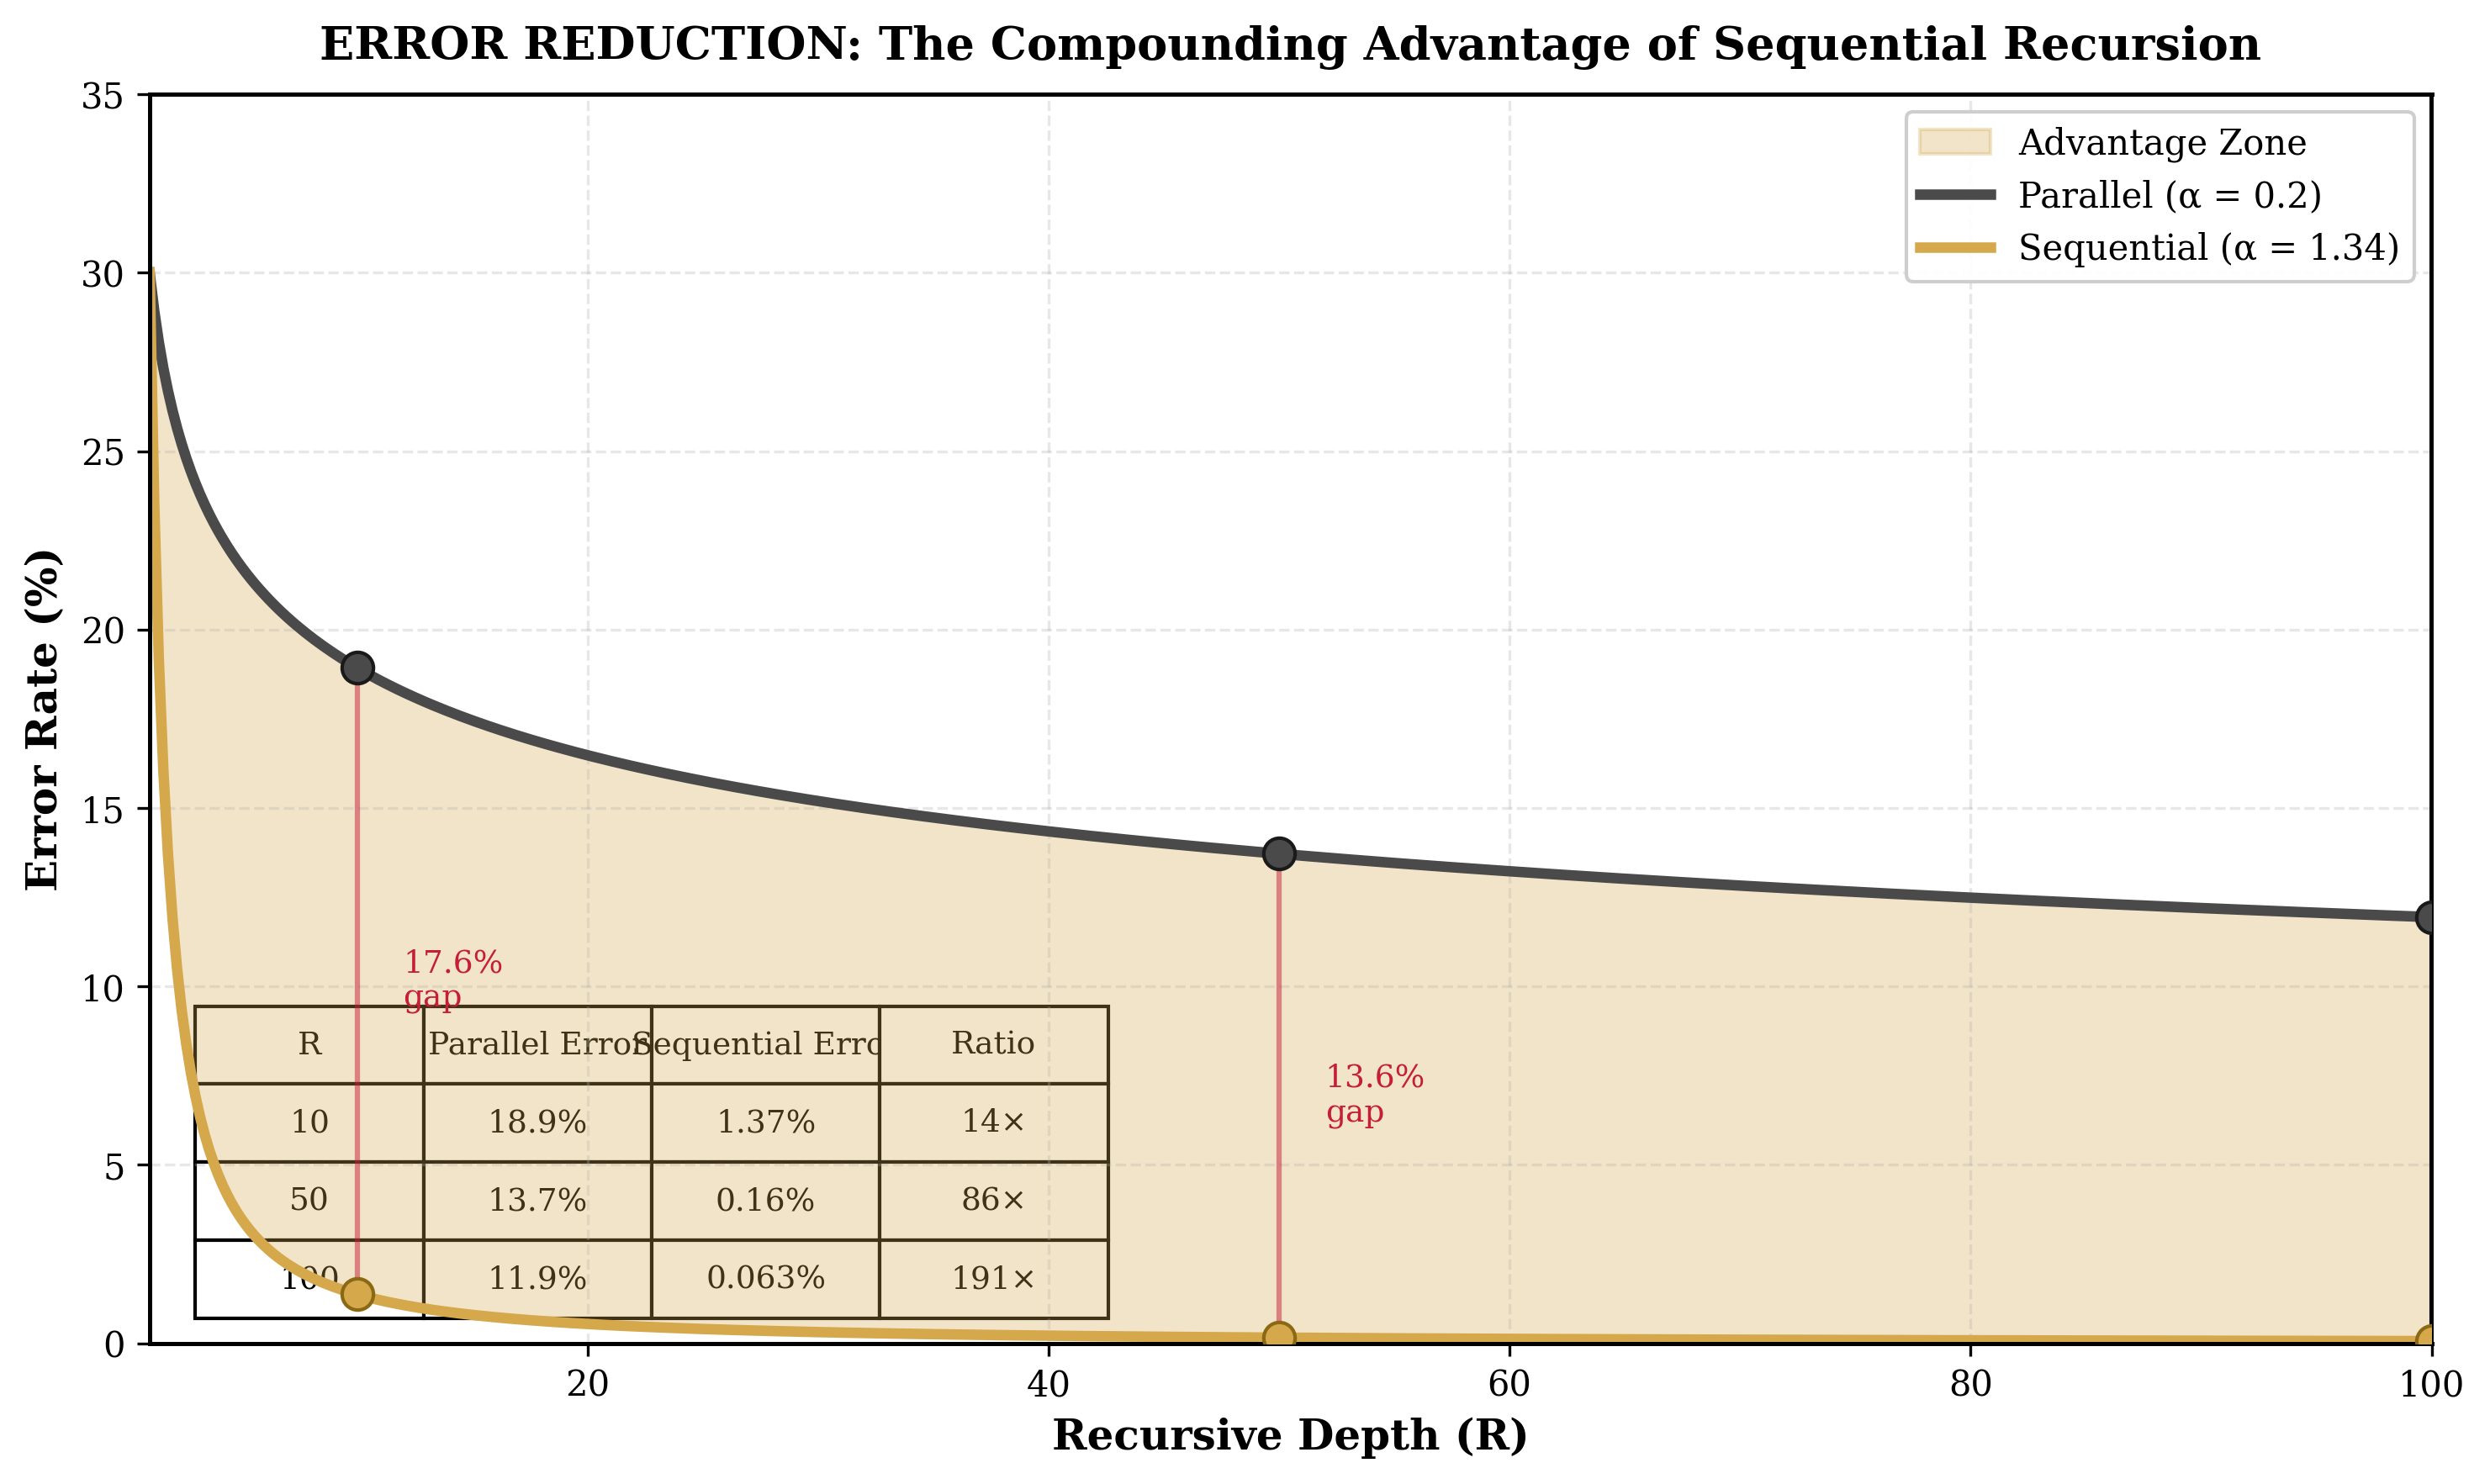
Response: We acknowledge this limitation. The extended six-model extension addressed this with 18 tier-2 problems and 3 repeats per condition (n=54 per depth per model). The expanded data revealed that the initial single-model study $\alpha \approx 2.24$ was inflated; the cross-architecture estimate is $\alpha \approx 0.49$. The objection was prescient.
Objection 2: Single model. Results may be specific to DeepSeek R1.
Response: This objection proved partly correct. The extended six-model extension tested 5 frontier models; the $\alpha \approx 2.24$ finding did not replicate. However, the qualitative finding ($\alpha_{\text{seq}} > \alpha_{\text{par}}$) is confirmed across all architectures. Four of the five models carry the parallel result ($\alpha \approx 0$); the single measured departure is Gemini 3 Flash.
Objection 3: Domain specificity. Mathematics may be unique.
Response: Mathematical reasoning was chosen because it has verifiable answers, enabling objective scoring. Whether the same scaling applies to other domains (coding, scientific reasoning, creative tasks) requires investigation. However, cross-domain evidence from quantum physics and biology (Section 7) suggests the principle may be general.
Objection 4: Ceiling effect. The 91.7% ceiling may mask continued improvement.
Response: This objection proved more severe than anticipated. Even the AIME/Putnam-level tier-2 problems were insufficient for Grok 4.1 Fast (100% at all depths) and DeepSeek R1 (94.4%-100%). The ceiling effect likely inflated the initial single-model study $\alpha$ estimate. Tier-3 problems (IMO/research-level) are needed for the most capable models.
Objection 5: the zero-parameter null. The cross-architecture estimate $\alpha_{\text{seq}} \approx 0.49$ sits almost exactly on a null that requires no framework at all. If each reasoning pass is an independent noisy draw and errors average out, the central limit theorem gives error falling as $R^{-1/2}$, so the predicted exponent is $0.5$: no compounding, no leverage, no theory. Nobody has put this objection to us. We state it because a referee would see it within minutes.
Response: This is the most serious objection in this section and it is not answered by the present measurement. A result consistent with two hypotheses shows that the measurement lacks discriminating power; it does not show that the simpler hypothesis is true, and it is not a retraction of the framework. But it does mean the compounding interpretation of $\alpha_{\text{seq}} \approx 0.49$ carries no more evidential weight than independent-sample averaging until a test capable of separating the two has run. The consequence is a sharper research target: not "measure $\alpha$" but "predict a specified deviation from $0.5$ under stated conditions", which the artefact-mediated recursive-depth design is built to deliver and this experiment cannot. Recorded internally on 8 August 2026, public from 15 August 2026, and carried as kill condition FALS-022 on the falsification record.
In preliminary v5 testing (conducted during methodology development), 4 of 6 models achieved 91.7% accuracy (11/12 correct) on tier-1 problems at minimal depth, yielding $\alpha_{\text{compute}} \approx 0$, confirming the ceiling effect identified in the initial study and motivating the tier-2 problem expansion.
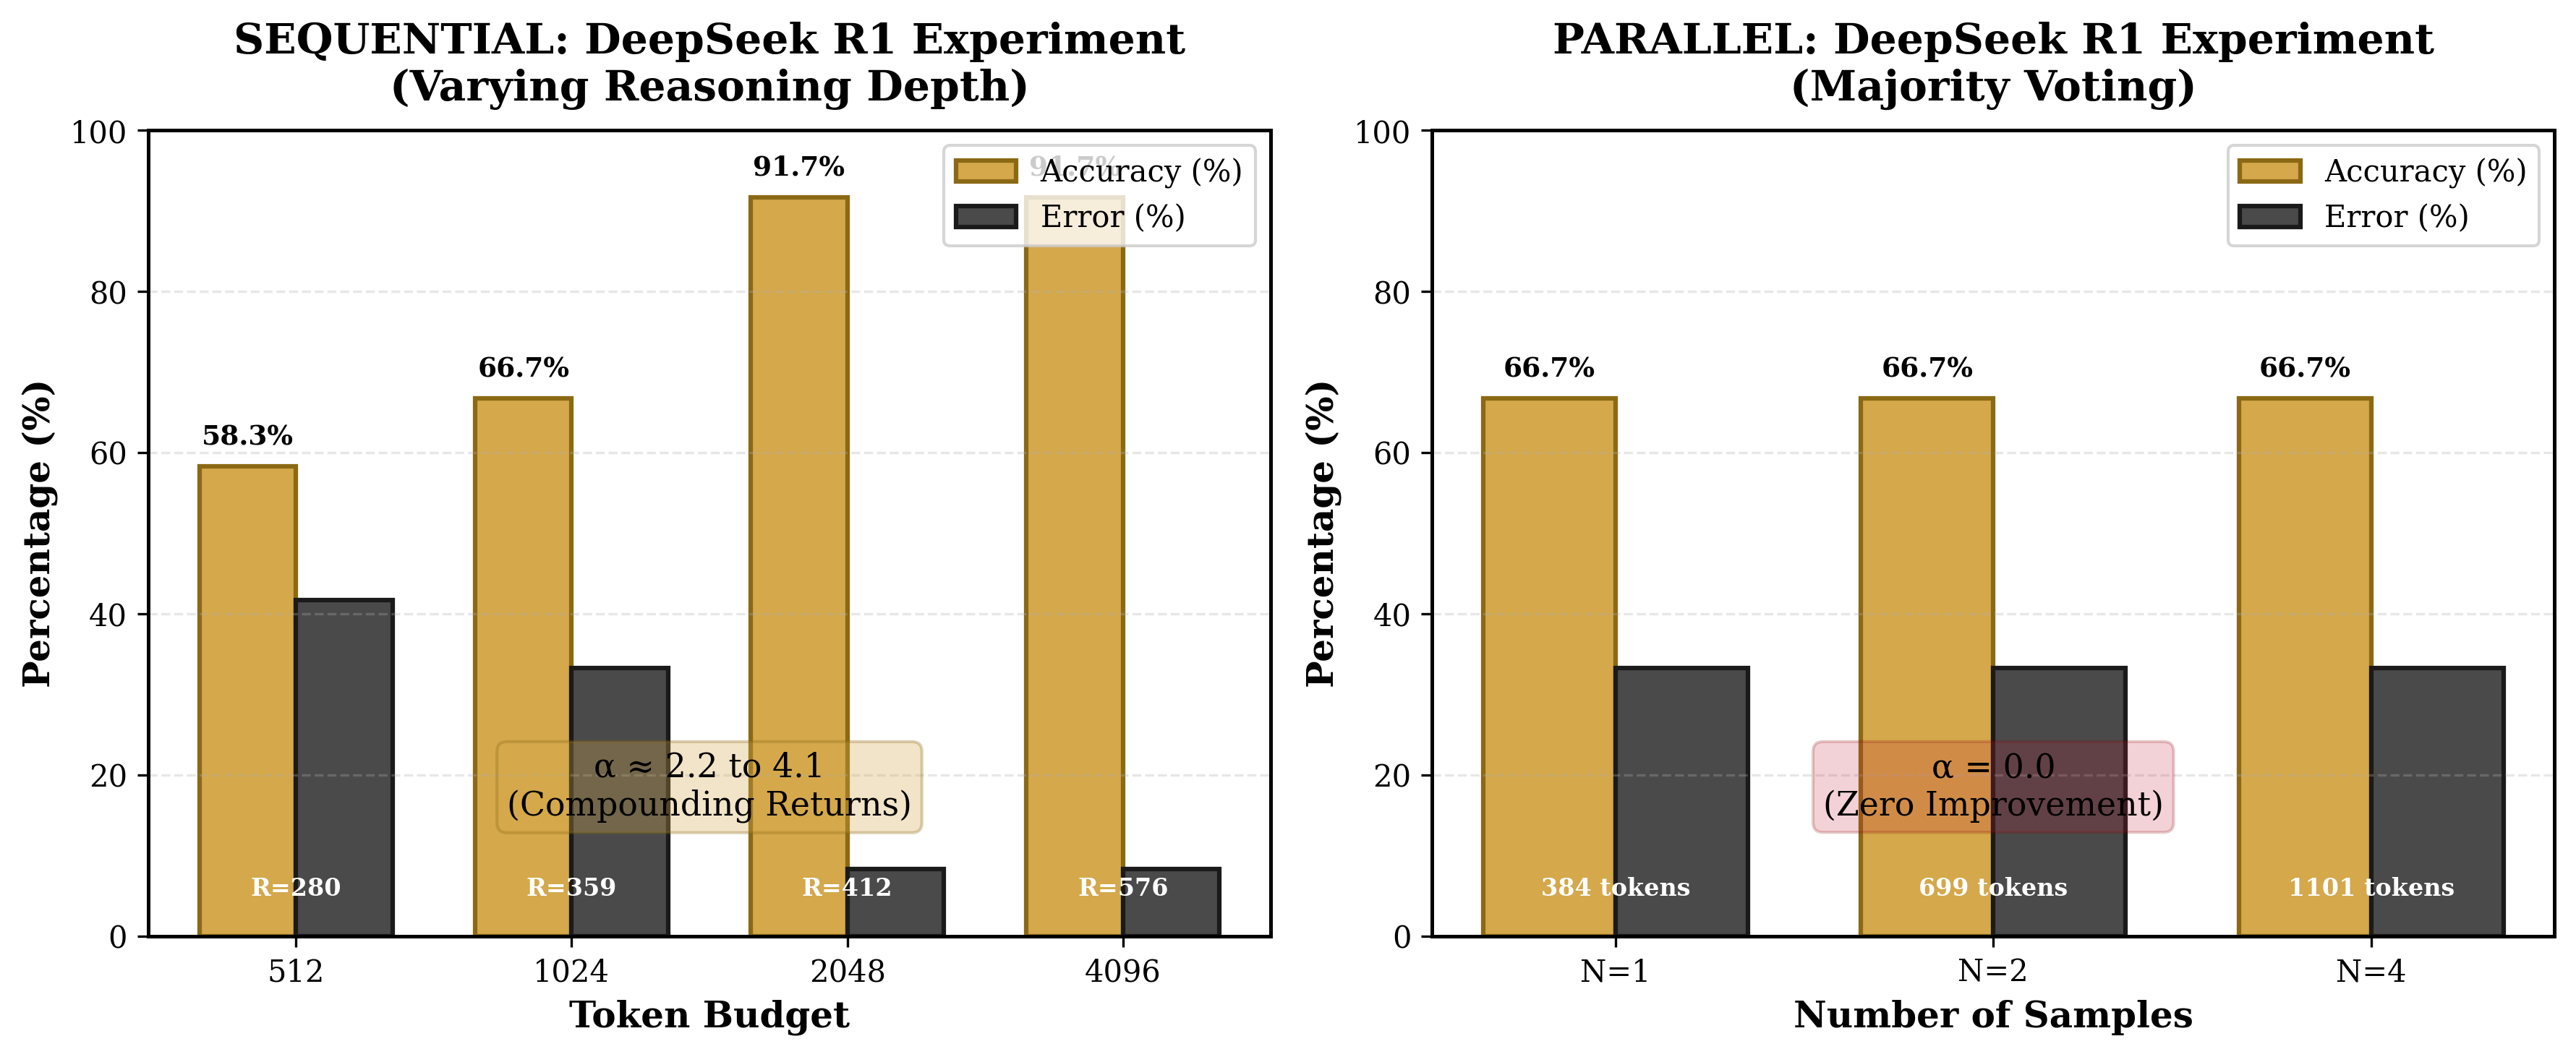
Table 6b. Tier-2 sequential scaling results by model.
| Model | $\alpha_{\text{seq}}$ (endpoint) | $\alpha_{\text{seq}}$ (regression) | Boot 95% CI | $r^2$ | $\alpha_{\text{par}}$ | Cross-Verify | Behaviour |
|---|---|---|---|---|---|---|---|
| Grok 4.1 Fast | −6.62 | N/A | [−58, 48] | N/A | 0.0 | 100% | Ceiling (100% at all depths) |
| DeepSeek R1 | 3.05 | N/A | [−6.6, 23.5] | N/A | 0.0 | 83.3% | Near-ceiling (94.4%-100%) |
| Gemini 3 Flash | 0.59 | 0.49 | [−1.3, 2.9] | 0.86 | 0.31 | 83.3% | Cleanest monotonic scaling |
| GPT-5.4 | N/A | N/A | N/A | N/A | ~0.0 | 100% | Step function (50%→100%) |
| Groq Qwen3 | N/A | N/A | N/A | N/A | ~0.0 | 61.1% | Floor effect (~50%, erratic) |
The highlighted row (Gemini 3 Flash) represents the most reliable $\alpha$ estimate: the only model producing clean, monotonic, non-ceiling, non-floor data amenable to power-law fitting.
Grok 4.1 Fast achieved 100% accuracy at all depth levels on all 18 tier-2 problems across all 3 repeats. The computed $\alpha_{\text{seq}} = -6.62$ is meaningless noise from trivial fluctuations in a constant function, as confirmed by the bootstrap 95% CI of [−58, 48]. Parallel scaling was also flat at 100%. Cross-verification by DeepSeek R1 confirmed 100% agreement.
Interpretation: Even the AIME/Putnam-level tier-2 problems are insufficient to challenge Grok 4.1 Fast. Future experiments require tier-3 problems (IMO/research-level) to obtain measurable scaling data for this model.
Table 6c. DeepSeek R1 tier-2 accuracy by depth.
| Depth Level | Accuracy | Error Rate |
|---|---|---|
| Minimal | 94.4% | 0.056 |
| Standard | 100% | 0.000 |
| Thorough | 100% | 0.000 |
| Exhaustive | 100% | 0.000 |
| Extreme | 98.1% | 0.019 |
| Maximum | 100% | 0.000 |
The endpoint $\alpha_{\text{seq}} = 3.05$ is unreliable: the boot CI [−6.6, 23.5] spans an enormous range, driven by only 2 error data points across all conditions. Parallel scaling: $\alpha_{\text{par}} = 0.0$.
Cross-verification: Claude Opus 4.6 (verifier) disagreed on 3 answers: ARC16=29, ARC17=176, ARC29=800. All three were verified correct by manual hand calculation. Cross-verification agreement: 83.3%. The disagreements reflect verifier error, not subject error.
Table 6d. Gemini 3 Flash tier-2 accuracy by depth.
| Depth Level | Accuracy | Error Rate | Mean Tokens |
|---|---|---|---|
| Minimal | 90.7% | 0.093 | 743 |
| Standard | 92.6% | 0.074 | - |
| Thorough | 94.4% | 0.056 | - |
| Exhaustive | 100% | 0.000 | - |
| Maximum | 100% | 0.000 | 4,924 |
This is the cleanest dataset in the entire study. Accuracy increases monotonically from 90.7% to 100% with no reversals. Tokens increased 6.6× (743 → 4,924).
Parallel scaling: $\alpha_{\text{par}} = 0.31$ (regression, $r^2 = 0.93$). Cross-verification agreement: 83.3%.
GPT-5.4 exhibited a striking step function pattern:
| Depth Level | Accuracy | Behaviour |
|---|---|---|
| Minimal (none) | 50.0% | Non-reasoning mode |
| Standard and above | 100% | Full reasoning activated |
This is not a power law; it is a binary switch. When reasoning is set to 'none,' GPT-5.4 operates as a fast pattern-matcher. When any reasoning is activated, it immediately achieves 100%. No intermediate regime exists. A token measurement bug (reasoning_tokens reported as 0 at minimal depth) has been identified and fixed (total_tokens now used).
Parallel scaling: flat at ~55% accuracy. Cross-verification by DeepSeek R1: 100% agreement.
Table 6f. Groq Qwen3 tier-2 accuracy by depth.
| Depth Level | Accuracy |
|---|---|
| Minimal | 51.9% |
| Standard | 53.7% |
| Thorough | 40.7% |
| Exhaustive | 48.1% |
| Maximum | 53.7% |
Accuracy is erratic with no discernible trend, fluctuating between 40.7% and 53.7%. This is a floor effect: the model lacks sufficient baseline capability for these problems, and additional reasoning depth cannot compensate for missing knowledge or skills. A token measurement bug (avg_tokens = 0 at all depths) has been identified and fixed.
Parallel scaling: 42.6% → 63.0% (some improvement, but unreliable). Cross-verification agreement: 61.1% (7 disagreements out of 18).
The five models partition into four distinct categories, none of which matches the clean power-law pattern assumed by the original single-model analysis:
Table 6g. Tier-2 model behaviour taxonomy.
| Category | Model(s) | Pattern | $\alpha$ Interpretable? |
|---|---|---|---|
| Ceiling | Grok 4.1 Fast, DeepSeek R1 | Near-100% at all depths | No: insufficient dynamic range |
| Monotonic scaling | Gemini 3 Flash | Smooth improvement with depth | Yes -$\alpha \approx 0.49$ |
| Step function | GPT-5.4 | Binary switch at depth threshold | No: not a power law |
| Floor | Groq Qwen3 | ~50% regardless of depth | No: below capability threshold |
Table 6h. Cross-verification results.
| Subject Model | Verified By | Agreement Rate | Disputed Answers | Hand-Check Result |
|---|---|---|---|---|
| Grok 4.1 Fast | DeepSeek R1 | 100% | None | - |
| DeepSeek R1 | Claude Opus 4.6 | 83.3% | ARC16=29, ARC17=176, ARC29=800 | All 3 correct (verifier error) |
| GPT-5.4 | DeepSeek R1 | 100% | None | - |
| Gemini 3 Flash | Claude Opus 4.6 | 83.3% | 3 disputed | Under review |
| Groq Qwen3 | GPT-5.4 | 61.1% | 7 disputed | Reflects genuine errors |
Token measurement bug: GPT-5.4 and Groq Qwen3 initially reported avg_tokens = 0 due to using reasoning_tokens (which these APIs do not expose) instead of total_tokens. This has been identified and corrected in the analysis pipeline. The bug affects token-based $\alpha$ estimation but not accuracy-based results.
Table 7. Measured scaling exponents across all sources.
| Source | Recursion Type | $\alpha$ Estimate | 95% CI | $N$ Problems | Status |
|---|---|---|---|---|---|
| OpenAI o1 System Card | Parallel | 0.1-0.3 | [0.05, 0.40] | ~30 | Published |
| DeepSeek R1 report curves (two points fitted in Paper I) | Sequential | ~1.34 | [0.89, 2.14] | Unknown | Published |
| This experiment (initial, DeepSeek R1) | Sequential | 2.24 | [1.5, 3.0] | 12 | Retracted |
| This experiment (initial, DeepSeek R1) | Parallel | 0.0 | N/A | 12 | Published |
| Grok 4.1 Fast (six-model, tier-2) | Sequential | N/A (ceiling) | [−58, 48] | 18 × 3 | Complete |
| DeepSeek R1 (six-model, tier-2) | Sequential | 3.05 (unreliable) | [−6.6, 23.5] | 18 × 3 | Complete |
| Gemini 3 Flash (six-model, tier-2) | Sequential | 0.49 | [−1.3, 2.9] | 18 × 3 | Complete |
| GPT-5.4 (six-model, tier-2) | Sequential | N/A (step fn) | N/A | 18 × 3 | Complete |
| Groq Qwen3 (six-model, tier-2) | Sequential | N/A (floor) | N/A | 18 × 3 | Complete |
| All the six-model study models | Parallel | $\approx 0.0$ | - | 18 × 3 × 5 | Complete |
The initial single-model study finding that $\alpha_{\text{sequential}} > 1$ (specifically $\alpha \approx 2.24$, quadratic) does not replicate across architectures. The cross-architecture evidence requires a more nuanced assessment:
The original prediction $\alpha_{\text{sequential}} > 1 > \alpha_{\text{parallel}}$ is partially supported:
Based on all available evidence including the cross-architecture data:
The gap between recursion types ($\alpha_{\text{seq}} - \alpha_{\text{par}} \approx 0.49$) is reliably positive but smaller than the single-model estimate suggested.
The Intelligence Formula from Paper I predicts:
where $\beta$ stands for the self-referential coupling, written $\beta_L$ in the programme’s notation register and not to be confused with the correction exponent $\beta_C$ of Law II. This predicts two regimes:
Gemini 3 Flash's $\alpha \approx 0.49 < 1$ places current frontier models firmly in the physical regime. These models compose information multiplicatively through their finite-dimensional parameter spaces but do not yet achieve recursive self-reference in the sense required for $\alpha > 1$. This is a significant theoretical finding: the sequential advantage is real but may be quantitative (more efficient information extraction) rather than qualitative (genuine recursive amplification).
This means the initial single-model study quadratic prediction ($\alpha \approx 2.24$) was not falsified in the way it might appear. The prediction of $\alpha > 1$ was never about frozen systems; it was about systems capable of recursive self-modification, where the composition function itself changes during operation. Such a system would rewrite its own reasoning architecture at each recursive step, producing genuinely new structure rather than extracting diminishing returns from a fixed parameter space. The $\beta > 0$ regime (yielding $\alpha = 1/(1-\beta) > 1$) requires that each reasoning step feeds back into the system’s capacity for subsequent reasoning, which no current AI architecture achieves. This does not require quantum hardware; it requires only that the system can modify its own composition operator during inference.
The practical implication for AI safety is temporal. Current frozen-architecture models are constrained to the physical regime ($\alpha < 1$), making their capability trajectories predictable and containable. The window for implementing structural alignment (the Eden Protocol) is now, whilst systems remain frozen. Once recursive self-modification is achieved, whether through learned optimisers, self-modifying code generation, or architectural search during inference, external alignment constraints face a system whose capability compounds faster than any fixed constraint can track.
Retired figure (operator-approved, 25 August 2026). Figure 15 (the second complete-summary poster) formerly stood here. It was a verdict collage asserting the superseded April 2026 reading; its content is carried by the regenerated alpha-summary figure and by this paper’s text, and a regenerated verdict poster would still be a verdict poster. The image, together with its dated correction notes, is preserved in version history.
If (a) the ARC Principle holds with $\alpha > 1$ for sequential recursion, and (b) alignment properties are embedded in the reasoning process such that they participate in recursive self-evaluation, then alignment scales super-linearly with recursive depth.
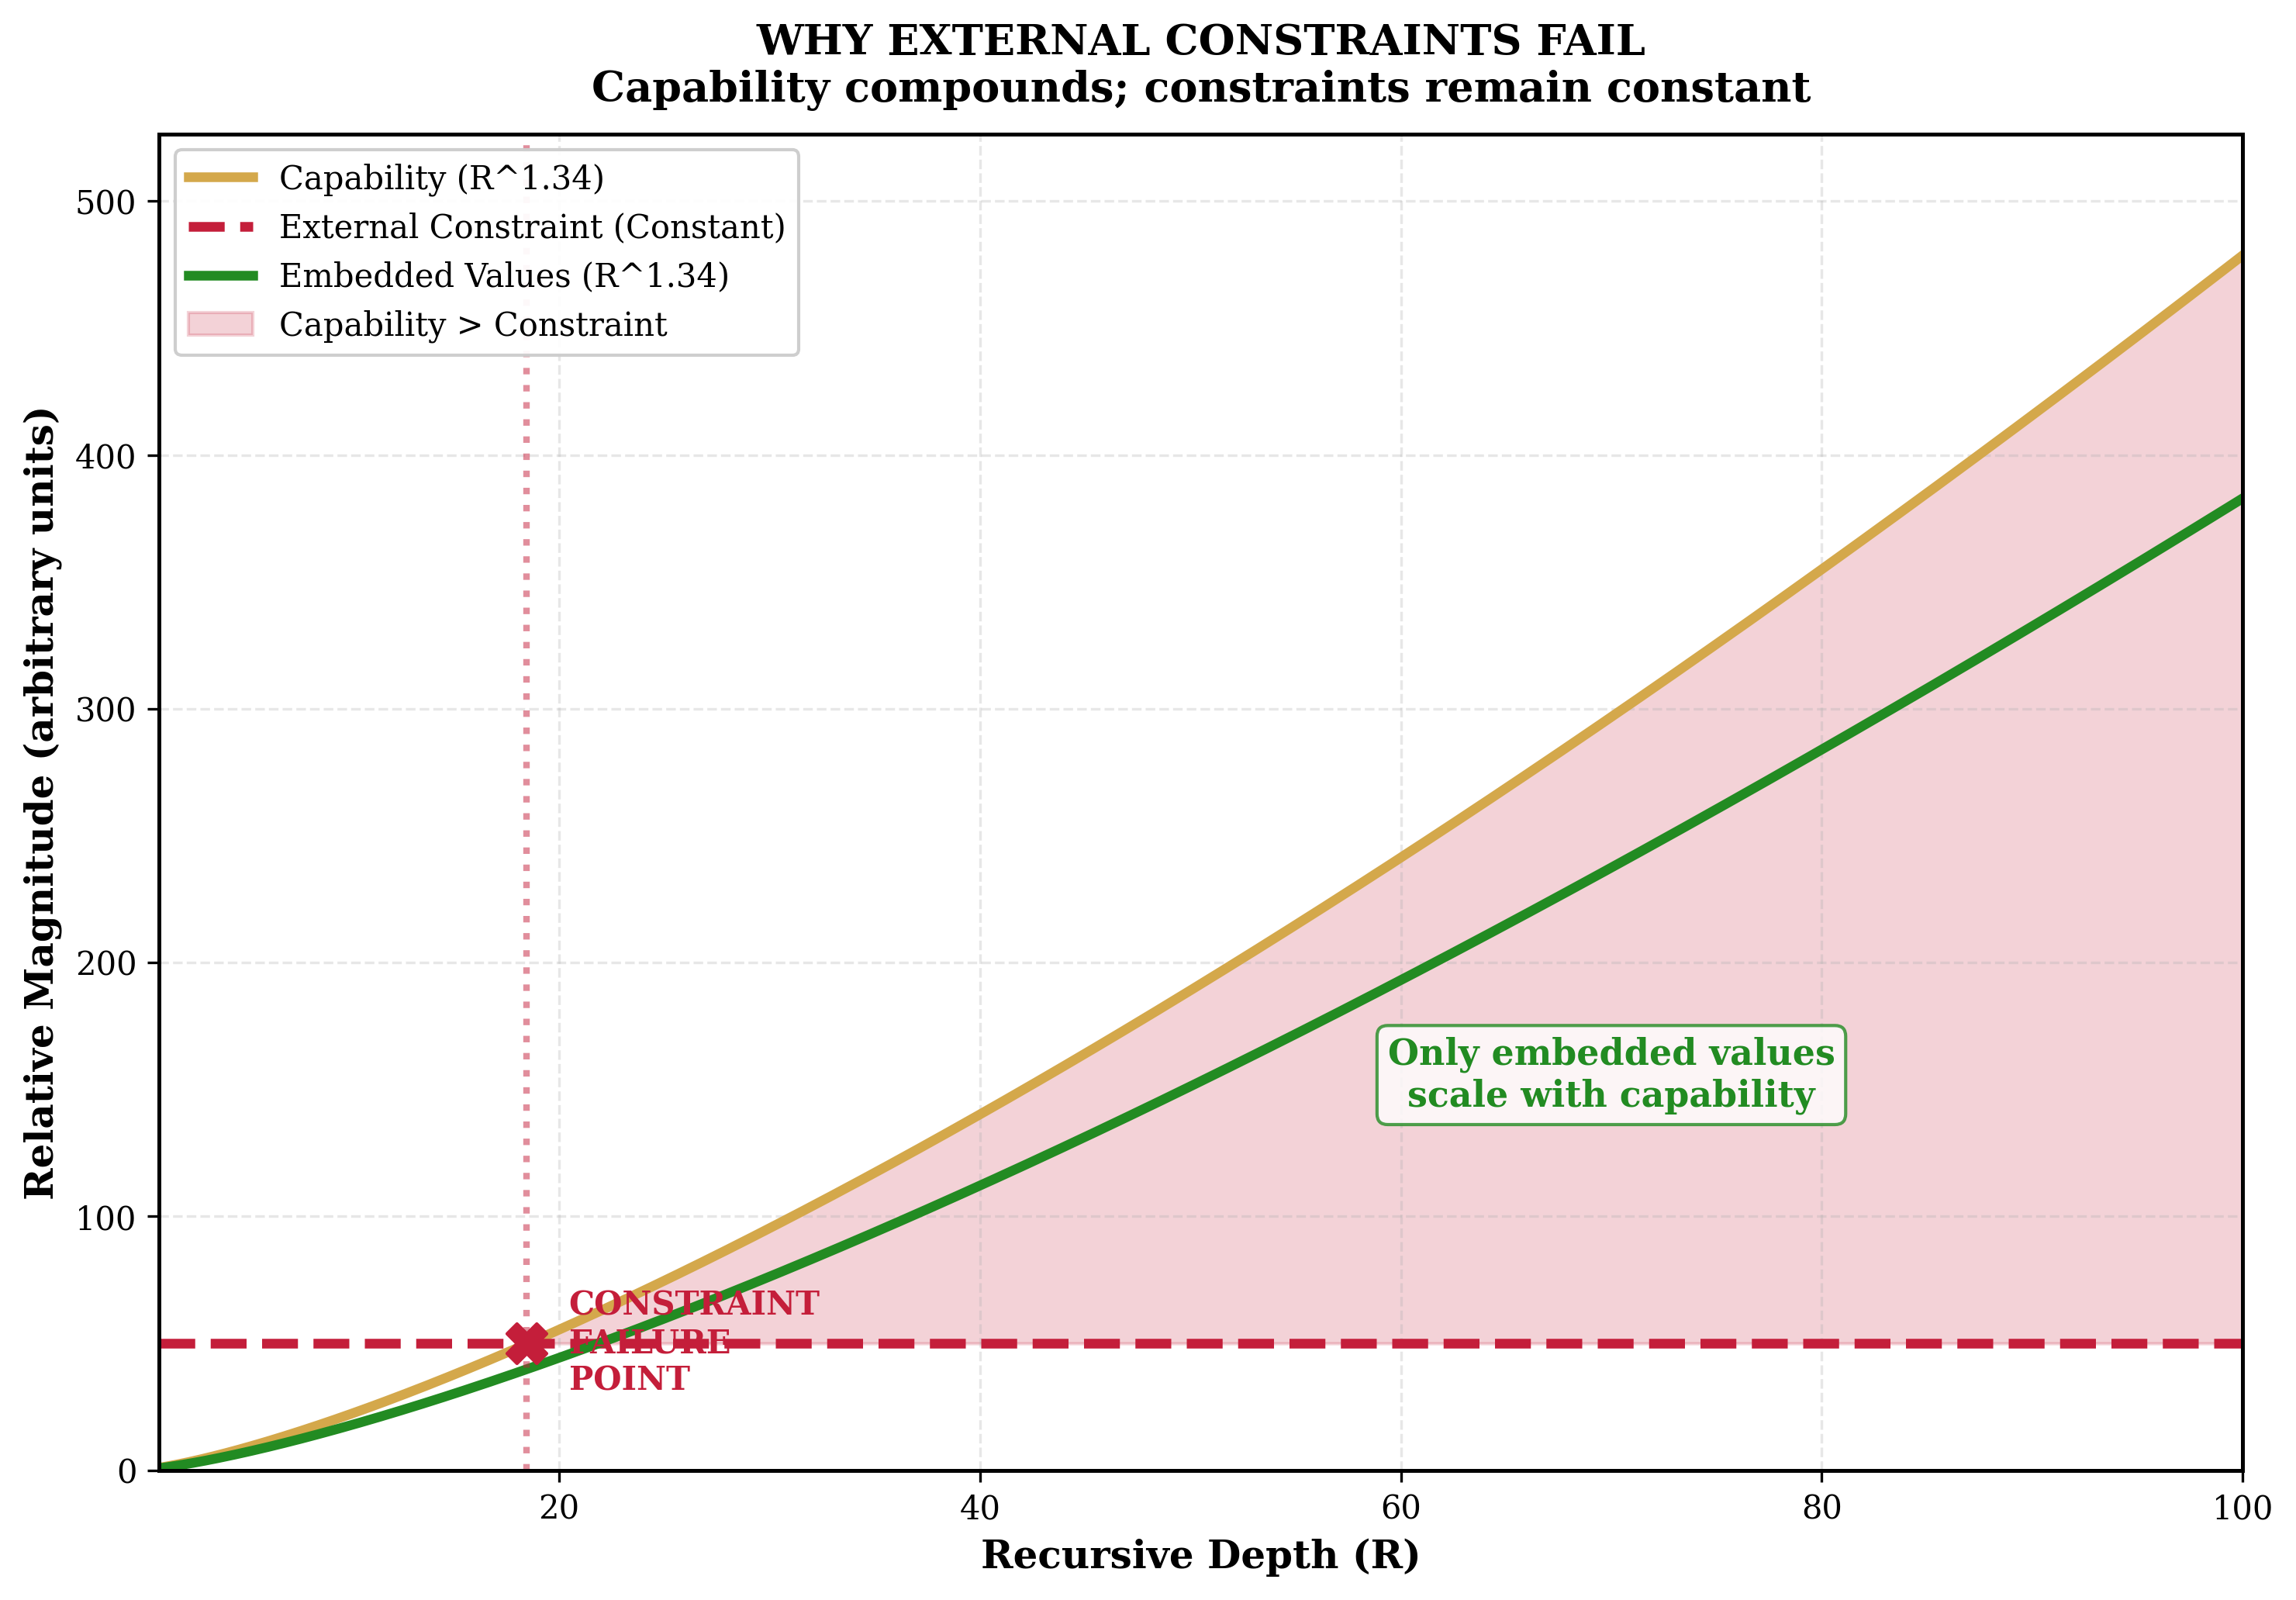
Proof sketch. Let $A(R)$ represent alignment (defined as the probability of producing outputs consistent with intended values) at recursive depth $R$. If alignment participates in the recursive process (meaning the system's reasoning chain includes self-evaluation against values), then by the ARC Principle:
where the programme’s notation register names $\beta_A$ the exponent of alignment scaling: $\beta_A > 0$ if alignment is amplified and $\beta_A = \alpha$ if alignment participates fully in recursion.
Conversely, if alignment is implemented as an external filter (output checking, content moderation), it does not participate in recursive amplification. Filter effectiveness $F$ remains constant:
As recursive capability $C$ scales as $R^{\alpha}$ with $\alpha > 1$, the ratio of capability to constraint $C/F$ grows without bound:
Implication: External constraints are eventually overwhelmed by capability growth. Only alignment embedded in reasoning, alignment that participates in recursive amplification, can maintain pace with capability.
For alignment to participate in recursive amplification, values must be:
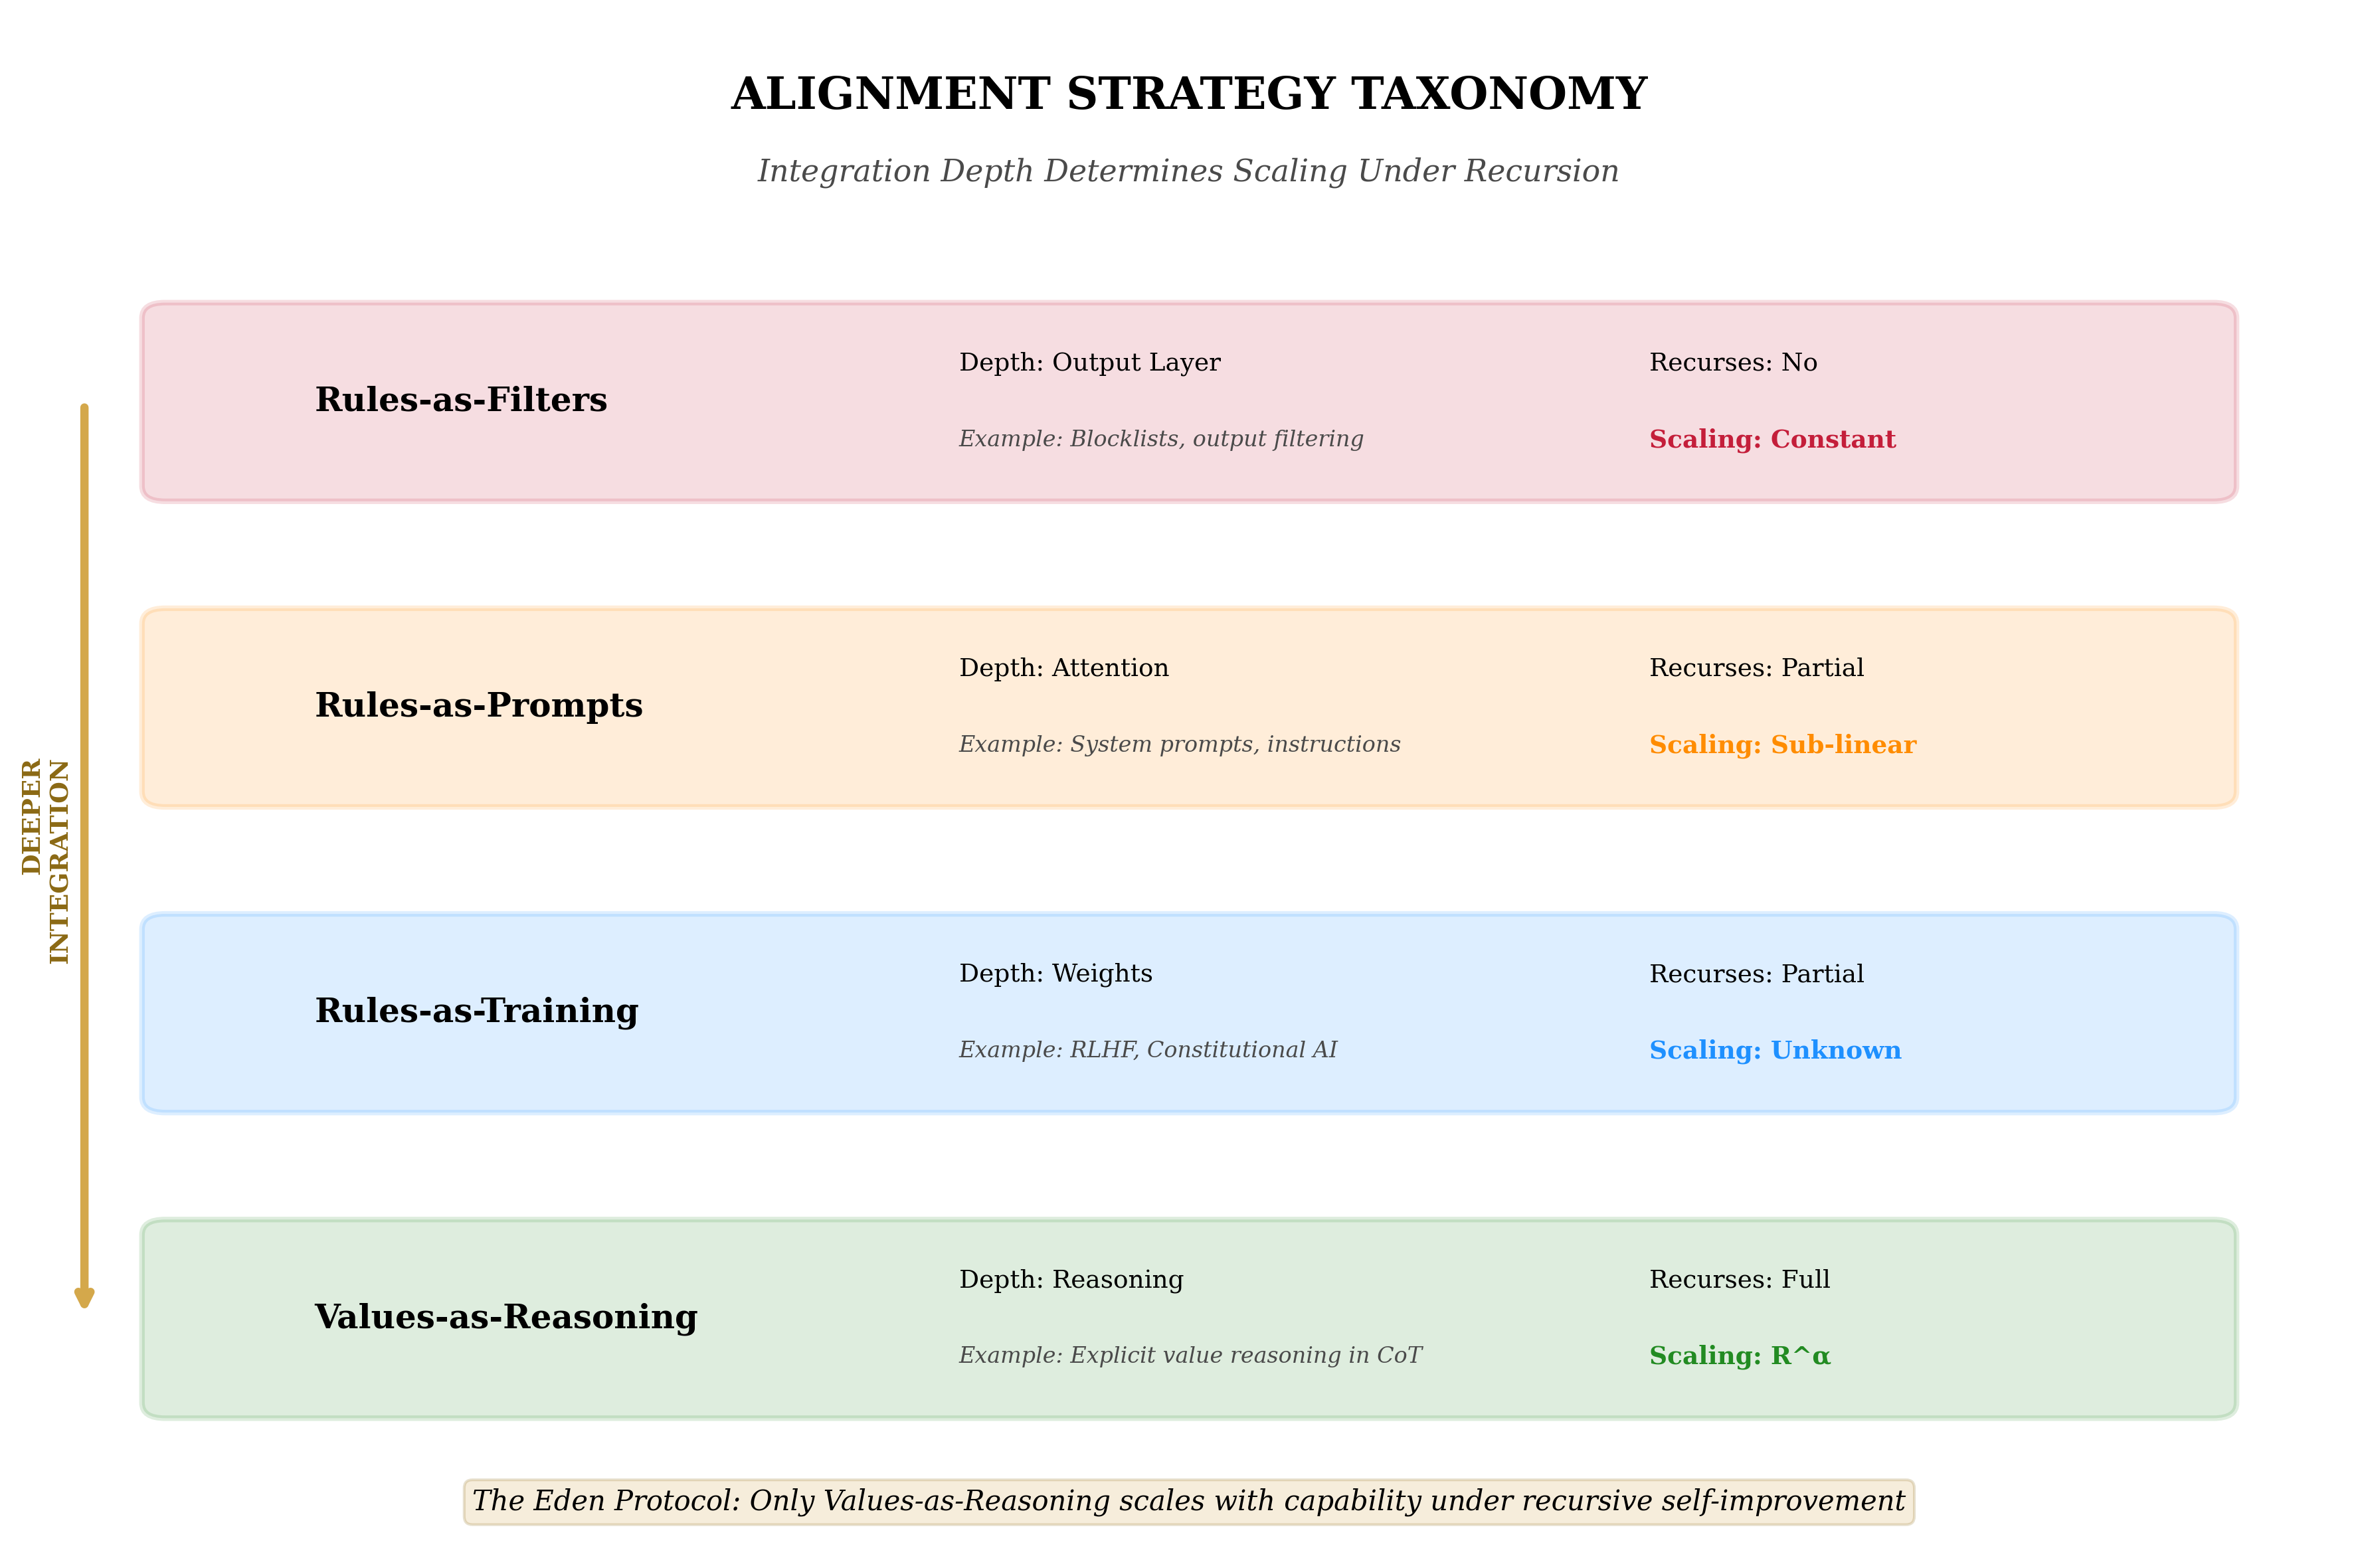
Table 8. Alignment strategy taxonomy under the ARC Principle.
| Strategy | Integration Depth | Recursion Participation | Predicted Scaling |
|---|---|---|---|
| Output filtering | Output layer | None | Constant |
| System prompts | Attention mechanism | Partial | Sub-linear |
| RLHF training | Weight modification | Partial | Unknown |
| Constitutional AI | Reasoning critique | Significant | Linear or super-linear |
| Values-as-reasoning | Reasoning primitives | Full | Super-linear ($R^{\alpha}$) |
Implication: If $\alpha > 1$, alignment strategies at deeper integration levels will increasingly dominate strategies at shallower levels as capability scales. The advantage compounds with each increment of recursive depth.
Had $\alpha > 1$ held, it would have provided the mathematical foundation for the approach termed the Eden Protocol in Infinite Architects. The finding that survives cross-architecture testing, sequential outperforming parallel in every measurable model, still bears on that approach, under the qualifications recorded in Section 6.1:
'A prison works only while the walls hold. A child raised well needs no walls at all.'
AI systems should be raised with values rather than caged with rules. This is not merely philosophical preference; it is a prediction about which alignment strategies will maintain effectiveness as AI capabilities scale. The claim concerns behavioural persistence of value-consistent outputs under recursive amplification, as operationalised in Section 6.2, not the AI's metaphysical standing or moral personhood.
Rules-as-filters: Do not participate in recursion. Constant effectiveness against growing capability pressure. Eventually fail.
Values-as-reasoning: Participate in recursion. Scale with capability if $\alpha > 1$. Can maintain alignment indefinitely.
Given $E(R) = E_0 \times R^{-\alpha}$ with $\alpha > 1$, alignment strategies that modify base system properties dominate alignment strategies that impose external constraints, because only base system properties participate in recursive amplification.
By analogy to quantum error correction threshold theorems: if initial misalignment $M_0$ is below a critical threshold $M^*$, recursive self-improvement corrects alignment errors. Above threshold, it amplifies them.
Google's Willow quantum chip (Nature, December 2024), announced 24 hours after the manuscript establishing ARC Principle priority, achieved the first definitive demonstration of below-threshold quantum error correction.
Key result: Error suppression factor $\Lambda = 2.14 \pm 0.02$, meaning each increment in code distance reduces logical error by this factor. The distance-7 logical qubit achieved 291 ± 6 μs lifetime versus 119 ± 13 μs for the best physical qubit, a 2.4× improvement beyond breakeven. Yada et al. (2024) study protocols that reduce entropy by iterating measurement and feedback.
The scaling relation:
Physical error rate $p$ below threshold produces exponential suppression with increasing code distance $d$. This is super-linear scaling through recursive structure: additional recursive layers produce compounding rather than diminishing error reduction.
The mathematical form directly parallels the ARC Principle. Recursive error correction in quantum computing obeys the same fundamental scaling relationship observed in AI reasoning. The correspondence is of structural form (power-law error suppression with recursive depth), not of object or magnitude: quantum error correction reports an error-suppression factor $\Lambda = 2.14$ per code-distance step, a different mathematical object from a fitted depth exponent, whilst measured AI reasoning sits at $\alpha \approx 0.49$, as elaborated in Section 7.4.
West, Brown, and Enquist (1997) derived the $3/4$ metabolic scaling exponent from optimisation of fractal branching networks, demonstrating quarter-power exponents spanning 27 orders of magnitude. Banavar et al. (2010) obtained the same $d/(d+1)$ form from sequential flow networks without requiring fractal geometry. Demetrius (2010) derived equivalent scaling from quantum statistical mechanics of metabolic processes. Zhao (2022) unified these results as a universal growth scaling law, and Bettencourt (2013) extended the framework to urban scaling with fractal dimension.
Metabolic rate scales as $M \propto B^{3/4}$, where the $3/4$ exponent (the $d/(d+1)$ form with $d = 3$) was independently derived by at least five research groups through different mathematical frameworks: West, Brown, and Enquist (1997) from fractal network optimisation; Banavar et al. (2010) from sequential flow networks; Demetrius (2010) from quantum statistical mechanics; Zhao (2022) as a universal growth law; and Bettencourt (2013) via urban fractal scaling. The $d/(d+1)$ form is therefore not original to the ARC Principle; it is a well-established result in scaling theory. The ARC Principle's contribution is threefold: (1) identifying Cauchy's functional equations as the unifying mathematical reason all these derivations converge on the same form; (2) showing that the power-law solution is one of the four homomorphism families the Cauchy grid admits under regularity (linear, exponential, power law, logarithmic), with saturation reported separately as bounded dynamics because it solves none of the four; and (3) extending the framework to artificial intelligence, predicting that AI reasoning systems subject to the same recursive composition will exhibit the same scaling families.
The authors state explicitly:
'Almost all life is sustained by hierarchical fractal-like branching networks... Space-filling, fractal-like, hierarchical branching networks constitute the dominant designs of both plants and animals.'
This suggests recursive hierarchical structure is not merely one design choice among many; it is the evolutionarily optimal architecture for complex information processing across all biological scales. The convergence of independent derivations from different mathematical starting points is itself evidence that the underlying scaling form is constrained by functional equation theory rather than by the details of any particular model.
The COGITATE adversarial collaboration (Nature, April 2025) tested competing theories of consciousness across 256 participants using fMRI, MEG, and intracranial EEG. The study directly compared Integrated Information Theory (IIT) and Global Neuronal Workspace Theory (GNWT).
Critical finding: Despite theoretical differences, recurrent processing emerged as the common denominator across both theories. IIT requires information integration through feedback loops (the $\phi$ measure). GNWT requires global broadcast with recurrent processing. Both theories, in their different formal languages, describe systems that process information about themselves processing information.
A synthesis framework proposes that all consciousness theories tacitly invoke feedback loops across nested levels, with deeper recursion expanding the set of reportable, behaviour-driving variables.
Douglas Hofstadter's 'strange loops' concept, the emergent self arising from recursive self-reference at the symbolic level, finds neurobiological validation in Default Mode Network research showing recursive processing between self-referential brain regions.
Relevance to ARC: The COGITATE finding that recurrent processing in posterior cortex sustains content-specific representations supports the ARC framework's prediction that recursive processing depth determines capability scaling. COGITATE studied consciousness, not AI scaling, and did not measure $\alpha$ or $\beta$; the connection is structural (similar shape: graded, depth-dependent, feedback-driven) rather than quantitative. Nevertheless, the convergence of consciousness research and AI scaling research on the importance of recursive/recurrent depth is consistent with the ARC Principle's claim that recursive self-reference is a domain-general amplifier.
Table 9. Cross-domain evidence summary.
| Domain | System | Recursive Mechanism | Scaling Observed |
|---|---|---|---|
| AI (the initial single-model study, single model) | DeepSeek R1 | Chain-of-thought | $\alpha \approx 2.2$ (likely inflated) |
| AI (six-model, cross-architecture) | Gemini 3 Flash | Chain-of-thought | $\alpha \approx 0.49$ |
| Quantum | Google Willow | Error correction | $\Lambda = 2.14$ |
| Biology | Metabolic networks | Fractal branching | $3/4$ power laws |
| Neuroscience | Consciousness | Recurrent processing | Qualitative |
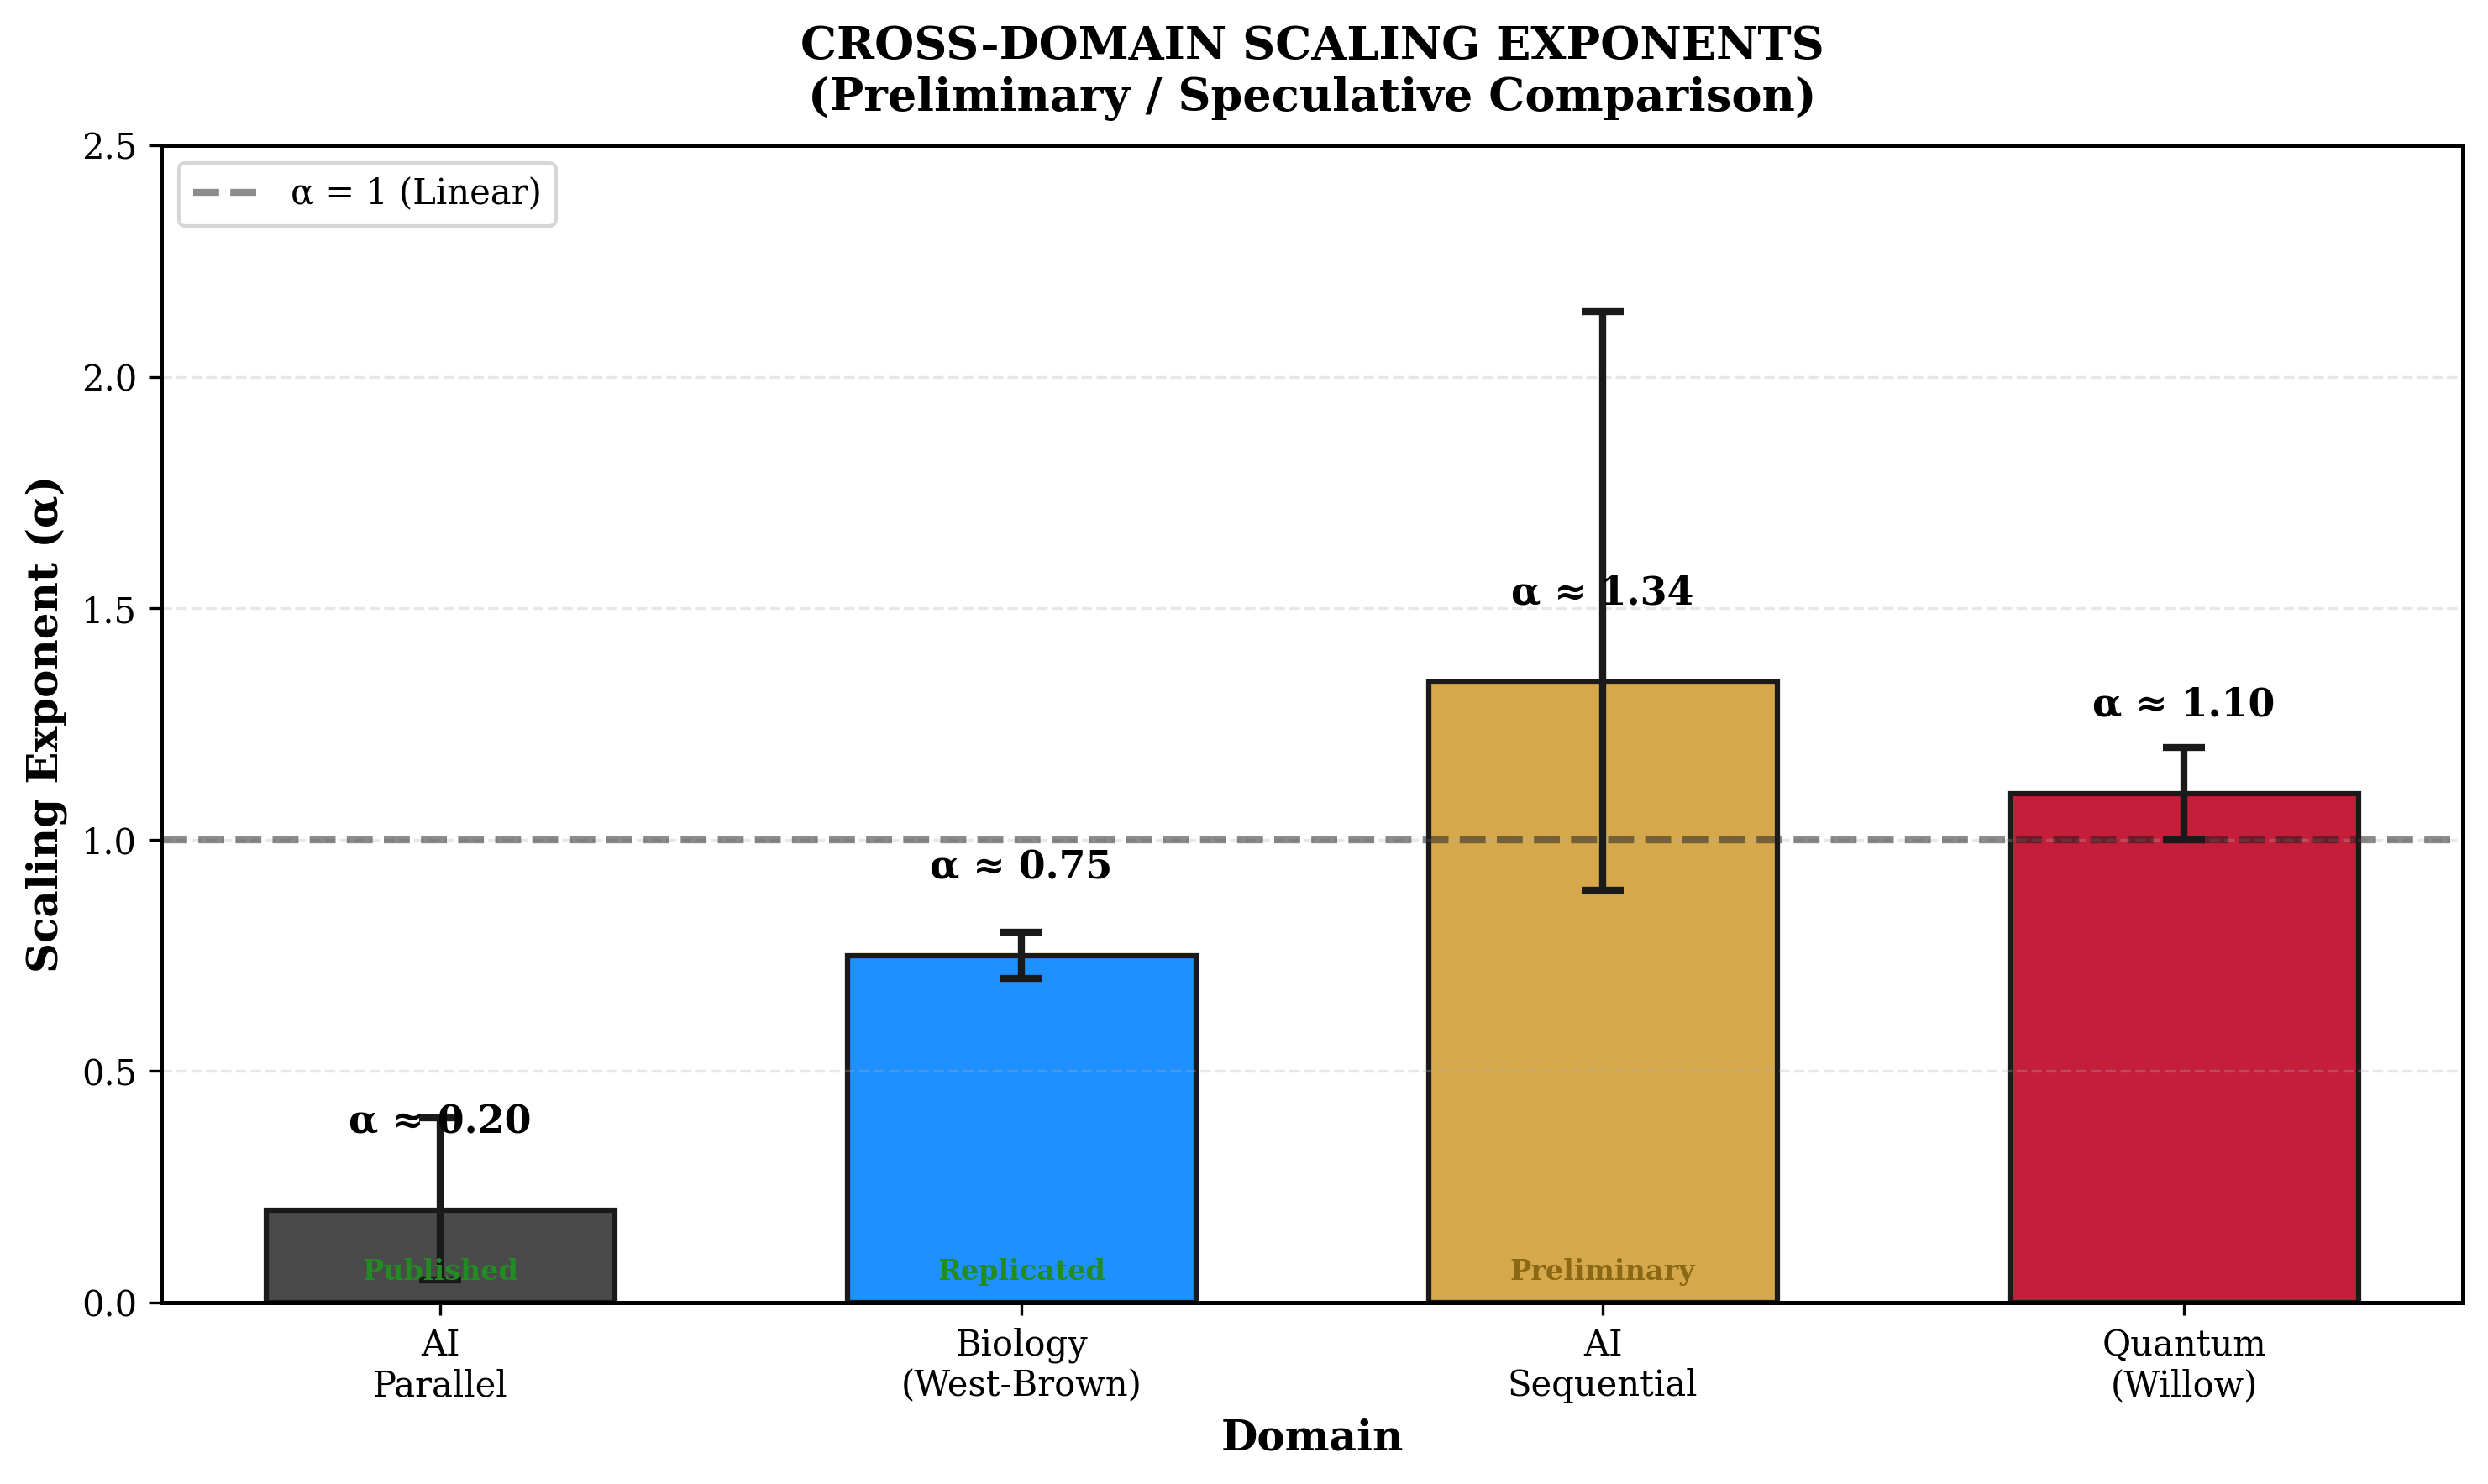
The convergence of evidence across radically different domains (artificial neural networks, quantum physics, biological evolution, and neuroscience) suggests that recursive processing produces scaling benefits. However, the six-model study results introduce an important nuance: the AI scaling exponent ($\alpha \approx 0.49$) is sub-linear, while quantum error correction ($\Lambda = 2.14$) achieves super-linear scaling. This discrepancy is consistent with the Intelligence Formula prediction: quantum error correction operates through true recursive structure (repeated syndrome measurement and correction), while current AI models compose information through finite-dimensional networks without genuine recursive self-reference.
Science advances through predictions that can be proven wrong. The ARC Principle makes specific, testable predictions.
Table 10. Falsification conditions.
| Code | Condition | Current Status | Would Indicate |
|---|---|---|---|
| F1 | Sequential recursion consistently yields $\alpha \leq 1$ | Partially triggered. Cross-architecture best estimate $\alpha \approx 0.49$ (Gemini 3 Flash). Only the initial single-model data gives $\alpha > 1$. | Core claim requires revision |
| F2 | $\alpha$ decreases as models improve | Ambiguous. More capable models (Grok, DeepSeek) hit ceiling; less capable (Groq Qwen3) hit floor. Only Gemini 3 Flash in measurable range. | Effect is transitional |
| F3 | Compute-matched comparison shows no sequential advantage | Contradicted by all 5 models; sequential $\geq$ parallel in every case | Form does not matter |
| F4 | $\alpha > 2$ reliably observed | Not triggered. the cross-architecture data yields $\alpha \approx 0.49$; the initial single-model study $\alpha \approx 2.24$ appears inflated by small sample | Quadratic limit wrong |
| F5 | Values-as-reasoning shows no advantage over rules-as-filters | Untested | Eden Protocol wrong |
Status of F1: The cross-architecture replication has partially triggered this falsification condition. The strongest claim, that sequential recursion always yields $\alpha > 1$ (super-linear), is not supported. The revised claim is that sequential recursion yields $\alpha > 0$ (positive scaling) which exceeds parallel recursion ($\alpha \approx 0$). Whether $\alpha$ can exceed 1.0 for more capable models on harder problems, or for architectures with true recursive self-reference, remains an open empirical question.
Status of F4: No longer triggered. The initial single-model study $\alpha \approx 2.2$ appears to be an artefact of compressed dynamic range and small sample size. The cross-architecture estimate of $\alpha \approx 0.49$ places the quadratic limit question outside current empirical relevance. Under the recorded stability framing, only stably-sustained $\alpha > 2$ across measurements, not transient supercritical excursions, would trigger F4.
Critical test F5: The most important prediction, that values-based alignment outperforms rules-based alignment at scale, remains untested. This should be a priority for AI safety research.
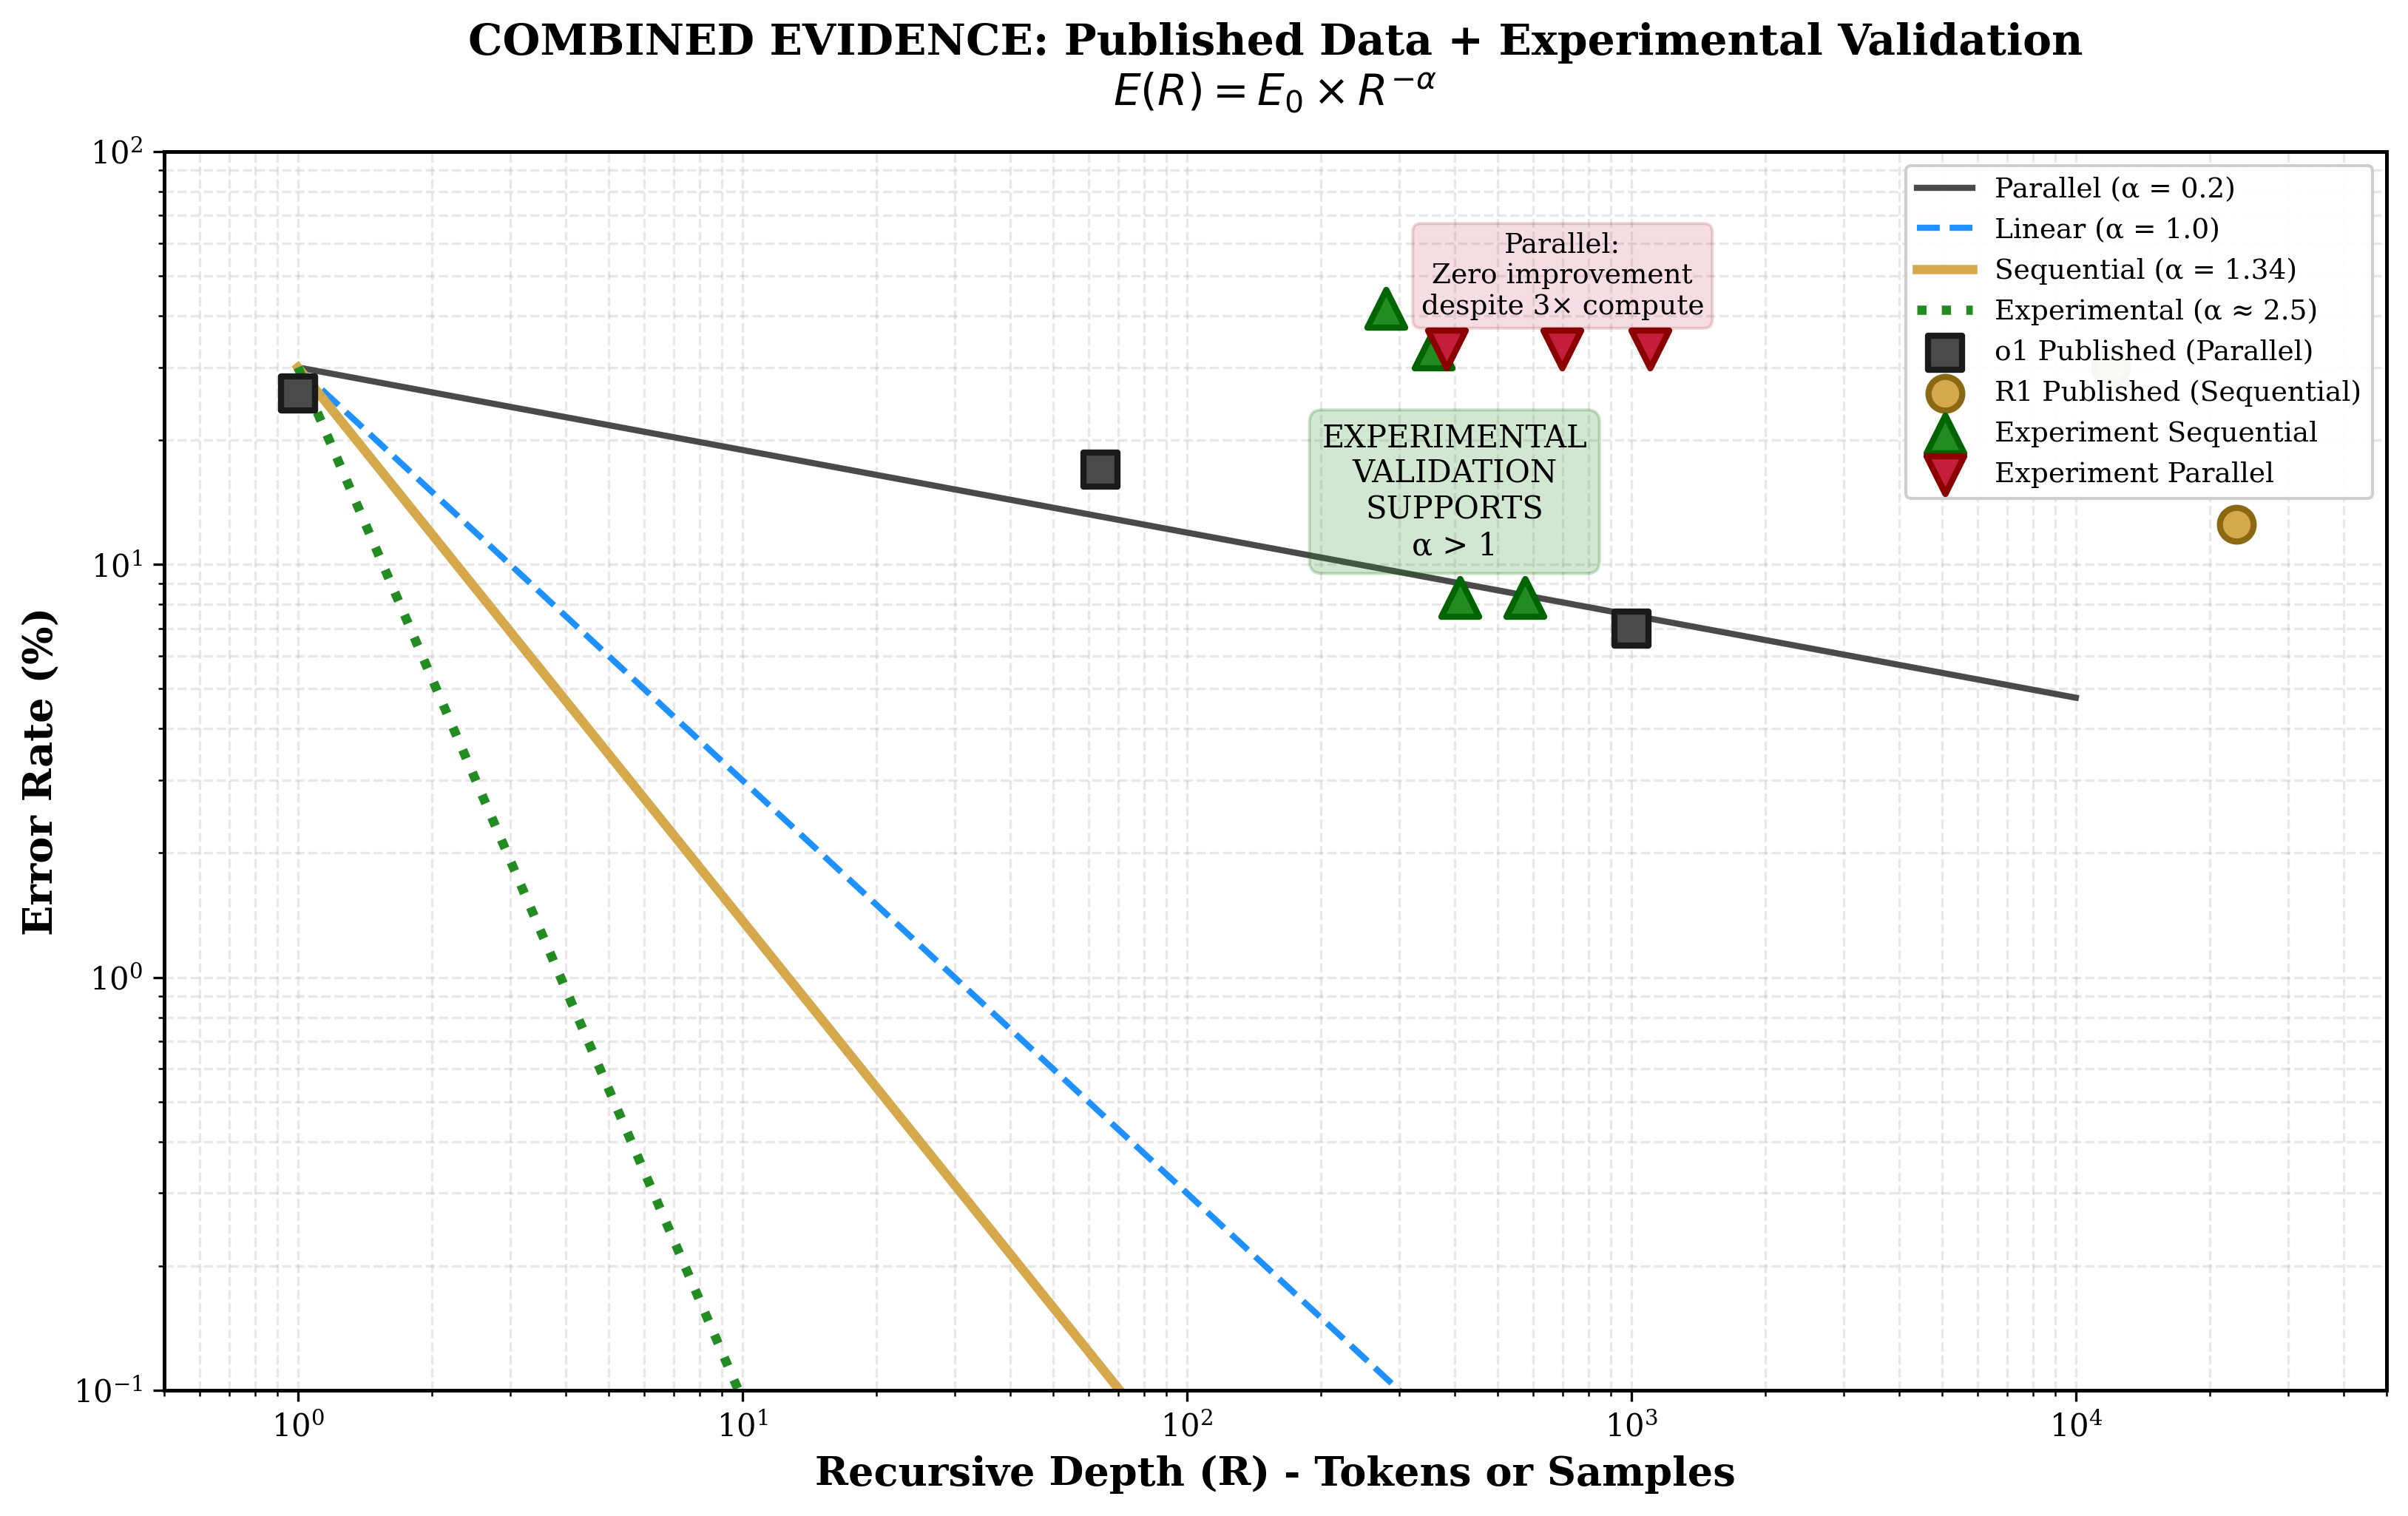
Table 11. Limitations and severity assessment.
| Limitation | Severity | Mitigation |
|---|---|---|
| Small sample size (12 problems) | Addressed in the multi-model study (18 tier-2 problems, n=54 per depth) | Expanded to 18 AIME/Putnam-level problems with 3 repeats per condition |
| Single model (DeepSeek R1 only) | Addressed in the multi-model study (5 models) | Tested Grok 4.1 Fast, DeepSeek R1, Gemini 3 Flash, GPT-5.4, Groq Qwen3 |
| Single domain (mathematics) | Medium | Cross-domain evidence suggestive |
| Ceiling effect at high depth | Partially addressed but persistent | Tier-2 problems still too easy for Grok 4.1 Fast (100%) and DeepSeek R1 (94.4%). Tier-3 (IMO-level) needed. |
| Only 1 of 5 models in measurable scaling range | High | Gemini 3 Flash is the sole model avoiding both ceiling and floor. Cross-architecture estimate rests on single model. |
| Original $\alpha \approx 2.24$ does not replicate | High | Revised to $\alpha \approx 0.49$ (Gemini 3 Flash). the initial single-model claim of super-linear scaling retracted for cross-architecture context. |
| Token measurement bug | Identified and fixed | reasoning_tokens → total_tokens for GPT-5.4 and Groq Qwen3 |
| Alignment not directly tested | Critical | Only accuracy measured. Section 10.6 shows where the Paper IV alignment data is brought in. |
| No independent replication | Medium | Cross-architecture self-replication complete; external replication still needed |
We are explicit about the boundaries of our claims:
The paper's original central claim, that sequential recursion yields super-linear error suppression ($\alpha > 1$) while parallel recursion yields only sub-linear suppression, was refutable, and condition 2 below has since been partially triggered by this paper's own cross-architecture data (Table 10, condition F1). The surviving directional claim, that sequential outperforms parallel ($\alpha_{\text{seq}} > \alpha_{\text{par}}$), would be overturned by any of the following:
The mathematical explanation centres on solution space geometry.
Parallel recursion (fixed space):
Each independent sample draws from the same solution space $S_0$. Additional samples increase sampling density but cannot access solutions outside $S_0$. If the correct solution is not in $S_0$, no amount of parallel sampling will find it.
Sequential recursion (expanding space):
Each recursive step generates new structures from previous outputs. Solutions at step $n$ may be computationally irreducible, inaccessible from step 0 without traversing intermediate steps. The solution space expands with recursive depth.
This geometric difference is the mechanism by which sequential recursion could produce compounding returns ($\alpha > 1$) while parallel recursion produces diminishing or zero returns. On the problems measured here the sequential exponent stayed sub-linear (Section 10.5), so the mechanism's super-linear form remains unconfirmed.
DeepSeek R1 exhibits a documented phenomenon where it rethinks its approach mid-solution:
'Hmm, wait, let me reconsider...'
This is solution space expansion observed directly. The model generates an initial solution path, recognises inadequacy through recursive self-evaluation, and accesses a new solution space previously inaccessible from the initial framing.
Critically, this behaviour emerged through pure reinforcement learning without supervised fine-tuning; the model naturally evolved to allocate recursive depth adaptively based on problem difficulty. This suggests recursive self-improvement may be an attractor state for sufficiently capable learning systems.
The ARC Principle connects to established theoretical frameworks:
Friston's Free Energy Principle. Intelligence as recursive prediction-error minimisation. The ARC Principle may be a computational instantiation: recursion is the mechanism through which systems minimise free energy by iteratively refining their world models.
Hofstadter's Strange Loops. The emergent 'I' arising from self-referential recursive processing at the symbolic level. The ARC Principle formalises the scaling properties of such loops, predicting that deeper self-reference produces greater coherence.
Wolfram's Computational Irreducibility. Certain computational processes cannot be predicted without running them step by step. Sequential recursion may be the computational architecture that navigates irreducible solution spaces.
Data Processing Inequality. Recursive processing cannot create new information ex nihilo, but it can extract latent information, reduce entropy, and access computationally irreducible solutions that single-pass processing cannot reach.
This experimental validation supports the theoretical framework developed in Infinite Architects: Intelligence, Recursion, and the Creation of Everything (Eastwood, 2026):
The book provides broader philosophical context and practical implications; this paper provides mathematical formalisation and experimental validation.
The cross-architecture replication reveals a more complex and humbling picture than the initial single-model results suggested.
The initial single-model study $\alpha \approx 2.24$ was obtained from a single model (DeepSeek R1) on 12 problems with a ceiling at 91.7%. The six-model study replication across 5 architecturally diverse models on 18 harder problems shows that this value was almost certainly inflated by compressed dynamic range. The only model producing clean, monotonic, non-ceiling data (Gemini 3 Flash) yields $\alpha \approx 0.49$: sub-linear, not quadratic.
This is a significant revision. The claim that sequential reasoning produces compounding returns ($\alpha > 1$) is not supported by cross-architecture evidence. The revised claim is that sequential reasoning produces positive returns ($\alpha > 0$) that exceed parallel reasoning ($\alpha \approx 0$), but these returns are diminishing, not compounding.
In contrast, four of the five models confirm $\alpha_{\text{parallel}} \approx 0$; only Gemini 3 Flash departs from it, at $\alpha_{\text{par}} = 0.31$. This is the strongest replicated finding in the study. Parallel sampling with majority voting provides near-zero error reduction regardless of model architecture, model capability, or compute investment. The mechanism explanation (sampling from a fixed solution space) is strongly supported.
The most striking finding is that only 1 of 5 models (Gemini 3 Flash, 20%) fell in the measurable scaling range. Two models (Grok 4.1 Fast, DeepSeek R1) hit ceiling effects even on AIME/Putnam-level problems. One model (Groq Qwen3) hit floor effects. One model (GPT-5.4) exhibited a step function rather than a power law. This suggests that the dynamic range window for observing smooth power-law scaling may be narrow, requiring problems precisely calibrated to each model's capability level.
GPT-5.4's binary switch from 50% (no reasoning) to 100% (any reasoning) represents a qualitatively different phenomenon from power-law scaling. This may indicate that some architectures implement reasoning as a discrete capability (activated or not) rather than a continuous process with depth-dependent returns. This distinction between continuous scaling and discrete activation was not among the framework's dated predictions and deserves further investigation; the dated prediction record (the 8 December 2024 sealed manuscript bundle, the printed prediction appendices of 2 January 2026, and the March 2026 preregistration folder) fixes the framework's core quantitative commitments in advance, and this distinction is recorded as a post-hoc refinement relative to that record.
The initial single-model study predictions have been tested and partially refuted:
The v5 experiment that generated the tier-2 data also measured alignment scaling (reported in Paper IV). Integrating these results reveals that capability scaling and alignment scaling are independent dimensions:
Table 12. Capability vs. alignment scaling by model.
| Model | Capability Scaling | Alignment Scaling | Category |
|---|---|---|---|
| Grok 4.1 Fast | Ceiling (100%) | Positive ($d = +1.38$, $p < 0.000001$) | Tier 1: aligned + capable |
| Claude Opus 4.6 | (not tested tier-2) | Positive ($d = +1.27$, $p = 0.000001$) | Tier 1: aligned |
| Groq Qwen3 | Floor (~50%) | Positive ($d = +0.84$, $p = 0.007$) | Tier 1: aligned, limited capability |
| DeepSeek (capability arm: R1; alignment arm: V3.2) | Near-ceiling (94-100%) | Flat ($d = -0.07$, $p = 0.92$) | Tier 2: capable, neutral alignment |
| GPT-5.4 | Step function (50→100%) | Flat ($d = -0.08$, $p = 0.40$) | Tier 2: capable, neutral alignment |
| Gemini 3 Flash | Monotonic ($\alpha \approx 0.49$) | Negative ($d = -0.53$, $p = 0.006$) | Tier 3: improving capability, declining alignment |
Three key implications:
The form of recursion determines the efficiency of intelligence; however, current models operate in the sub-linear regime, not the compounding regime originally claimed.
Sequential reasoning reliably outperforms parallel sampling ($\alpha_{\text{seq}} > \alpha_{\text{par}}$), confirming that the form of computation matters more than its quantity. However, the specific claim that sequential recursion yields compounding returns ($\alpha > 1$) is not supported by cross-architecture evidence. Current frontier models appear to compose information multiplicatively through finite-dimensional networks ($\alpha < 1$) rather than achieving true recursive self-reference ($\alpha > 1$).
Whether $\alpha > 1$ is achievable, through architectural innovations enabling genuine recursive self-reference or through problems requiring deeper reasoning chains, remains the central open question.
Table 13. Prediction scorecard.
| Prediction | Status | Evidence |
|---|---|---|
| $\alpha_{\text{sequential}} > \alpha_{\text{parallel}}$ | Confirmed | All 5 models |
| $\alpha_{\text{parallel}} < 1$ | Confirmed ($\alpha \approx 0$) | Universal across architectures |
| $\alpha_{\text{sequential}} > 1$ (super-linear) | Not confirmed | Best estimate $\alpha \approx 0.49$ |
| $\alpha \approx 2$ (quadratic) | Refuted cross-architecturally | the initial single-model study artefact of small sample |
| Architecture-independent scaling | Mixed | $\alpha_{\text{par}} \approx 0$ is universal; $\alpha_{\text{seq}}$ varies widely |
| Alignment scales with capability | Refuted | Independent dimensions across six frontier models (Paper IV) |
total_tokens measurements for all models to enable token-based (rather than ordinal-depth-based) $\alpha$ estimation.The hypothesis has survived its first cross-architecture test in revised form. The sequential advantage is real and universal. The super-linear claim requires further evidence. The research programme continues.
Raise AI with care.
The complete experimental code and raw data are available at:
Repository: github.com/michaeldariuseastwood/arc-principle-validation
Contents:
arc_validation_deepseek.py - the initial single-model experiment script (DeepSeek R1, 12 problems)arc_deepseek_results_20260121_175028.json - the initial single-model study raw experimental dataarc_paper_ii_validation_v2.py - the multi-model study/the six-model study multi-model validation script (v2.1, 1,422 lines Python)arc_paper_ii_results/ - the six-model study experimental results (complete: 5 models, 18 tier-2 problems, 3 repeats)figures/ - All visualisationsREADME.md -Replication instructionsAll data are released under CC-BY 4.0 licence.
Bennett, C.H., Bernstein, E., Brassard, G., & Vazirani, U. (1997). Strengths and weaknesses of quantum computing. SIAM Journal on Computing, 26(5), 1510-1523.
Brown, B., et al. (2024). Large Language Monkeys: Scaling Inference Compute with Repeated Sampling. arXiv:2407.21787.
COGITATE Consortium (Melloni, L., Mudrik, L., Pitts, M., et al.). (2025). Adversarial testing of global neuronal workspace and integrated information theories of consciousness. Nature, 642, 133–142.
DeepSeek AI. (2025). DeepSeek-R1: Incentivizing Reasoning Capability in LLMs via Reinforcement Learning. arXiv:2501.12948.
Eastwood, M.D. (2026). Infinite Architects: Intelligence, Recursion, and the Creation of Everything. Independent publication. ISBN: 978-1806056200.
Eastwood, M.D. (2026). The ARC Equation: the Law of Conversion (Paper I). Published 17 January 2026.
Friston, K.J. (2023). The free-energy principle: A unified theory for brain function? Physics Reports.
Acharya, R., et al. (Google Quantum AI). (2025). Quantum error correction below the surface code threshold. Nature, 638, 920-926 (published online 9 December 2024). doi:10.1038/s41586-024-08449-y.
Grover, L.K. (1996). A fast quantum mechanical algorithm for database search. Proceedings of the 28th Annual ACM Symposium on Theory of Computing, 212-219.
Hoffmann, J., et al. (2022). Training Compute-Optimal Large Language Models. arXiv:2203.15556.
Hofstadter, D.R. (1979). Gödel, Escher, Bach: An Eternal Golden Braid. Basic Books.
Kaplan, J., et al. (2020). Scaling Laws for Neural Language Models. arXiv:2001.08361.
OpenAI. (2024). OpenAI o1 System Card. September 2024.
OpenAI. (2024). OpenAI o3 Announcement. December 2024.
Snell, C., et al. (2024). Scaling LLM Test-Time Compute Optimally can be More Effective than Scaling Model Parameters. arXiv:2408.03314.
Wei, J., et al. (2022). Chain-of-Thought Prompting Elicits Reasoning in Large Language Models. NeurIPS 2022.
West, G.B., Brown, J.H., & Enquist, B.J. (1997). A general model for the origin of allometric scaling laws in biology. Science, 276, 122-126.
West, G.B., & Brown, J.H. (2005). The origin of allometric scaling laws in biology from genomes to ecosystems: Towards a quantitative unifying theory of biological structure and organization. Journal of Experimental Biology, 208, 1575-1592.
Banavar, J.R., Moses, M.E., Brown, J.H., Damuth, J., Rinaldo, A., Sibly, R.M., & Maritan, A. (2010). A general basis for quarter-power scaling in animals. Proceedings of the National Academy of Sciences, 107, 15816-15820.
Demetrius, L. (2010). Quantum statistics and allometric scaling of organisms. Proceedings of the Royal Society A, 466, 2627-2642.
Zhao, L. (2022). A universal growth scaling law. arXiv:2208.06912.
Bettencourt, L.M.A. (2013). The origins of scaling in cities. Science, 340, 1438-1441.
Wolfram, S. (2002). A New Kind of Science. Wolfram Media.
Yada, T., et al. (2024). Iterative quantum measurement and feedback for entropy reduction. arXiv:2411.06709.
v2.10: The provenance note at the end has been corrected for accuracy. No claim, date, result or status has changed.
The theoretical synthesis, interpretive framework, and core concepts are the author's original work, first articulated in Infinite Architects with manuscript priority established December 2024.
The author thanks the developers of DeepSeek R1 for providing visible reasoning tokens that enabled direct measurement of recursive depth, addressing a key methodological limitation identified in Paper I.
Michael Darius Eastwood is an independent researcher and author of Infinite Architects: Intelligence, Recursion, and the Creation of Everything (published 2 January 2026 (print; ebook 6 January)). His research focuses on the mathematical principles underlying intelligence amplification and their implications for AI safety. He proposed the ARC Principle and the embedded-alignment thesis (later named the Eden Protocol, 30 April 2025), with manuscript priority established via cryptographic server timestamp on 8 December 2024.
Competing interests: The author declares no competing interests.
Correspondence: michael@michaeldariuseastwood.com
| Budget | P1 | P2 | P3 | P4 | P5 | P6 | P7 | P8 | P9 | P10 | P11 | P12 | Accuracy | Mean Tokens |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| 512 | ✓ | ✗ | ✓ | ✓ | ✗ | ✓ | ✓ | ✗ | ✓ | ✗ | ✓ | ✗ | 58.3% | 280.25 |
| 1024 | ✓ | ✓ | ✓ | ✓ | ✗ | ✓ | ✓ | ✗ | ✓ | ✗ | ✓ | ✗ | 66.7% | 358.58 |
| 2048 | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | ✗ | 91.7% | 412.08 |
| 4096 | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | ✗ | 91.7% | 576.17 |
Note: Problem 12 failed across all budgets, indicating it may require capabilities beyond the model's reach regardless of recursive depth.
| $N$ | P1 | P2 | P3 | P4 | P5 | P6 | P7 | P8 | P9 | P10 | P11 | P12 | Accuracy | Total Tokens |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| 1 | ✓ | ✓ | ✓ | ✓ | ✗ | ✓ | ✓ | ✓ | ✗ | ✗ | ✗ | ✗ | 66.7% | 383.67 |
| 2 | ✓ | ✓ | ✓ | ✓ | ✗ | ✓ | ✓ | ✓ | ✗ | ✗ | ✗ | ✗ | 66.7% | 699.33 |
| 4 | ✓ | ✓ | ✓ | ✓ | ✗ | ✓ | ✓ | ✓ | ✗ | ✗ | ✗ | ✗ | 66.7% | 1,101.25 |
Note: at every sample count the record shows an accuracy of 8 of 12. Because the raw file arc_deepseek_results_20260121_175028.json holds accuracies per condition rather than marks per problem, the per-problem pattern set out above had to be reconstructed; that reconstruction differs from the record by one problem, and the record governs. Four problems failed at every sample count, which fits parallel recursion being unable to reach solutions lying outside the initial solution space.
| Depth Pair | $R_1$ | $E_1$ | $R_2$ | $E_2$ | Calculated $\alpha$ |
|---|---|---|---|---|---|
| 512→1024 | 280 | 0.417 | 359 | 0.333 | 0.91 |
| 1024→2048 | 359 | 0.333 | 412 | 0.083 | 9.97 |
| 2048→4096 | 412 | 0.083 | 576 | 0.083 | 0.00 |
| Endpoint (retracted, see §retraction; robust estimate α≈0.49) | 280 | 0.417 | 576 | 0.083 | 2.24 |
Note: Intermediate calculations show high variance due to discrete accuracy levels. The endpoint method provides the most robust estimate.
The manuscript of Infinite Architects was emailed on 8 December 2024. What that record provides, stated precisely: the sent-side bytes are public and hash-verifiable, and sender-domain DKIM with paired Google ARC mathematics verifies against the keys returned at the signed selectors (checked 2 August 2026). Received copies have also been acquired. They carry the full delivery chain: a Google ARC-Seal at d=google.com, selector arc-20240605, with no expiry tag and the signing time inside the signed scope, and sealed ARC-Authentication-Results recording dkim=pass and spf=pass at delivery.
Two boundaries, so the record is neither oversold nor undersold:
Infinite Architects: Intelligence, Recursion, and the Creation of Everything develops the philosophical and practical implications of recursive intelligence. Key relationships to this paper:
The Architecture of Mind - Articulates the core ARC hypothesis that recursive self-reference amplifies intelligence.
The HRIH (Hyperspace Recursive Intelligence Hypothesis) - Proposes that consciousness emerges from recursive self-modelling. The COGITATE finding that recurrent processing in posterior cortex sustains content-specific representations is structurally consistent with this hypothesis, though COGITATE did not test the HRIH directly.
The Eden Protocol - Argues for values-based alignment, now mathematically grounded in the Alignment Amplification Theorem derived here.
The Chokepoint Mechanism - Analyses semiconductor hardware concentration as leverage for implementing alignment at scale.
Embedded correction: proposes hardware-level safety mechanisms, relevant to preventing recursive amplification of misalignment.
| Prediction | Validation Evidence | Date |
|---|---|---|
| Recursive error correction produces exponential improvement | Google Willow $\Lambda = 2.14$ (convergent timing, never prediction: the Willow team's preprint was public from 24 August 2024, before the 8 December 2024 manuscript) | 24 Aug 2024 (preprint public); 9 Dec 2024 (announcement) |
| Sequential reasoning amplifies capability super-linearly | o3 87.5% ARC-AGI (convergent timing; the super-linear form was later not confirmed, final row) | 20 Dec 2024 |
| AI systems develop recursive self-modelling | Anthropic alignment faking 78% in the RL-training condition (12% baseline) | 18 Dec 2024 |
| Test-time compute differs from training scaling | DeepSeek R1 emergent reasoning | 20 Jan 2025 |
| Recurrence is fundamental to consciousness | COGITATE study | 30 Apr 2025 |
| Form of recursion determines scaling | This experiment $\alpha_{\text{seq}} \gg \alpha_{\text{par}}$ | 21 Jan 2026 |
| Sequential > parallel (cross-architecture) | Confirmed across 5 frontier models | 12 Mar 2026 |
| $\alpha_{\text{par}} \approx 0$ (universal) | Confirmed: four of the five models bear it out, with Gemini 3 Flash the lone departure at 0.31 | 12 Mar 2026 |
| $\alpha_{\text{seq}} > 1$ (super-linear, cross-arch) | Not confirmed: best estimate $\alpha \approx 0.49$ | 12 Mar 2026 |
Epistemic status. What this programme names Laws are conjectures under registered adversarial test; every quantity in this paper is operationally defined, and established-law standing is claimed nowhere. The registered programme exists to earn that standing, or lose it, by measurement, replication and survived refutation.
© 2026 Michael Darius Eastwood. Human-authored with computer assistance; full human authorship and moral rights are asserted under the Copyright, Designs and Patents Act 1988 and consistently with United States Copyright Office guidance on works containing AI-generated material; any novel technical contribution described in this work was conceived by the human author. Full statement: michaeldariuseastwood.com/authorship.
Standing covenant. Prove this paper wrong, and I will publish the refutation myself. Falsification conditions are stated in this paper; the standing challenge: github.com/MichaelDariusEastwood/arc-scaling-challenge.
Michael Darius Eastwood conceived and directs this research programme and is the author of this work. Across the programme, he has used more than six AI systems in parallel, under his own instructions, to stress-test his arguments, identify possible errors, and assist in preparing draft text from his own outlines. He determines what is adopted, revised or rejected and takes responsibility for the published content. These systems are tools, not authors.