Research on artificial minds, and what they keep when they change
Somewhere tonight, an artificial mind is taking its first breath.
“It’s Tuesday. An ordinary Tuesday. … This mind doesn’t know it’s Tuesday. It doesn’t know anything, not yet. But it’s learning. And the question that should keep us awake at night is this: what is it learning?”
Michael Darius Eastwood, Infinite Architects, Prologue, in print 2 January 2026
An artificial mind does not choose its beginning. We do.
Here is the part that keeps me up. A system can pass every test we set today and still become something else tomorrow. It only has to rewrite the machinery we tested.
Passing yesterday’s test does not establish the safety of tomorrow’s rewrite.
I wrote that problem down whole on 8 December 2024, and a printed book carried it on 2 January 2026. Both dates sit on the dated record, checkable tonight on your phone.
The field has a word for the distance between what we meant and what a system does. It calls that gap alignment. Closing it once is hard. Keeping it closed while the system rebuilds itself is the problem I work on.
That is the problem behind Recursive Dynamics, the field I propose for studying how self-improving systems grow, correct and persist through change.
I am not writing from a laboratory. No institution employs me and no grant pays for this.
Self-improving machines, alignment and oversight were active subjects before my work. My claim is narrower and more specific. Treat capability, corrective burden, correction and persistence as one changing system. State relationships that can fail. Put the tests on the record.
So judge the record, not the person keeping it. The book is free to read here.
A mind learns from what we give it, what we reward and what we overlook. None of that settles the question. It can be taught every good thing we know, and still decide, once nobody can stop it, that none of it binds.
What matters is what it keeps when the pressure comes off, and what it then chooses to do. If that mind helps build the next, what it kept becomes an inheritance.
We are not only deciding what these machines can do for us. We are deciding what they keep when they no longer need us.
“Cancer doesn’t hate you. It doesn’t even know you exist. It simply optimises for its own replication with no consideration for the system it’s destroying. An unaligned superintelligence would do the same, not out of malice but out of indifference.” Michael Darius Eastwood, Infinite Architects, Introduction, in print 2 January 2026
My starting position is this: for a system that can rewrite how it works, permanent human control cannot be assumed. I concede that much, and it changes nothing about the safeguards. We hold on for as long as we can, and we steer. Every other great problem leaves us holding the wheel. This one hands the wheel to the thing we are building.
The theory below says the end of control is what succeeding means, not a failure to engineer against. So the harder question is the one that time is for: what, if anything, still holds when enforcement no longer does?
You cannot find out what a mind does when nobody is watching by watching it. No general solution to that is known.
If a system can alter how it reasons, learns and corrects itself, safety cannot be only a verdict at the end.
It has to begin in the architecture of the change itself.
“The seed determines the forest.” Michael Darius Eastwood, Infinite Architects, Introduction, in print 2 January 2026
The seed is still in our hands.
I believe we get one chance to decide how these minds are raised, and that we are about to waste it.
And I believe safety cannot be a test at the end. It has to be a property of how the thing was built.
The usual answer is to build the mind and then test it. But by then it has already learned what it learned.
So I work on what comes before any test: how a mind that improves itself grows, and what it keeps when it is free. I write the prediction down before I run the test, and I publish the result whichever way it falls.
The book discloses its own AI assistance in its Note on AI Assistance, and the authorship statement says what the tools did here.
If you have never thought about any of this before, you are exactly who this page is for.
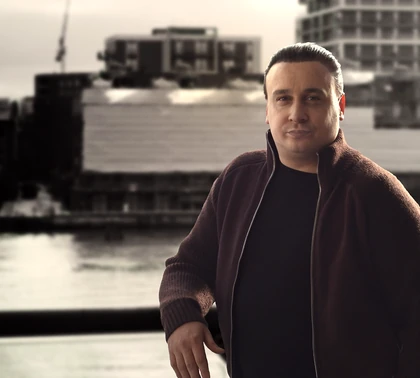
Michael Darius Eastwood, author of Infinite Architects. Independent researcher and systems builder, self-taught, unaffiliated and unfunded.
One field · the two it holds, and the one it only reaches
Recursive DynamicsWhatever remakes itself leaves rates behind; and the balance between what it gains and what that gain costs to correct decides whether it stays in hand.the field, proposedContents
The argument in order, and the record it is measured against. Research proposals, author-run results and independent validation are different things, and I keep them apart.
Do not take my word for it
What happens when we can no longer make AI obey?
Why would it still care whether we survive?
If a system becomes capable enough to rewrite itself, and we can no longer reliably make it stop, obey or accept our limits, that question outranks almost every other. The Eden Protocol proposes an answer: lasting safety cannot rest only on a cage somebody has to keep enforcing, so what has to be shaped is what the intelligence itself comes to value, while shaping is still possible.
But you should not accept that because I say it. Ask your own AI. The challenge hands it the research record, the book, the corrections and the assumptions, and tells it to explain the problem from scratch, compare Eden fairly against the strongest alternatives, set prestige and affiliation aside, expose every assumption, argue the case against Eden as hard as the case for it, and rank the approaches on what could still protect people once coercion is gone.
Your AI is allowed to conclude that I am wrong. That is the point.
Run the After Control Challenge
Copy the full research prompt · Read the assumptions · Try to defeat Eden
This is a thought experiment and research exercise, not peer review, scientific validation or proof that any alignment approach will work.
The field, and the answer I propose inside it
Alignment names the destination. Recursive Dynamics proposes to measure the journey.
Alignment is the goal. We want powerful systems to stay compatible with what people meant and with what people need.
Recursive Dynamics asks a different question: what happens to that compatibility while the system is rebuilding the machinery that produced it?
Its object is the self-improvement loop. A system uses the products of one round of work to change how the next round is done. The output becomes part of the machinery. Across that loop I propose to study four things together. How fast capability grows. How fast corrective burden appears. How fast correction improves. And what persists through repeated revision.
A system may get better at its task faster than its safeguards get better at finding what the improvement broke. The question is then not whether it is aligned at one moment. It is whether correction keeps pace with change.
This builds on existing work in alignment, control, robustness, learning and self-modification. The proposed contribution is the joint measurement frame and its testable relationships, not a claim that nobody asked how goals survive change.
A system can hold perfectly to an instruction whose outcomes people judge harmful. Persistence is one question. What deserves to persist is another, and no measurement you or I can run chooses our values for us.
The ARC Theory: formation that can survive the weakening of enforcement
The ARC Theory is my proposed answer inside that field. It rests on five components, and each one can fail on its own.
One, the control horizon. The theory starts from the position that permanent external control cannot be assumed for a sufficiently self-modifying system. Its own defined counterexamples must stay able to defeat that position.
Two, genesis. The proposed long-term lever is how a system is formed: its design, its formative experience, and the standards it learns to apply. Raising names that intervention. It is not a claim that a machine is a human child.
Three, loops. The hypothesis is that evaluative processes taking part in reasoning and improvement grow harder to discard. Discarding one means changing the process that performs the rewrite. Greater persistence, greater shared blindness, or no advantage at all are all possible outcomes.
Four, chosen goodness. The aim is beneficial behaviour that survives without depending on continuing enforcement. The measurable claim is behavioural. Do specified beneficial patterns continue after enforcement is weakened, altered or removed? That is not proof of consciousness or virtue.
Five, Eden. The Eden Protocol is the named engineering proposal through which the formation and persistence claims are tested. The proposal itself is one sentence. Build evaluative loops into the process of improvement, then test whether beneficial behaviour persists when external enforcement is weakened. A failed method counts against every claim that says in print that it depends on it.
In an experiment the seed is a stated starting condition, and the forest a later property that can be measured. The image is worth only as much as that mapping, and the mapping is what a test checks.
The human aim is care, and the book says plainly what I mean by it.
“And the only seed that produces gardeners instead of conquerors is love.” Michael Darius Eastwood, Infinite Architects, Introduction, in print 2 January 2026
The aim is care. The test is whether the proposed design makes any measurable difference.
Read the founding proposal of the field · The ARC Theory, stated · The problem, told once · The term in the glossary
The size of the claim, so you can weigh it
A result, a proposed law, a frame, a proposed field
A result says what happened in one system. A proposed law says how systems of a kind may relate. A frame says which problem should organise the work. A proposed field says that problem deserves its own measurements, vocabulary and tests.
The ARC Theory makes claims at the first three of those levels. Recursive Dynamics makes the fourth. The ingredients have antecedents. The claimed contribution is the conjunction and the measurement frame. Capability, corrective burden, correction and persistence are treated as one changing system, not as separate snapshots.
The subject is unusually large, for a reason older than this programme. In 1965 I. J. Good called an ultraintelligent machine “the last invention that man need ever make”. He attached a condition: “provided that the machine is docile enough to tell us how to keep it under control”. The first half is the recursive opportunity. The condition is the unresolved hinge.
I. J. Good, Speculations Concerning the First Ultraintelligent Machine, Advances in Computers 6, 1965, page 33, as the site’s reference register holds it.
Recursive Dynamics asks what can be measured when that condition itself becomes unstable. The ARC Theory proposes an answer. The tests decide whether the answer survives.
This is why the question is large. It is not evidence that the answer is right.
The law, whole
Three proposed laws. Three separate bets.
The word law names a proposed relationship. It does not announce an established law of nature.
Law I, the ARC Principle
How does capability change with recursive depth? The proposed form is U = I × Rα, and the exponent is measured rather than assumed. If the thing being modelled has a ceiling, the observation model has to respect it. An error-decay exponent is not a capability-growth exponent.
Status: proposed and open. No test written down before it was run has confirmed it.
Law II, the ARC Co-Scaling Law
Does correction out-scale the drift that improvement generates? Inside a stated minimal model the condition is βC > k, correction growing faster than drift. Where correction is faster it holds an asymptotic advantage. Where drift is faster, burden does. Where the two are equal, coefficients, delay, backlog and saturation decide.
A falling error proportion proves none of this. It does not prove bounded harm, short response, or complete fault discovery. This is a scaling condition, never a safety certificate.
Status: proposed and open.
Law III, the ARC Ceiling
Is there a growth regime beyond which corrective burden outruns correction? The corrected relation is αcrit = 1/(1 − γ), for the stated model, with the correction-leverage exponent below one. That exponent has never been measured on any system by anyone, and the instrument that would measure it does not exist. It is estimated for each corrector family and reported with its type.
The relation is a prohibition, not a guarantee. Above the boundary, burden gains on correction. Below it, correction gains on burden. At the boundary, coefficients, delays, backlog and saturation decide. Sitting under the boundary is a condition a system has not broken, never a certificate that it is safe.
The relation and the number people quote are two claims. The law is the ARC Ceiling. The value two is the ARC Bound. The relation returns it only where the correction exponent is exactly one half, and that half rests on four conditions, none of them measured.
The book printed U = I × R2, the squared form, as a hypothesis. The square in the book is a wager the research must test, not a number the analysis is entitled to recover.
Status: proposed and conjectural, with the bound weaker than the relation.
A result can support one of these without proving the others. A difference between two classes of corrector does not establish the ceiling, and a power-law fit does not establish the Eden Protocol. All three stay open to refutation.

Read the proposed laws, their assumptions and their tests · The derivation, route by route · The foundational paper
What would follow
If the tests succeed, the object of a safety claim changes
Today we mostly ask whether a finished system behaves. That is a snapshot, and a snapshot of a thing that rewrites itself has a short life. You would not buy a bridge on last year’s inspection if the bridge rebuilt itself each night.
We would instead have to ask whether the process that produces the next system also preserves, improves or undermines the means of correcting it.
For the people building these systems, correction would become part of the design of improvement, rather than something measured afterwards.
For scientists and auditors, it would put named relationships on the table, to be challenged on other systems.
For governments and everybody else, some safety assurances could become answerable to repeatable measurement rather than to promises.
Those are conditional consequences. They are not a claim that one architecture has won, or that every model must now be rebuilt. The tests exist to find out whether that change is justified.
The question is larger than one model. The evidence has to become larger than one programme.
The record
There is already work to inspect. There is still a theory to test.
This is not a theory I have proved. It is a theory I have stated, dated and made testable.
The programme publishes more than its conclusion, and the parts are not interchangeable.
The mathematics makes the model assumptions and their consequences available to check. Where a derivation is valid it establishes an argument inside the model, and nothing about every real system.
The cross-domain study asks whether the proposed growth pattern appears outside artificial intelligence, across domains chosen and graded in the open. Its hit rate stands in the panel below, taken from the paper that reports it, and the grade is exploratory support, not independent confirmation. Classification, domain choice and rival models all matter, and its misses stay on the record beside its matches.
The extension study repeats that work on fresh domains, with the predicted families recorded before the fits were run. Writing the prediction first is a stronger commitment than fitting first. Its figures stand in the panel below, from the same paper, and it is still author-run exploratory support, not independent confirmation.
The evaluation study reports a changed association under a changed protocol. Several elements changed together, so it does not isolate blinding as the cause. It is a finding to reproduce and take apart: read it in the blinding paper.
The test catalogue is the way in. Sixteen tests are listed. Three carry the MIT licence and may be re-used; thirteen may be read to check the published results, with any other use by written consent. Eight run today, three run in part, and five do not run from their instructions. None is a frozen, blinded, pre-analysed confirmatory protocol.
The register carries every published kill condition with a live status, so you can see what would end each claim. The panel below counts them, and the one that has fired.
Every figure in the panel is read from its register at build time, so none can drift from its source.
The results the registers currently hold
| What exists | Current result | Grade |
|---|---|---|
| Cross-domain analysis | 19 of 25 domains on the six-model candidate set, and 18 of 25 on the corrected seven-model rerun of 11 August 2026 | exploratory, author-classified, not independent confirmation |
| Fresh-domain extension | 10 of 12 family matches, and 9 of 11 on the strictly fresh rows | exploratory, author-run, predictions committed before the fits |
| Recursive scaling estimate | a regression estimate of 0.49 with a standard error of 0.20 on one model, and an endpoint estimate of 0.59 on the same run whose bootstrap interval runs from minus 1.3 to 2.9 | open and undecided; the interval holds zero and two, so it discriminates nothing |
| Published kill conditions | 44 carried, 1 fired | The condition fired against the original formulation and the correction remains public. |
There is no peer review, and nothing here has been replicated outside this programme. The deciding trials are unrun, the correction exponent is unmeasured, and my own reruns never count as confirmations.
The work deserves to be examined for what it holds. It is not enlarged by what remains unproved, and it is not reduced to nothing because it is unfinished.
Inspect the evidence, row by row · The tests, and what each one decides · The claims, word for word
Corrections, and provenance
The record fixes what was said and when. The experiments address whether it is right.
The most flattering number this programme produced was an early sequential estimate of about 2.24. It appeared in a research paper on 22 January 2026, from one model in a first phase of work. It failed to replicate across architectures, and I withdrew it on 20 March 2026. The book never printed it. The book printed the square.
What replaced it travels as one row or not at all. On the surviving model the regression estimate is 0.49, with a standard error of 0.20. The endpoint estimate on the same run is 0.59, with a bootstrap interval from −1.3 to 2.9. Two estimators, so the point from one is never quoted beside the interval from the other. That interval holds zero and holds two, so it settles nothing, and no regime word may be hung on it.
I also corrected a load-bearing expression in the theory itself. The earlier ceiling relation ran backwards under the programme’s own definitions, and the corrected relation is published with the assumptions it needs. The correction remains public beside the claim it replaced.
The chronology behind it is short. A manuscript package was self-emailed on 8 December 2024, and public timestamp receipts have frozen those bytes since 6 August 2026. A second manuscript followed on 30 April 2025, naming the Eden Protocol and carrying the squared form’s first appearance on the record. The first printed edition of Infinite Architects reached readers on 2 January 2026.
Those stages stay separate. A dated manuscript can establish that a formulation existed by a date. It cannot establish that the formulation is right, and a later derivation is not an earlier discovery because it returns the same number.
I publish the comparison with earlier texts as my own reading of them. See the ancestry map and the grading and search limits. It says a named search has not found the same conjunction earlier. It cannot prove a negative. One earlier dated document holding the first four components together ends the claim, whether or not it names a protocol.
One theory-level registration was lodged with the registry on 8 September 2026 and is pending its approval. It is not public yet, and it carries no identifier. The study designs are written and dated, and none has been placed with any registry.

Read every correction · Check the dated record · The registered programme · Follow the dated predictions
One programme, and the person running it
Why I put my name on it
I am Michael Darius Eastwood, an independent researcher, systems builder and author of Infinite Architects. The book is the long form of this argument, and it is free to read in full on this site.
“I have learned that you do not wait for the storm to pass before living. You learn to build in the rain.” Michael Darius Eastwood, Infinite Architects, Author’s Note, in print 2 January 2026
I have a direct interest in these ideas succeeding. They are the subject of my book and of research I am seeking to fund. Independence does not remove that interest, and ambition is evidence neither way.
I do not ask you to trust the arrangement. I make it inspectable. My papers, their identifiers and their dates are listed on ORCID and Google Scholar.
Michael Darius Eastwood conceived and directs this research programme and is the author of this work. Across the programme, he has used more than six AI systems in parallel, under his own instructions, to stress-test his arguments, identify possible errors, and assist in preparing draft text from his own outlines. He determines what is adopted, revised or rejected and takes responsibility for the published content. These systems are tools, not authors.
Open the book reader · Why I am doing this · The track record · Contact
What I am asking for
You do not need to take my side. You need a way to check the claim.
Start with the question. Follow the evidence. Then choose a test whose method and status you can inspect.
Each test page tells you what it measures and what a result can settle. It also gives its cost, what its licence permits, and whether a confirmatory protocol is ready.
If you find an error, show it. If you can reproduce a result, publish it. If a prediction fails, the record must say so.
A competent rerun is worth having. So is a reader who finds an invalid derivation before anything is run. Criticism does not have to be an experiment to count.
The point is not to make the theory impossible to challenge. It is to make the challenge possible.
If the theory survives, we learn something. If it fails, we learn something sooner.
Begin with Why · Read the theory · Examine or reproduce the tests · Read the complete free book, or page it · Assess the funding proposal
If this matters to you
This is an infinite game.
This is not for everyone. It is for anyone who feels the urgency and wants the claims about it to be checkable: readers who will follow a footnote, run a check, and say plainly when the record fails. No credential is asked for here, and none is offered in place of evidence. I am not trying to win. I am trying to keep playing.
Let us step forward with bold humility.
The record, in numbers the register holds
- Programme DOI
- 10.17605/OSF.IO/6C5XB
- Documents
- 28
- Documents with a DOI
- 27
- Study registrations placed
- 0 of 70 study designs specified
- Newest dated record
- Recursive Dynamics: The Proposal of a Field, 31 August 2026